DOWNLOAD the newest itPass4sure DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Ge37TW9VuIbrf3vCAHu70-w8Xy-bOLpy
Generally speaking, passing the exam is what the candidates wish. Our DP-100 exam braindumps can help you pass the exam just one time. And in this way, your effort and time spend on the practicing will be rewarded. DP-100 training materials offer you free update for one year, so that you can know the latest information for the exam timely. In addition, DP-100 Exam Dumps cover most of the knowledge point for the exam, and you can pass the exam as well as improve your ability in the process of learning. Online and offline chat service is available for DP-100 learning materials, if you have any questions for DP-100 exam dumps, you can have a chat with us.
| Section | Weight | Objectives |
|---|---|---|
| Prepare a model for deployment | 20-25% | - Manage deployment assets
|
| Design and prepare a machine learning solution | 20-25% | - Prepare development environments
|
| Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
| Explore data and train models | 35-40% | - Optimize model performance
|
If moving up in the fast-paced technological world is your objective, Microsoft is here to help. The excellent Designing and Implementing a Data Science Solution on Azure (DP-100) practice exam from Microsoft can help you realize your goal of passing the Microsoft Treasury with Designing and Implementing a Data Science Solution on Azure (DP-100) certification exam on your very first attempt. Most people find it difficult to find excellent Microsoft Treasury with Designing and Implementing a Data Science Solution on Azure (DP-100) exam dumps that can help them prepare for the actual Designing and Implementing a Data Science Solution on Azure (DP-100) exam.
NEW QUESTION # 383
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are analyzing a numerical dataset which contain missing values in several columns.
You must clean the missing values using an appropriate operation without affecting the dimensionality of the feature set.
You need to analyze a full dataset to include all values.
Solution: Use the last Observation Carried Forward (IOCF) method to impute the missing data points.
Does the solution meet the goal?
Answer: B
Explanation:
Instead use the Multiple Imputation by Chained Equations (MICE) method.
Replace using MICE: For each missing value, this option assigns a new value, which is calculated by using a method described in the statistical literature as "Multivariate Imputation using Chained Equations" or
"Multiple Imputation by Chained Equations". With a multiple imputation method, each variable with missing data is modeled conditionally using the other variables in the data before filling in the missing values.
Note: Last observation carried forward (LOCF) is a method of imputing missing data in longitudinal studies.
If a person drops out of a study before it ends, then his or her last observed score on the dependent variable is used for all subsequent (i.e., missing) observation points. LOCF is used to maintain the sample size and to reduce the bias caused by the attrition of participants in a study.
References:
https://methods.sagepub.com/reference/encyc-of-research-design/n211.xml
https://www.ncbi.nlm.nih.gov/pmc/articles/PMC3074241/
NEW QUESTION # 384
You register the following versions of a model.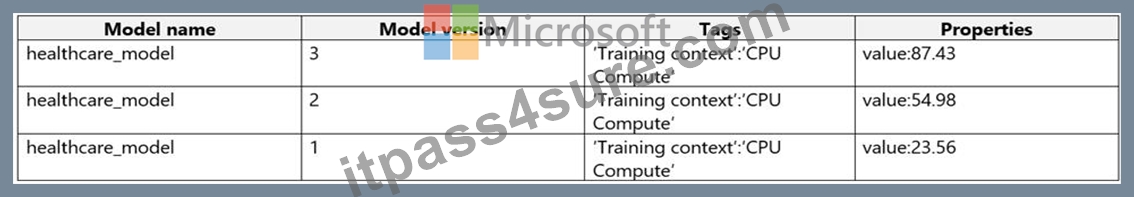
You use the Azure ML Python SDK to run a training experiment. You use a variable named run to reference the experiment run.
After the run has been submitted and completed, you run the following code: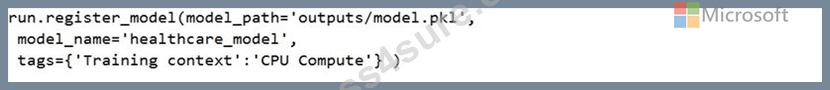
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.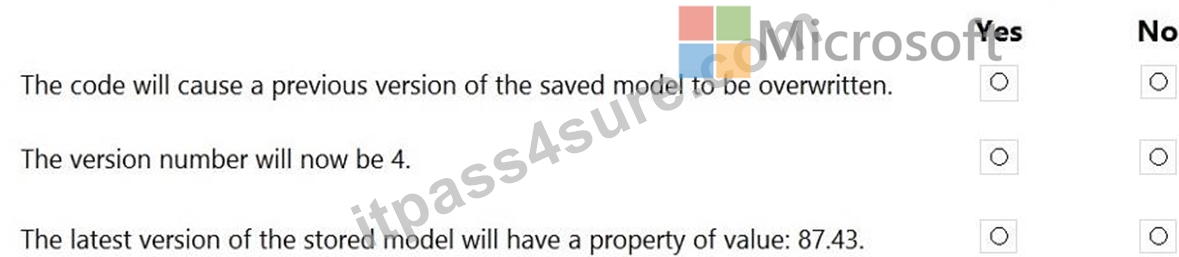
Answer:
Explanation: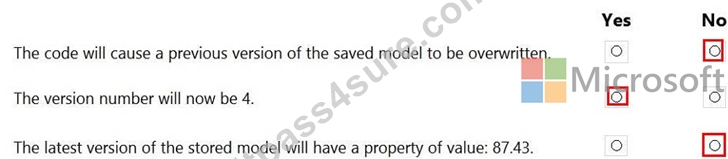
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-deploy-and-where
NEW QUESTION # 385
A biomedical research company plans to enroll people in an experimental medical treatment trial.
You create and train a binary classification model to support selection and admission of patients to the trial.
The model includes the following features: Age, Gender, and Ethnicity.
The model returns different performance metrics for people from different ethnic groups.
You need to use Fairlearn to mitigate and minimize disparities for each category in the Ethnicity feature.
Which technique and constraint should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.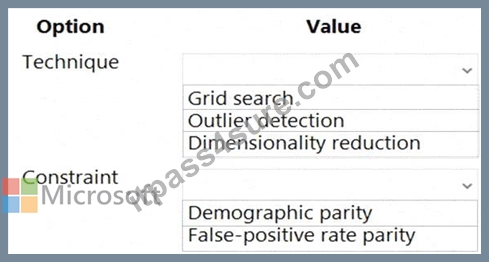
Answer:
Explanation: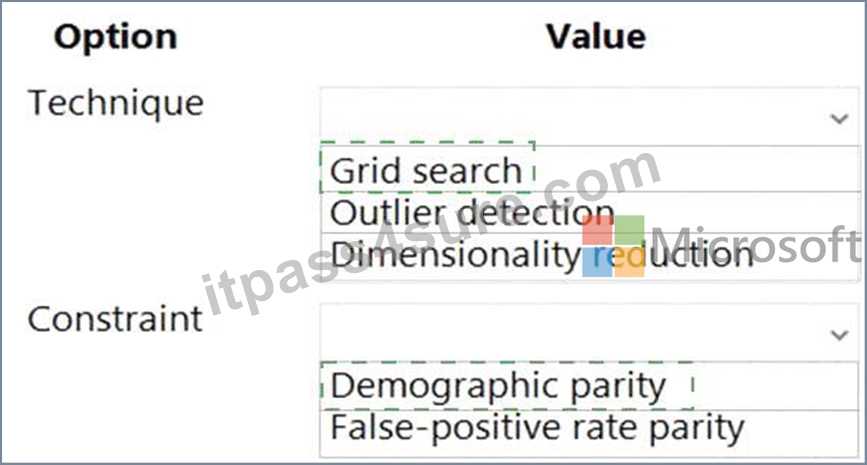
Explanation: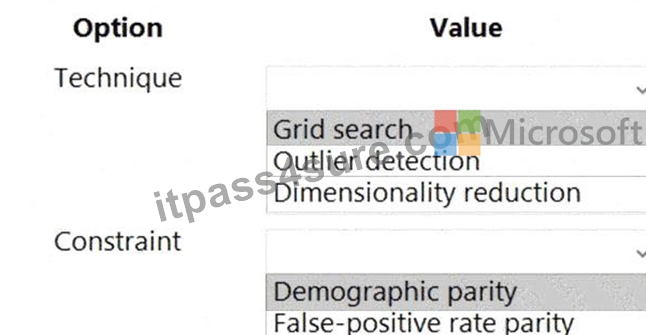
Box 1: Grid Search
Fairlearn open-source package provides postprocessing and reduction unfairness mitigation algorithms:
ExponentiatedGradient, GridSearch, and ThresholdOptimizer.
Note: The Fairlearn open-source package provides postprocessing and reduction unfairness mitigation algorithms types:
Reduction: These algorithms take a standard black-box machine learning estimator (e.g., a LightGBM model) and generate a set of retrained models using a sequence of re-weighted training datasets.
Post-processing: These algorithms take an existing classifier and the sensitive feature as input.
Box 2: Demographic parity
The Fairlearn open-source package supports the following types of parity constraints: Demographic parity, Equalized odds, Equal opportunity, and Bounded group loss.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-fairness-ml
NEW QUESTION # 386
You create a new Azure Machine Learning workspace with a compute cluster.
You need to create the compute cluster asynchronously by using the Azure Machine Learning Python SDK v2.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point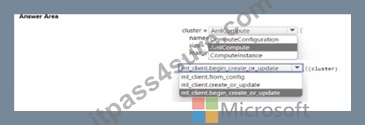
Answer:
Explanation: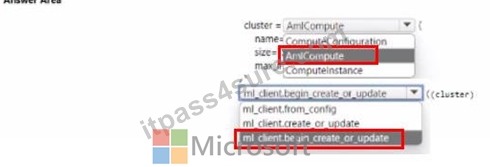
NEW QUESTION # 387
You use the Azure Machine Learning designer to create and run a training pipeline. You then create a real-time inference pipeline.
You must deploy the real-time inference pipeline as a web service.
What must you do before you deploy the real-time inference pipeline?
Answer: B
Explanation:
You need to create an inferencing cluster.
Deploy the real-time endpoint
After your AKS service has finished provisioning, return to the real-time inferencing pipeline to complete deployment.
Select Deploy above the canvas.
Select Deploy new real-time endpoint.
Select the AKS cluster you created.
Select Deploy.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-designer-automobile-price-deploy
NEW QUESTION # 388
......
The itPass4sure guarantees their customers that if they have prepared with Designing and Implementing a Data Science Solution on Azure (DP-100) practice test, they can pass the Designing and Implementing a Data Science Solution on Azure (DP-100) certification easily. If the applicants fail to do it, they can claim their payment back according to the terms and conditions. Many candidates have prepared from the actual Microsoft DP-100 Practice Questions and rated them as the best to study for the examination and pass it in a single try with the best score. The Microsoft DP-100 practice material of itPass4sure came into existence after consultation with many professionals and getting their positive reviews.
DP-100 Frequent Updates: https://www.itpass4sure.com/DP-100-practice-exam.html
BONUS!!! Download part of itPass4sure DP-100 dumps for free: https://drive.google.com/open?id=1Ge37TW9VuIbrf3vCAHu70-w8Xy-bOLpy