ちなみに、Jpshiken dbt-Analytics-Engineeringの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1_zu3wRxDZRn7Oj78PFoCIoePnclf16eI
多種多様なユーザーのニーズを促進するために、dbt-Analytics-Engineeringスタディガイドでは、現在最高の適用率を持つ3つのモデル(PDF、ソフトウェア、オンライン)を開発しました。別の名前のオンラインモードは、学習教材のアプリです。ブラウザ上のユーザー端末が、この学習モデルの教材をシミュレートするdbt-Analytics-Engineeringによって適用されたアプリケーションを実現できる限り、Webブラウザーに基づいて開発されます、ユーザーはアプリのリンクを開くだけで済み、dbt-Analytics-Engineering学習教材の方法で学習コンテンツをリアルタイムですばやく開くことができます。
| Section | Objectives |
|---|---|
| Topic 1: Testing and Data Quality | - Built-in and custom tests
|
| Topic 2: Documentation and Lineage | - dbt documentation system
|
| Topic 3: dbt Core Concepts | - Models and materializations
|
| Topic 4: Deployment and Orchestration | - Environments and workflows
|
| Topic 5: Analytics Engineering Foundations | - SQL proficiency for analytics
|
>> dbt-Analytics-Engineeringテスト難易度 <<
自宅にいても外にいても、dbt-Analytics-Engineeringテストトレントを勉強できます。 dbt-Analytics-Engineering学習ツールの指導の下では、試験の準備に20〜30時間しかかからないため、他にやることがあるので、時間を心配する必要はありません。 dbt-Analytics-Engineering試験資料を使用して、独自に学習できます。毎日多くの時間を費やす必要はなく、試験に合格し、最終的には証明書を取得します。 dbt-Analytics-Engineering認定は、就職面接の重要なタグになる可能性があり、他の人よりも競争上の優位性があります。
質問 # 28
Examine the code:
select
left(customers.id, 12) as customer_id,
customers.name as customer_name,
case when employees.employee_id is not null then true else false end as is_employee, event_signups.event_name, event_signups.event_date, sum(case when visit_accomodations.type = 'hotel' then 1 end)::boolean as booked_hotel, sum(case when visit_accomodations.type = 'car' then 1 end)::boolean as booked_ride from customers
-- one customer can sign up for many events
left join event_signups
on left(customers.id, 12) = event_signups.customer_id
-- an event signup for a single customer can have many types of accommodations booked left join visit_accomodations on event_signups.signup_id = visit_accomodations.signup_id and left(customers.id, 12) = visit_accomodations.customer_id
-- an employee can be a customer
left join employees
on left(customers.id, 12) = employees.customer_id
group by 1, 2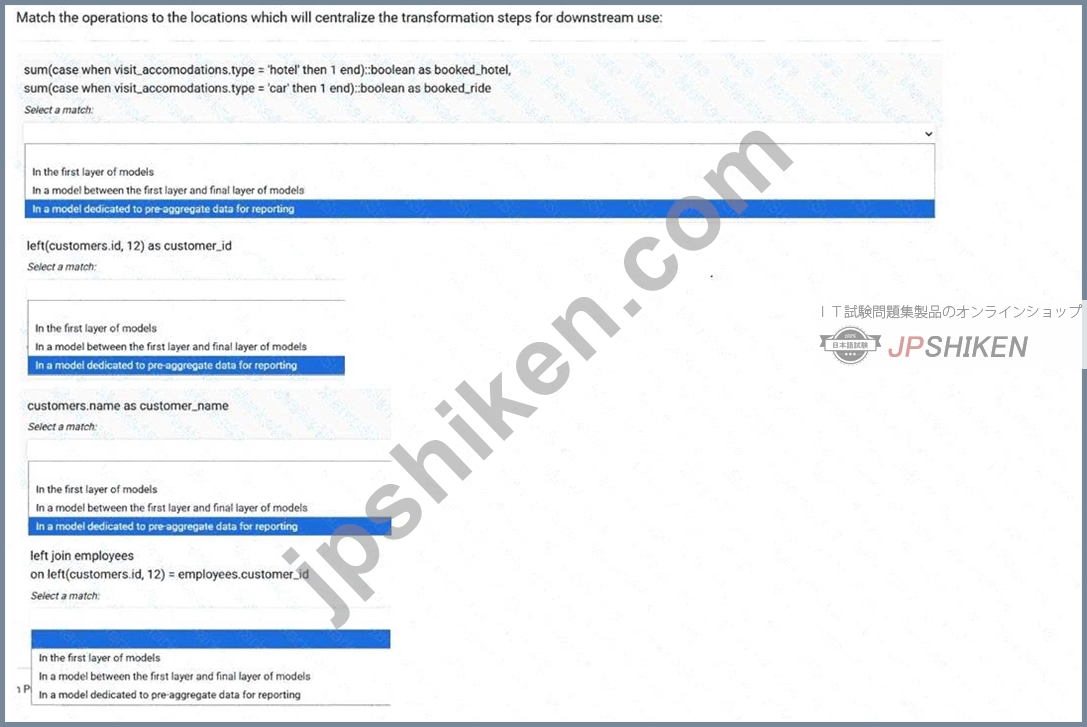
正解:
解説: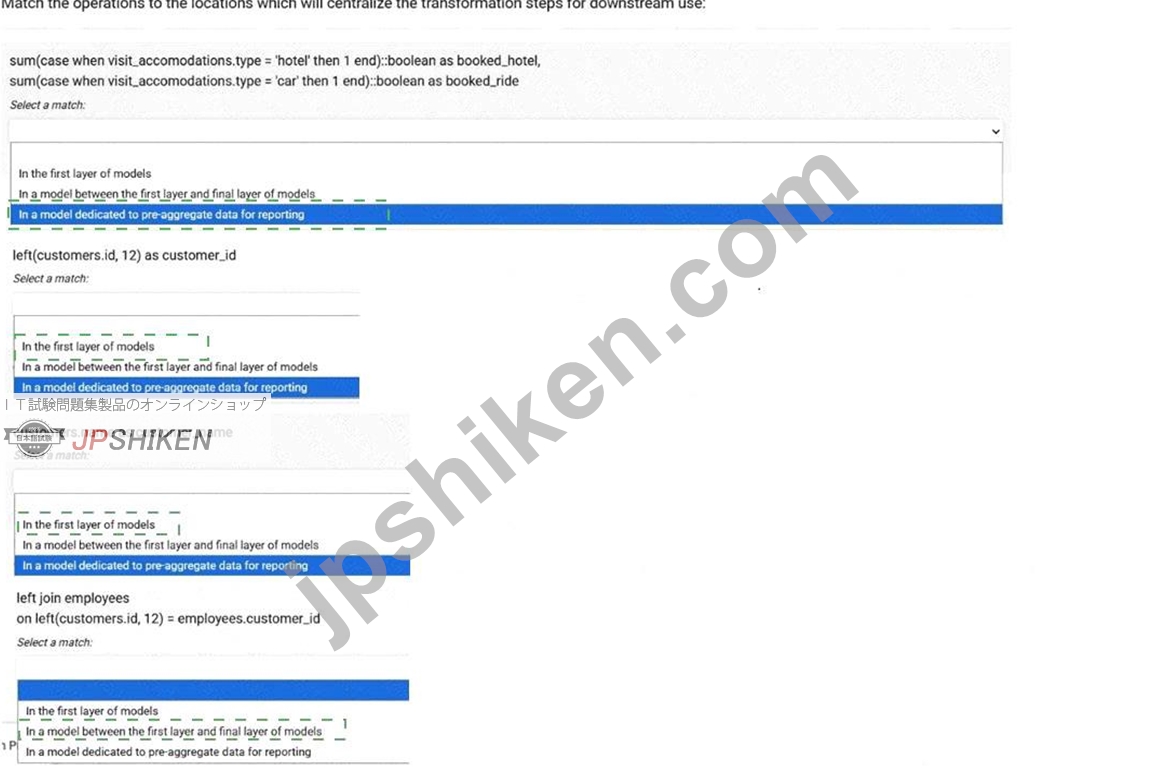
Explanation:
Operation
Correct Location
Aggregations (booked_hotel, booked_ride)
In a model dedicated to pre-aggregate data for reporting
Standardizing customer_id
In the first layer of models
Selecting customer_name
In the first layer of models
Joining employees
In a model between the first layer and final layer of models
In dbt's recommended modeling framework, transformations should be centralized according to their purpose and level of abstraction. Basic cleaning and column standardization-such as shortening customers.id using left(customers.id, 12)-belongs in the first layer of models, commonly known as staging models. This layer is responsible for producing clean, consistent, analytics-ready fields. Selecting raw descriptive fields like customers.name also belongs in this layer.
Joins that enrich a dataset by combining cleaned staging outputs across domains-such as joining customers with employees-belong in intermediate models. These models unify business logic that sits between the raw staging layer and the final aggregations used for reporting.
Finally, aggregations like counting types of accommodations (booked_hotel and booked_ride) belong in marts or reporting models, especially when they involve summarization that downstream tools (dashboards, BI reports) will consume. This keeps heavy business logic centralized and reusable.
質問 # 29
Which explanation describes how dbt infers dependencies between models?
Choose 1 option.
正解:A
解説:
The correct answer is A: Information is gathered from the use of source and ref macros.
dbt determines the dependency graph - the DAG - by analyzing calls to ref() and source() inside model SQL files. These macros explicitly declare relationships between models. When a developer writes ref ('orders'), dbt interprets this as: "the current model depends on the orders model." Similarly, source() indicates dependencies on upstream raw data sources. This declarative approach allows dbt to build a structured and deterministic DAG without scanning SQL for implicit table references.
Option B is incorrect because dbt does not query database objects to infer dependencies; it resolves dependencies at compile time through metadata generated from model files. Option C is incorrect because dbt intentionally does not parse SQL to detect table names-this would be brittle and error-prone across warehouses. Instead, dbt requires explicit references to maintain reliability. Option D is incorrect because YAML files define metadata about models and sources but do not create dependency relationships between them.
Thus, the dependency graph is built exclusively by reading ref() and source() macro calls, which ensures clarity, correctness, and maintainability within the analytics engineering workflow.
質問 # 30
Your team follows a convention where commit messages include a relevant issue tracker reference (e.g., JIRA- 123). You've been working on multiple features and fixes. Which of the following best promotes clean commits?
正解:A
解説:
Atomic commits focus on a single change, making history easier to understand. Referencing relevant issues creates a link between code changes and project tasks.
質問 # 31
You frequently need to implement custom SQL tests that are very similar but with slight variations in parameters. Which dbt feature could streamline this process?
正解:C
解説:
Macros are ideal for parameterizing reusable test logic, making it easy to adapt the tests without excessive copy-pasting.
質問 # 32
You're setting up a new dbt project on a recently provisioned data warehouse. What actions are essential before your initial development begins?
正解:B
解説:
A: Organization is key for maintainability and collaboration. B: Secure access is fundamental from the outset C: Visibility into job execution and resource usage is crucial.
質問 # 33
......
IT認定試験の中でどんな試験を受けても、Jpshikenのdbt-Analytics-Engineering試験参考資料はあなたに大きなヘルプを与えることができます。それは Jpshikenのdbt-Analytics-Engineering問題集には実際の試験に出題される可能性がある問題をすべて含んでいて、しかもあなたをよりよく問題を理解させるように詳しい解析を与えますから。真剣にJpshikenのdbt Labs dbt-Analytics-Engineering問題集を勉強する限り、受験したい試験に楽に合格することができるということです。
dbt-Analytics-Engineering受験トレーリング: https://www.jpshiken.com/dbt-Analytics-Engineering_shiken.html
BONUS!!! Jpshiken dbt-Analytics-Engineeringダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1_zu3wRxDZRn7Oj78PFoCIoePnclf16eI