The aim of VCEEngine is help every candidates getting Databricks certification easily and quickly. Comparing to attending expensive training institution, Databricks-Certified-Data-Engineer-Professional dumps pdf is more suitable for people who are eager to passing actual test but no time and energy. If you decide to join us, you will receive valid Databricks-Certified-Data-Engineer-Professional learning study materials with real questions and detailed explanations.
| Section | Weight | Objectives |
|---|---|---|
| Data Processing | 28% | - ETL Pipelines - Spark SQL - Data Transformation - Structured Streaming |
| Databricks Lakehouse Platform | 24% | - Unity Catalog - Lakehouse Architecture - Data Management - Delta Lake |
| Data Quality and Governance | 12% | - Data Lineage - Data Quality - Governance |
| Data Modeling and Storage | 20% | - Data Modeling - Storage Optimization - File Formats |
| Monitoring and Troubleshooting | 16% | - Monitoring - Performance Optimization - Troubleshooting |
>> Databricks-Certified-Data-Engineer-Professional Exam Guide Materials <<
The PDF version of the VCEEngine Databricks Databricks-Certified-Data-Engineer-Professional prep material is easily accessible. This format is ideal for someone who is constantly on the move, as you can prepare for your Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam whether you are using your smartphone, tablet, or laptop. You can study anywhere, at any time, without having to worry about installing anything. Furthermore, you can study with a hard copy by printing all of your Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) PDF questions. We offer regular updates in PDF format to improve Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) questions according to changes in the exam.
NEW QUESTION # 31
A Data Engineer is building a simple data pipeline using Lakeflow Declarative Pipelines (LDP) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create Lakeflow Declarative Pipelines that read the raw JSON data and write it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using LDP?
Answer: A
Explanation:
The correct method to define a table using Lakeflow Declarative Pipelines (LDP) is with the
@dlt.table decorator, which persists the output as a managed Delta table. When ingesting raw JSON data, spark.read.json() or spark.read.format("json").load() is the standard approach. This reads JSON- formatted files from the source and stores them in Delta format automatically managed by Databricks.
NEW QUESTION # 32
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer s suggestion is correct?
Answer: A
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 33
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays.
Which limitation will the team face while diagnosing this problem?
Answer: A
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
NEW QUESTION # 34
The data engineering team maintains the following code: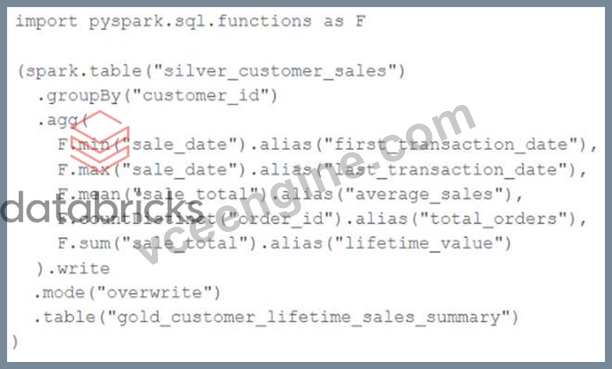
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: C
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 35
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.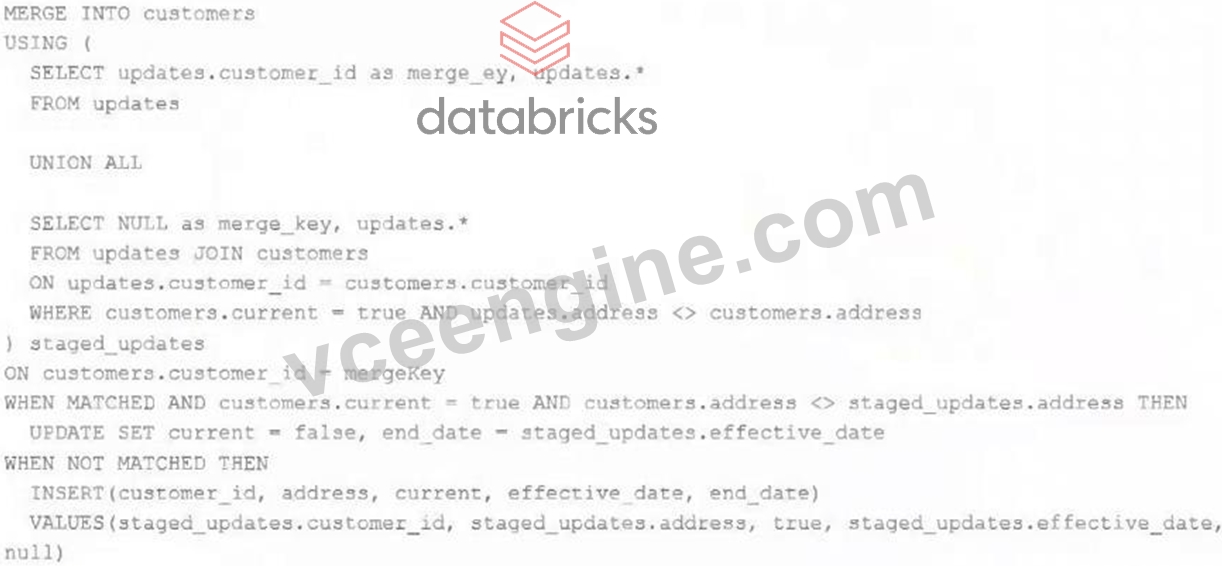
Which statement describes this implementation?
Answer: A
NEW QUESTION # 36
......
Studying from an updated practice material is necessary to get success in the Databricks Databricks-Certified-Data-Engineer-Professional certification test on the first try. If you don't adopt this strategy, you will not be able to clear the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) examination. Failure in the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) test will lead to loss of confidence, time, and money. Don't worry because "VCEEngine" is here to save you from these losses with its updated and real Databricks Databricks-Certified-Data-Engineer-Professional exam questions.
Databricks-Certified-Data-Engineer-Professional Actual Braindumps: https://www.vceengine.com/Databricks-Certified-Data-Engineer-Professional-vce-test-engine.html