我々の係員は全日24時間あなたのお問い合わせをお待ちしております。あなたは我々のDP-750問題集に疑問を持っているなら、あなたはいつでもどこでもオンラインで我々の係員を問い合わせたり、メールで我々のメールアドレスに送ったりすることができます。我々はタイムリーにあなたのDP-750問題集についての質問を回復しています。あなたの来信を歓迎しております。あなたにサービスを提供するのは我々の幸いです。
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
なぜ受験生はほとんどXhs1991を選んだのですか。Xhs1991は実践の検査に合格したもので、Xhs1991の広がりがみんなに大きな利便性と適用性をもたらしたからです。Xhs1991が提供したMicrosoftのDP-750試験資料はみんなに知られているものですから、試験に受かる自信がないあなたはXhs1991のMicrosoftのDP-750試験トレーニング資料を利用しなければならないですよ。Xhs1991を利用したら、あなたはぜひ自信に満ちているようになり、これこそは試験の準備をするということを感じます。
質問 # 66
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
正解:D
解説:
The correct answer is A. Photon is Azure Databricks' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso's requirement for 'fast and consistent performance for BI workloads' and 'production ingestion workloads that can scale automatically during telemetry spikes.' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what's needed - telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
質問 # 67
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
正解:B
解説:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
質問 # 68
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.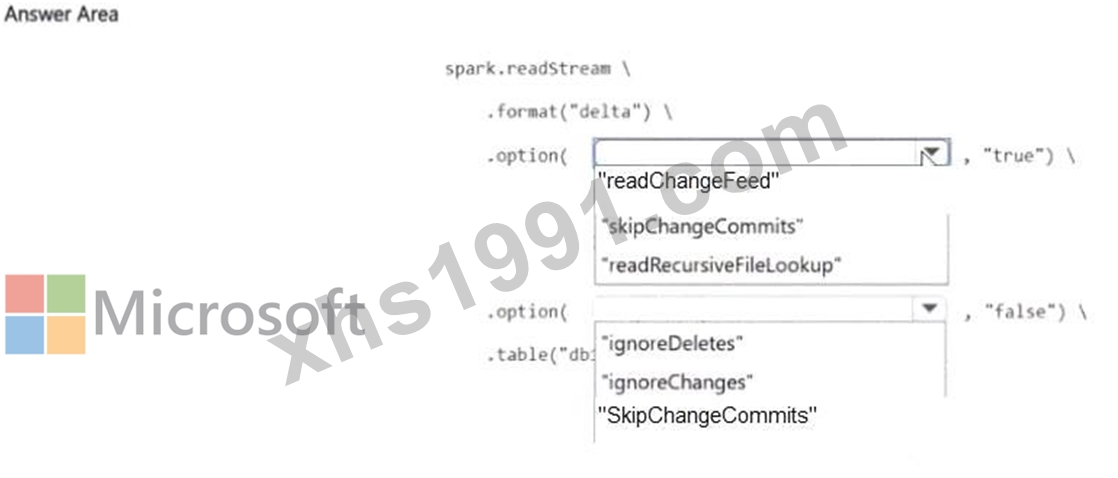
正解:
解説: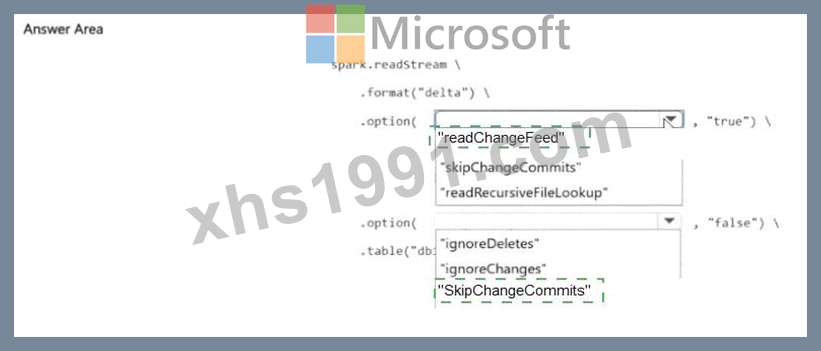
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
質問 # 69
You need to curate Unity Catalog objects that reference the ERP data. The solution must meet the governance requirements.
What should you do?
正解:D
解説:
A foreign catalog mirrors the external ERP database and provides read-only access through Lakehouse Federation. Consequently, it cannot host managed volumes or locally created Delta tables, and its foreign tables cannot be altered to add analytics columns. The appropriate design is to create governed views in the managed analytics catalog and have those views reference the foreign tables through fully qualified catalog.
schema.table names. This preserves the ERP data in its source system, avoids duplication, and exposes standardized curated objects through Unity Catalog. Permissions can then be granted on the managed views while access to underlying foreign objects remains controlled. Unity Catalog uses a three-level namespace, and foreign catalogs are specifically intended to make external database data queryable without copying it into Databricks-managed storage. Microsoft Learn
質問 # 70
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1.
Does this meet the goal?
正解:B
解説:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
質問 # 71
......
人生のチャンスを掴むことができる人は殆ど成功している人です。ですから、ぜひXhs1991というチャンスを掴んでください。Xhs1991のMicrosoftのDP-750試験トレーニング資料はあなたがMicrosoftのDP-750認定試験に合格することを助けます。この認証を持っていたら、あなたは自分の夢を実現できます。そうすると人生には意義があります。
DP-750赤本合格率: https://www.xhs1991.com/DP-750.html