We provide the dbt Labs dbt-Analytics-Engineering exam questions in a variety of formats, including a web-based practice test, desktop practice exam software, and downloadable PDF files. ValidDumps provides proprietary preparation guides for the certification exam offered by the dbt-Analytics-Engineering Exam Dumps. In addition to containing numerous questions similar to the dbt-Analytics-Engineering exam, the dbt Analytics Engineering Certification Exam (dbt-Analytics-Engineering) exam questions are a great way to prepare for the dbt Labs dbt-Analytics-Engineering exam dumps.
| Section | Objectives |
|---|---|
| Topic 1: Testing and Data Quality | - Data validation strategies
|
| Topic 2: Documentation and Lineage | - Data lineage understanding
|
| Topic 3: Deployment and Orchestration | - Running dbt in production
|
| Topic 4: dbt Core Concepts | - Models and materializations
|
| Topic 5: Analytics Engineering Foundations | - Modern data stack concepts (ELT vs ETL)
|
>> dbt-Analytics-Engineering Actual Dump <<
People can achieve great success without an outstanding education and that the dbt Labs qualifications a successful person needs can be acquired through the study to get some professional certifications. So it cannot be denied that suitable dbt-Analytics-Engineering actual test guide do help you a lot; thus we strongly recommend our dbt-Analytics-Engineering Exam Questions for not only that our dbt-Analytics-Engineering training guide is designed to different versions: PDF, Soft and APP versions, which can offer you different study methods, but also that our dbt-Analytics-Engineering learning perp can help you pass the exam without difficulty.
NEW QUESTION # 354
You define a source table and include an override:YAML
Answer: B
Explanation:
While dbt supports overrides, they generally work at higher levels within your project file, not at the model level.
NEW QUESTION # 355
Given this dbt_project.yml:
name: "jaffle_shop"
version: "1.0.0"
config-version: 2
profile: "snowflake"
model-paths: ["models"]
macro-paths: ["macros"]
snapshot-paths: ["snapshots"]
target-path: "target"
clean-targets:
- "logs"
- "target"
- "dbt_modules"
- "dbt_packages"
models:
jaffle_shop:
orders:
materialized: table
When executing a dbt run your models build as views instead of tables:
19:36:14 Found 1 model, 0 tests, 0 snapshots, 0 analyses, 179 macros, 0 operations, 0 seed files, 0 sources, 0 exposures, 0 metrics
19:36:16 Concurrency: 1 threads (target='default')
19:36:17 Finished running 1 view model in 3.35s.
19:36:17 Completed successfully
19:36:17 Done. PASS=1 WARN=0 ERROR=0 SKIP=0 TOTAL=1
Which could be a root cause of why the model was not materialized as a table?
The target-path is incorrectly configured.
Answer: B
Explanation:
The behavior described-dbt running the orders model as a view despite being explicitly configured as a table
-indicates that dbt is not correctly detecting or applying the model-level configuration during compilation.
dbt relies heavily on the target-path directory to write compiled SQL, manifest files, and run artifacts. If the target-path is misconfigured, pointing to a location that dbt does not handle correctly or that overlaps with another folder used internally, dbt may fail to load the correct configuration from the merged project settings.
When dbt cannot locate the compiled configuration for a model, it defaults to its standard materialization type, which is view. This explains why the logs show:
"Finished running 1 view model"
even though the dbt_project.yml clearly declares:
materialized: table.
Additionally, the logs indicate no warnings or parsing errors, meaning dbt ran successfully but with incorrect settings-another indicator of configuration metadata being overridden or misplaced due to an incorrect target- path.
By resolving the target-path issue, dbt will successfully load the model configuration and materialize the orders model as a table as intended.
NEW QUESTION # 356
13. An analyst on your team has informed you that the business logic creating the is_active column of your stg_users model is incorrect.
You update the column logic to:
case
when state = 'Active'
then true
else false
end as is_active
Which test can you add on the state column to support your expectations of the source data? Choose 1 option.
Answer: D
Explanation:
The purpose of this question is to determine how to validate that the input values in the state column support the business logic that determines the is_active field. Since the logic checks whether state = 'Active', it is critical that the state column only contains values that the business process expects. In the example shown, acceptable states appear to be: 'active', 'churned', and 'trial'.
The correct way to enforce this expectation is to apply an accepted_values test on the state column. This ensures that any unexpected state (e.g., 'inactive', 'pending', 'deleted', or NULL) will cause the test to fail, alerting the team that the upstream system is producing unexpected or invalid values. Additionally, adding not_null ensures every user record contains a valid state.
Option A is the only configuration that applies the accepted values test to the correct column (state) and reflects the expected domain of values.
Options B and D incorrectly apply tests to the derived column is_active, not the source column that needs validation. Option C only checks nullability and uniqueness, which does not validate the range of allowed values and thus does not protect the business logic.
Therefore, Option A is the only correct answer.
NEW QUESTION # 357
Choose a correct command for each statement.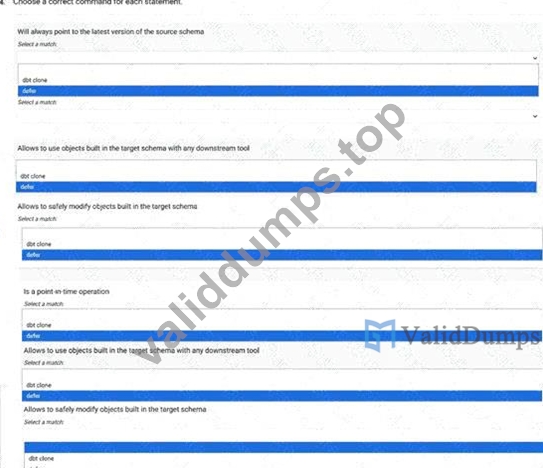
Answer:
Explanation: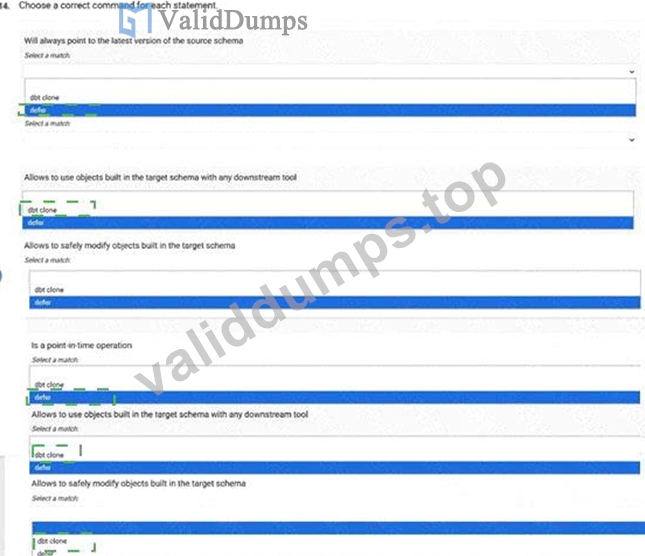
Explanation:
Will always point to the latest version of the source schema
Correct Match: # defer
Allows to use objects built in the target schema with any downstream tool Correct Match: # dbt clone
3## Allows to safely modify objects built in the target schema
Correct Match: # defer
4## Is a point-in-time operation
Correct Match: # dbt clone
defer and dbt clone serve very different purposes in dbt, and understanding their behavior is essential for choosing the right command.
The --defer flag tells dbt to use already-built objects from a previous environment (often production) instead of rebuilding them. Because it always references the existing target schema's most recent objects, it "always points to the latest version of the source schema." Since no objects are overwritten when using defer, it also
"allows safely modifying objects built in the target schema"-your development environment uses production objects without altering them.
By contrast, dbt clone creates a point-in-time copy of existing relations. This cloned schema is static; it does not auto-update when source data changes. Therefore, clone is classified as a "point-in-time operation." Since clone copies physical tables/views into a new schema, downstream tools (BI dashboards, ML pipelines) can safely query the cloned environment without affecting production, making "allows to use objects built in the target schema with any downstream tool" the correct match.
Thus, defer is used for logic substitution without copies, while clone is used for replicable, point-in-time snapshots.
NEW QUESTION # 358
A model depends heavily on geospatial calculations, which are computationally expensive. What optimization strategy might be worth exploring?
Answer: B
Explanation:
Optimized database functionality is crucial for complex calculations. While option A could be beneficial, it's important to first utilize database-level optimizations.
NEW QUESTION # 359
......
Closed cars will not improve, and when we are reviewing our qualifying dbt-Analytics-Engineering examinations, we should also pay attention to the overall layout of various qualifying examinations. For the convenience of users, our dbt-Analytics-Engineering learn materials will be timely updated information associated with the qualification of the home page. Our dbt-Analytics-Engineering Certification material get to the exam questions can help users in the first place. Users can learn the latest and latest test information through our dbt-Analytics-Engineering test preparation materials. What are you waiting for?
New dbt-Analytics-Engineering Exam Dumps: https://www.validdumps.top/dbt-Analytics-Engineering-exam-torrent.html