P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Pass4SureQuiz: https://drive.google.com/open?id=1u827OqkuUlSftRQqde6yp6EHDbqBxgKy
You need to do something immediately to change the situation. For instance, the first step for you is to choose the most suitable Professional-Machine-Learning-Engineer actual guide materials for your coming exam. so the Professional-Machine-Learning-Engineer study materials is very important for you exam, because the Professional-Machine-Learning-Engineer study materials will determine whether you can pass the Professional-Machine-Learning-Engineer Exam successfully or not. We would like to intruduce you our Professional-Machine-Learning-Engineer exam questions, which is popular and praised as the most suitable and helpful Professional-Machine-Learning-Engineer study materials in the market.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Certified - Professional Machine Learning Engineer |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Exam Price: | $200 USD |
| Exam Format: | Multiple choice, Multiple select |
| Related Certifications: | Google Cloud Certified - Professional Data Engineer |
| Available Languages: | English, Japanese |
| Exam Duration: | 120 minutes |
| Real Exam Qty: | 50-60 |
| Passing Score: | Not publicly disclosed (Pass/Fail) |
| Certificate Validity Period: | 2 years |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online (proctored) or Test center (Kryterion) |
| Pre Condition: | Recommended 3+ years of industry experience with ML models and 1+ year of experience using Google Cloud. |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Professional-Machine-Learning-Engineer Exams <<
Passing the Google Professional-Machine-Learning-Engineer certification exam is necessary for professional development, and employing real Professional-Machine-Learning-Engineer Exam Dumps can assist applicants in reaching their professional goals. These actual Professional-Machine-Learning-Engineer questions assist students in discovering areas in which they need improvement, boost confidence, and lower anxiety. Candidates will breeze through Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) certification examination with flying colors and advance to the next level of their jobs if they prepare with updated Professional-Machine-Learning-Engineer exam questions.
Google Professional Machine Learning Engineer certification exam is divided into two sections: a multiple choice section and a practical section. The multiple choice section covers topics such as data preparation, feature engineering, model selection, and model evaluation. The practical section requires candidates to complete a set of tasks related to building, training, and deploying machine learning models using Google Cloud Platform.
NEW QUESTION # 213
You created an ML pipeline with multiple input parameters. You want to investigate the tradeoffs between different parameter combinations. The parameter options are:
- Input dataset
- Max tree depth of the boosted tree regressor
- Optimizer learning rate
You need to compare the pipeline performance of the different parameter combinations measured in F1 score, time to train, and model complexity. You want your approach to be reproducible, and track all pipeline runs on the same platform. What should you do?
Answer: B
NEW QUESTION # 214
You are using Kubeflow Pipelines to develop an end-to-end PyTorch-based MLOps pipeline. The pipeline reads data from BigQuery, processes the data, conducts feature engineering, model training, model evaluation, and deploys the model as a binary file to Cloud Storage. You are writing code for several different versions of the feature engineering and model training steps, and running each new version in Vertex AI Pipelines. Each pipeline run is taking over an hour to complete. You want to speed up the pipeline execution to reduce your development time, and you want to avoid additional costs. What should you do?
Answer: C
Explanation:
1. Caching directly addresses the issue of redundant computations, especially for frequently used feature engineering versions
2. End-to-End" MLOps, Kubeflow Pipelines handle all stages, including feature engineering, maintaining your desired "end-to-end" workflow.
NEW QUESTION # 215
Your team is building an application for a global bank that will be used by millions of customers. You built a forecasting model that predicts customers1 account balances 3 days in the future. Your team will use the results in a new feature that will notify users when their account balance is likely to drop below $25. How should you serve your predictions?
Answer: B
Explanation:
This answer is correct because it uses Firebase, a platform that provides a scalable and reliable notification system for mobile and web applications. Firebase Cloud Messaging (FCM) allows you to send messages and notifications to users across different devices and platforms. By registering each user with a user ID on the FCM server, you can target specific users based on their account balance predictions and send them personalized notifications when their balance is likely to drop below the $25 threshold. This way, you can provide a useful and timely feature for your customers and increase their engagement and retention.
References:
* [Firebase Cloud Messaging]
* [Firebase Cloud Messaging: Send messages to specific devices]
NEW QUESTION # 216
A company wants to classify user behavior as either fraudulent or normal. Based on internal research, a machine learning specialist will build a binary classifier based on two features: age of account, denoted by x, and transaction month, denoted by y. The class distributions are illustrated in the provided figure. The positive class is portrayed in red, while the negative class is portrayed in black.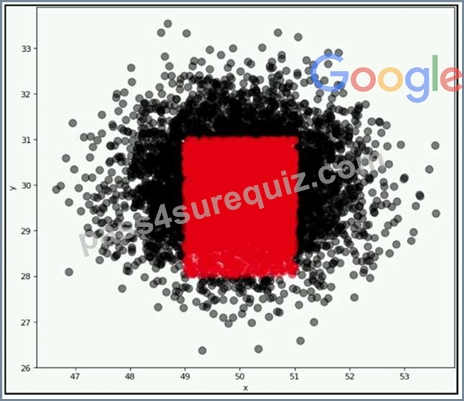
Which model would have the HIGHEST accuracy?
Answer: D
NEW QUESTION # 217
You have successfully deployed to production a large and complex TensorFlow model trained on tabular data.
You want to predict the lifetime value (LTV) field for each subscription stored in the BigQuery table named subscription. subscriptionPurchase in the project named my-fortune500-company-project.
You have organized all your training code, from preprocessing data from the BigQuery table up to deploying the validated model to the Vertex AI endpoint, into a TensorFlow Extended (TFX) pipeline. You want to prevent prediction drift, i.e., a situation when a feature data distribution in production changes significantly over time. What should you do?
Answer: B
Explanation:
* Option A is incorrect because implementing continuous retraining of the model daily using Vertex AI Pipelines is not the most efficient way to prevent prediction drift. Vertex AI Pipelines is a service that allows you to create and run scalable and portable ML pipelines on Google Cloud1. You can use Vertex AI Pipelines to retrain your model daily using the latest data from the BigQuery table. However, this option may be unnecessary or wasteful, as the data distribution may not change significantly every day, and retraining the model may consume a lot of resources and time. Moreover, this option does not monitor the model performance or detect the prediction drift, which are essential steps for ensuring the quality and reliability of the model.
* Option B is correct because adding a model monitoring job where 10% of incoming predictions are sampled 24 hours is the best way to prevent prediction drift. Model monitoring is a service that allows
* you to track the performance and health of your deployed models over time2. You can use model monitoring to sample a fraction of the incoming predictions and compare them with the ground truth labels, which can be obtained from the BigQuery table or other sources. You can also use model monitoring to compute various metrics, such as accuracy, precision, recall, or F1-score, and set thresholds or alerts for them. By using model monitoring, you can detect and diagnose the prediction drift, and decide when to retrain or update your model. Sampling 10% of the incoming predictions every
24 hours is a reasonable choice, as it balances the trade-off between the accuracy and the cost of the monitoring job.
* Option C is incorrect because adding a model monitoring job where 90% of incoming predictions are sampled 24 hours is not a optimal way to prevent prediction drift. This option has the same advantages as option B, as it uses model monitoring to track the performance and health of the deployed model.
However, this option is not cost-effective, as it samples a very large fraction of the incoming predictions, which may incur a lot of storage and processing costs. Moreover, this option may not improve the accuracy of the monitoring job significantly, as sampling 10% of the incoming predictions may already provide a representative sample of the data distribution.
* Option D is incorrect because adding a model monitoring job where 10% of incoming predictions are sampled every hour is not a necessary way to prevent prediction drift. This option also has the same advantages as option B, as it uses model monitoring to track the performance and health of the deployed model. However, this option may be excessive, as it samples the incoming predictions too frequently, which may not reflect the actual changes in the data distribution. Moreover, this option may incur more storage and processing costs than option B, as it generates more samples and metrics.
References:
* Vertex AI Pipelines documentation
* Model monitoring documentation
* [Prediction drift]
* [TensorFlow Extended documentation]
* [BigQuery documentation]
* [Vertex AI documentation]
NEW QUESTION # 218
......
Reliable Professional-Machine-Learning-Engineer Test Syllabus: https://www.pass4surequiz.com/Professional-Machine-Learning-Engineer-exam-quiz.html
P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Pass4SureQuiz: https://drive.google.com/open?id=1u827OqkuUlSftRQqde6yp6EHDbqBxgKy