Our company is a professional certificate test materials provider, and we are in the leading position in providing valid and effective exam materials. AI-300 exam braindumps are high quality, and it also contain certain questions and answers, and it will be enough for you to pass the exam. Besides, in order to let you have a deeper understanding of what you are going to buy, we offer you free demo to have a try before buying AI-300 Training Materials. We offer you free update for 365 days after purchasing, and the update version will be sent to your email address automatically.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 2: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 3: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 4: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Topic 5: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
These practice exams are solely designed to help you achieve AI-300 certification on the first attempt. The mock exam simulator helps you get through every topic inside out and you get overall better grades. This is because you have hands-on the most updated and most reliable Microsoft AI-300 Questions created under the supervision of 90,000 Microsoft professionals.
NEW QUESTION # 59
You are monitoring a fine-tuned large language model deployed in Microsoft Foundry.
You evaluate the model before and after fine-tuning by using the same evaluation dataset.
You review the following evaluation results: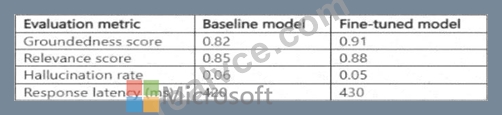
You need to determine whether the fine-tuned model shows improved performance without introducing regression.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.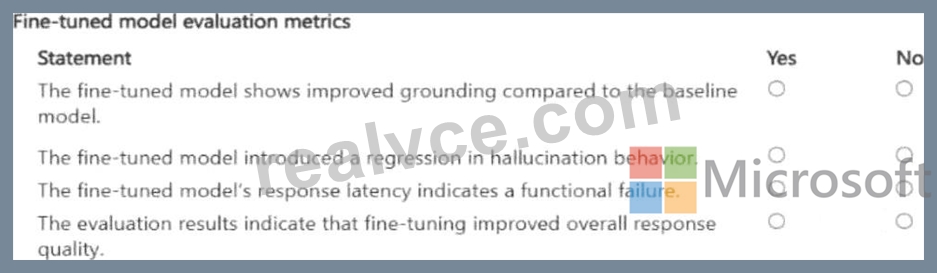
Answer:
Explanation: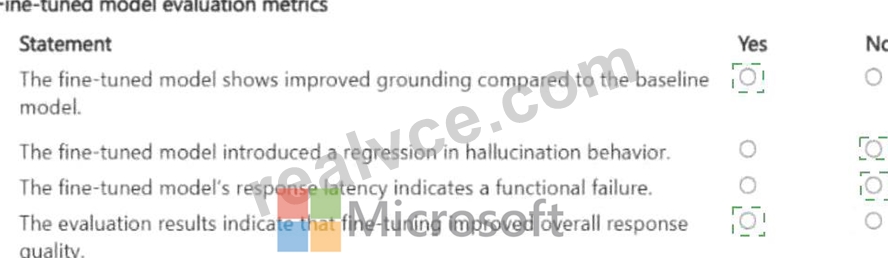
Explanation:
When evaluating a fine-tuned model against the base model using the same evaluation dataset, the interpretation of each metric requires careful analysis. A statement that the fine-tuned model improves on the target task is True if and only if the target metric such as task-specific accuracy, F1 score, or ROUGE score shows a statistically meaningful improvement. A statement about regression on a complementary metric is True if the fine-tuned model ' s score on that metric is meaningfully lower than the base model ' s. In Microsoft Foundry ' s evaluation framework, both pre-fine-tuning and post-fine-tuning results are stored against the same experiment, enabling direct side-by-side comparison. The core principle is that improvement on the primary task is not sufficient if fine-tuning causes degradation on safety or coherence - this is called catastrophic forgetting, and the evaluation dataset is designed to detect it.
Microsoft Learn Reference Topic: Evaluate fine-tuned models in Microsoft Foundry - Compare base and fine-tuned model metrics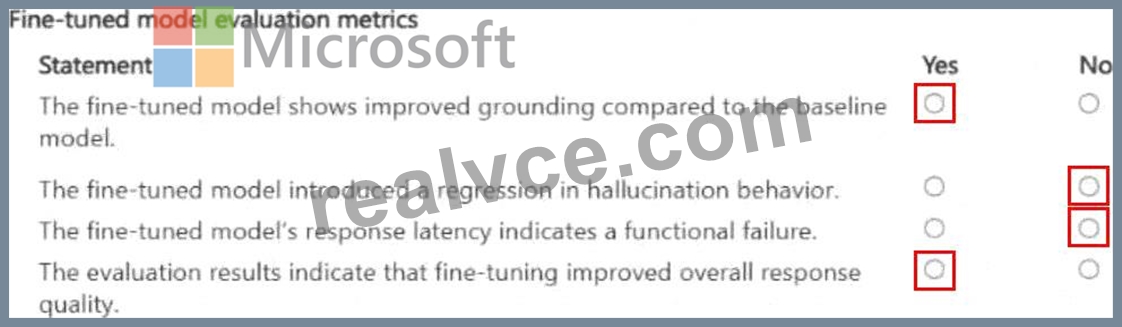
NEW QUESTION # 60
Hotspot Question
You manage an Azure Machine Learning workspace. You configure an automated machine learning regression training job by using the Azure Machine Learning Python SDK v2.
You configure the regression job by using the following script: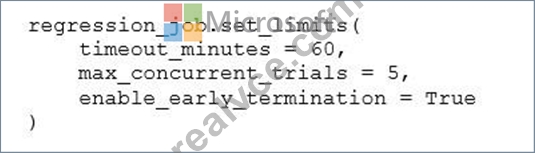
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.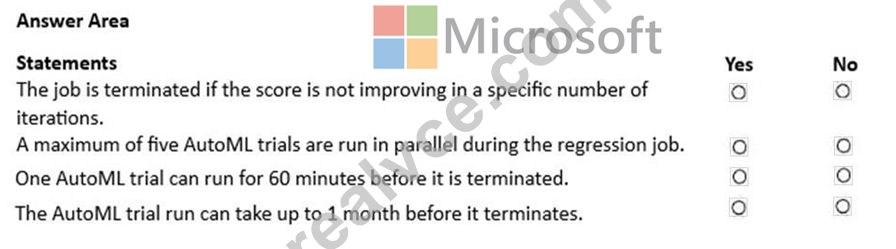
Answer:
Explanation: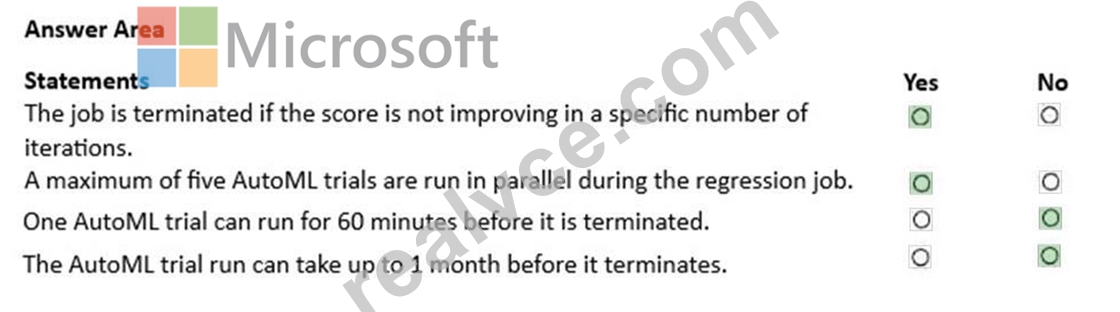
Explanation:
Box 1: Yes
Yes, the automated machine learning (AutoML) training job will terminate early if the primary metric score stops improving after a specific number of iterations.
According to the official Microsoft Azure Machine Learning SDK v2 documentation, setting enable_early_termination = True activates the early stopping policy for the overall experiment.
How Early Termination Works in AutoML v2
The internal early stopping logic operates on a built-in schedule to avoid premature termination:
First 20 iterations: No early stopping takes place (these serve as landmarks).
From the 21st iteration onward: The early stopping window activates.
Termination trigger: The job will automatically stop if the primary evaluation score fails to improve across 10 consecutive iterations.
Box 2: Yes
Yes, a maximum of five trials can run at the same time.
The limit comes from the code settings.
The max_concurrent_trials = 5 line tells Azure to run up to five trials at once.
Box 3: No
No, a single AutoML trial cannot run for 60 minutes before it is terminated.
Parameter Breakdown
In the Azure Machine Learning Python SDK v2, the set_limits() method handles timeouts via two distinct parameters:timeout_minutes = 60: This sets the maximum duration for the entire AutoML job (the experiment as a whole), including data preparation, featurization, and all training trials combined.
trial_timeout_minutes: This parameter governs the maximum time allowed for an individual trial (a single model training run) before termination.
Conclusion
Because trial_timeout_minutes is omitted from your script, it defaults to its standard system value (which is typically 20 minutes for tabular datasets). Therefore, an individual trial will time out much earlier than 60 minutes. Additionally, since the entire job terminates at 60 minutes, it is physically impossible for a single trial to consume the full 60 minutes without forcing the termination of the remaining concurrent runs.
Box 4: No
No, the AutoML trial cannot take up to 1 month before it terminates.
Based on the script parameters, the job will terminate after a maximum of 60 minutes.
Reference:
https://learn.microsoft.com/en-us/python/api/azure-ai-ml/azure.ai.ml.automl.regressionjob?view=azure-python
NEW QUESTION # 61
During training, pipelines occasionally fail due to schema mismatch caused by upstream data changes. You need a robust and automated solution that prevents invalid data from reaching training steps. What is the BEST approach?
Answer: B
NEW QUESTION # 62
During training, pipelines occasionally fail due to schema mismatch caused by upstream data changes. You need a robust and automated solution that prevents invalid data from reaching training steps. What is the BEST approach?
Answer: B
Explanation:
A data validation component ensures that incoming data matches the expected schema before training begins. This prevents pipeline failures and avoids training on corrupted or incomplete data. Ignoring schema mismatches can introduce silent errors, making debugging difficult and compromising model quality.
NEW QUESTION # 63
Hotspot Question
You have an Azure Machine Learning workspace and a collection of image files stored in two Azure Blob Storage accounts.
You need to configure data asset properties.
Which values should you use in your configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.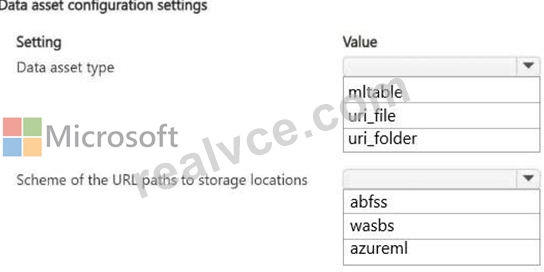
Answer:
Explanation: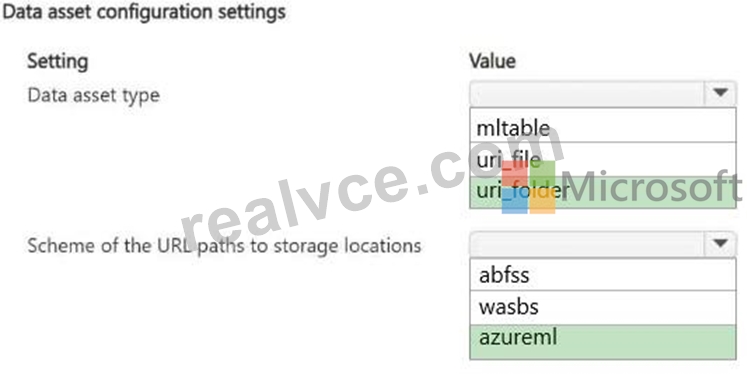
Explanation:
Box 1: uri_folder
The best data asset type for this scenario is a File data asset (uri_file or uri_folder).
In Azure Machine Learning, image files used for training computer vision models are best managed as file-based data assets because machine learning frameworks read individual images directly from storage paths rather than tabular rows.
Preserves Formats: Keeps images in their native formats (PNG, JPEG).Direct Access: Allows training scripts to mount or download files easily.
*-> Folder Mapping: A uri_folder references the entire directory containing your images.
Efficiency: Avoids the overhead of parsing unstructured binary data into a table.
Box 2: azureml
To point a uri_folder data asset to your Azure Blob Storage locations in Azure Machine Learning, you should use the azureml:// URI scheme.
This is the recommended, modern standard that leverages Azure ML datastores for secure tokenless access.
Alternatively, you can use direct Azure Storage URI schemes depending on your configuration Recommended Scheme: Azure ML Datastore This scheme abstracts the storage credentials by referencing an Azure ML Datastore.
Format: azureml://datastores/<datastore_name>/paths/<path_to_folder>/
Example: azureml://datastores/myblobdatastore/paths/images/training_set/ Incorrect:
[not wasbs]
Azure Blob Storage (wasbs)
Used when connecting via the legacy Windows Azure Storage Blob driver.
Format:
wasbs://<container_name>@<storage_account_name>.blob.core.windows.net/<path_to_folder>/
[Not abfss]
Azure Data Lake Storage Gen2 (abfss)
Used if your Blob Storage accounts have the hierarchical namespace enabled.
Format:
abfss://<container_name>@<storage_account_name>.dfs.core.windows.net/<path_to_folder>/ Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-create-data-assets
NEW QUESTION # 64
......
But there are question is that how you can pass the AI-300 exam and get a certificate. The best answer is to download and learn our AI-300 quiz torrent. Our products will help you get what you want in a short time. You just need little time to download and install it after you purchase, then you just need spend about 20~30 hours to learn it. We are glad that you are going to spare your precious time to have a look to our AI-300 Exam Guide.
AI-300 Practice Test Pdf: https://www.realvce.com/AI-300_free-dumps.html