ZertSoft ist eine Schulungswebsite, die spezielle Fragen und Antworten zur Microsoft DP-750 Zertifizierungsprüfung IT-Zertifizierungsprüfung und Prüfungsthemen bieten. Gegen die populäre Microsoft DP-750 Zertifizierungsprüfung haben wir neuen Schulungskonzepte entwickelt, die die Bedürfnisse vieler Leute abdecken können. Viele berühmten IT-Firmen stellen ihre Angestellte laut dem Microsoft DP-750 Zertifikat ein. Deahalb ist die Microsoft DP-750 (Implementing Data Engineering Solutions Using Azure Databricks) Zertifizierungsprüfung zur Zeit sehr populär. ZertSoft wird von vielen akzeptiert und hat den Traum einer Mehrheit der Leute verwirklicht. Wenn Sie mit Hilfe von ZertSoft die Prüfung nicht bestehen, zahlen wir Ihnen die gesammte Summe zurück.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
Haben Sie ZertSoft, haben Sie den Schlüssel zum Erfolg, denn Sie können damit die Microsoft DP-750 Zertifizierungsprüfung zügig bestehen. Unsere Berufsgruppe aus gut ausgebildeten und erfahrenen IT-Eliten haben die Entwicklungen der ständig veränderten IT-Branche untersucht und erforscht, dann erstellen Sie die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung für ZertSoft. Ihre Autorität ist zweifellos. Bevor Sie unsere Prüfungsmaterialien kaufen, können Sie die Demo durch unsere Webseite ZertSoft herunterladen.
62. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes created Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Antwort: A
Begründung:
The correct answer is C - a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
SDP is tailor-made for exactly this pattern: ingest from cloud storage, transform through cleansing and enrichment stages, and publish Delta tables to Unity Catalog. What sets it apart from the other options is built- in monitoring (the pipeline graph shows row counts, expectation metrics, and run history) and automatic retries (failed tasks retry automatically based on pipeline settings, without manual re-run triggers).
Option A (Structured Streaming job) gives you the streaming engine but nothing else - monitoring, alerting, and retry logic all have to be built from scratch. Option B (scheduled notebook job) is a batch approach that requires manual monitoring and lacks the declarative lineage tracking SDP provides. Option D (Azure Data Factory with data flows) works but adds a separate Azure service to manage, introduces ADF licensing costs, and doesn't integrate natively with Unity Catalog governance.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/what-is-delta-live-tables
63. Frage
What is the best way to reduce Databricks compute cost for intermittent workloads?
Antwort: A
Begründung:
Autoscaling adjusts resources based on workload demand, and auto-termination shuts down idle clusters, reducing cost significantly. All-purpose clusters are always on. Increasing size raises cost. Single-node clusters limit scalability and are not suitable for production workloads.
64. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
* Ensure that amount is always greater than 0.
* Fail the pipeline update for Table1 when data that violates rule1 is detected.
Which statement should you execute?
Antwort: D
Begründung:
The expect_or_fail decorator validates every incoming record against the expression amount > 0 and stops the table update when a violation occurs. This exactly meets the requirement that invalid data cause the pipeline update to fail. Option A applies multiple expectations and drops violating records instead of failing the update. Option B also discards invalid records while allowing valid records to continue processing. Option D records expectation metrics but retains invalid records and allows the update to continue. These alternative behaviors are useful when invalid data can be tolerated, quarantined, or monitored, but they do not satisfy strict enforcement. The fail action provides transactional protection because the affected update does not successfully publish data that violates the stated quality rule.
65. Frage
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.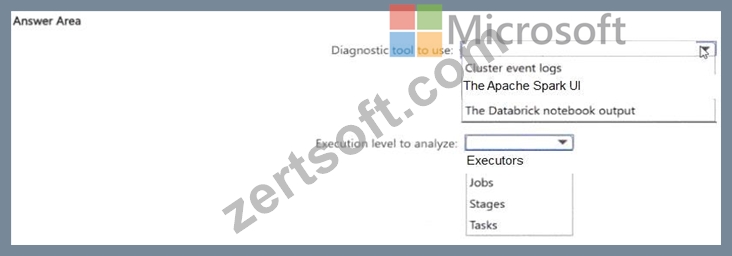
Antwort:
Begründung: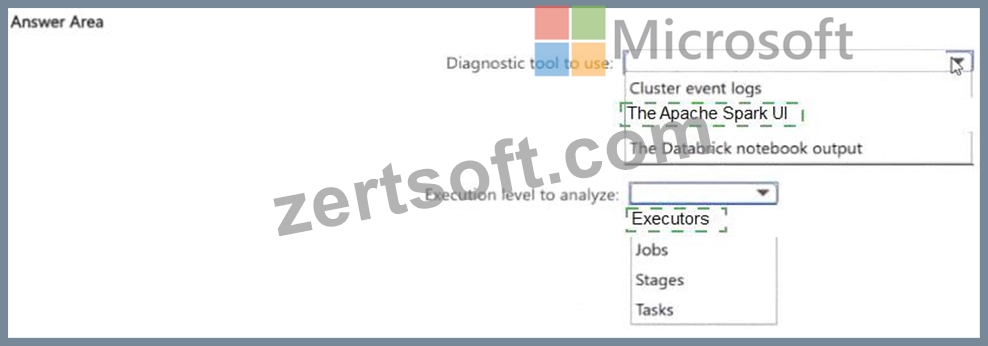
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it's accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it's processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that's data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
66. Frage
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.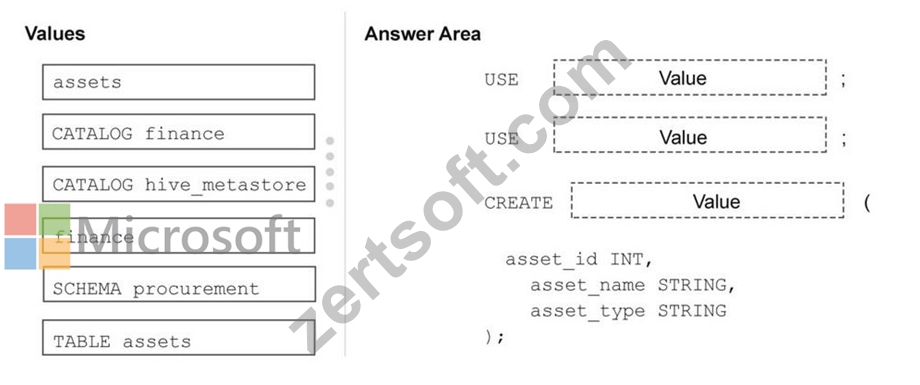
Antwort:
Begründung: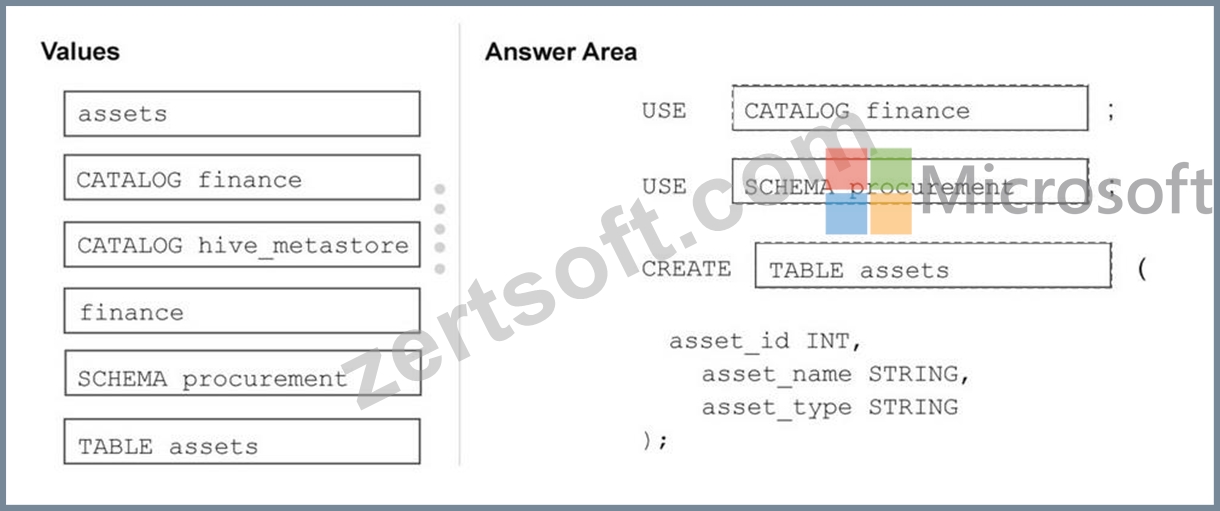
67. Frage
......
Bereiten Sie sich jetzt auf Microsoft DP-750 Prüfung? Auf der offiziellen Webseite unserer ZertSoft wird alle Ihrer Bedarf an der Vorbereitung auf Microsoft DP-750 erfüllt. Insofern unsere Marke Ihnen bekannt ist, können Sie sogleich die Prüfungsunterlagen der Microsoft DP-750 nach Ihrem Bedarf innerhalb einigen Minuten erhalten. Gesicherte Zahlungsmittel, zuverlässige Kundendienste sowie die Produkte auf hohem Standard, diese Vorteilen können alle zusammen Ihnen helfen, zufriedenstellende Leistungen zu bekommen.
DP-750 Prüfungsaufgaben: https://www.zertsoft.com/DP-750-pruefungsfragen.html