P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Actual4Cert: https://drive.google.com/open?id=1UIYfpUWEJVVBPP0BQnwrOFolV0xXIFhj
Actual4Cert will be with you, and make sure you can be successful. No matter how big your IT dream it is, our Actual4Cert will help you to make it come true step by step. Because Actual4Cert's Databricks-Generative-AI-Engineer-Associate exam certification training material is worked out by senior IT specialist team through their own exploration and continuous practice. If you still have some hesitation, you can download Databricks-Generative-AI-Engineer-Associate Dumps PDF free demo and answers on probation on Actual4Cert websites. I believe that it won't let you down.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Reliable Databricks-Generative-AI-Engineer-Associate Study Notes <<
As is known to us, the quality is an essential standard for a lot of people consuming movements, and the high quality of the Databricks-Generative-AI-Engineer-Associate study materials is always reflected in the efficiency. We are glad to tell you that the Databricks-Generative-AI-Engineer-Associate study materials from our company have a high quality and efficiency. If you decide to choose our study materials as you first study tool, it will be very possible for you to pass the Databricks-Generative-AI-Engineer-Associate Exam successfully, and then you will get the related certification in a short time.
NEW QUESTION # 86
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Answer: A
Explanation:
The Generative AI Engineer needs to follow a methodical pipeline to build and deploy a Retrieval-Augmented Generation (RAG) application. The steps outlined in option B accurately reflect this process:
Ingest documents from a source: This is the first step, where the engineer collects documents (e.g., technical regulations) that will be used for retrieval when the application answers user questions.
Index the documents and save to Vector Search: Once the documents are ingested, they need to be embedded using a technique like embeddings (e.g., with a pre-trained model like BERT) and stored in a vector database (such as Pinecone or FAISS). This enables fast retrieval based on user queries.
User submits queries against an LLM: Users interact with the application by submitting their queries. These queries will be passed to the LLM.
LLM retrieves relevant documents: The LLM works with the vector store to retrieve the most relevant documents based on their vector representations.
LLM generates a response: Using the retrieved documents, the LLM generates a response that is tailored to the user's question.
Evaluate model: After generating responses, the system must be evaluated to ensure the retrieved documents are relevant and the generated response is accurate. Metrics such as accuracy, relevance, and user satisfaction can be used for evaluation.
Deploy it using Model Serving: Once the RAG pipeline is ready and evaluated, it is deployed using a model-serving platform such as Databricks Model Serving. This enables real-time inference and response generation for users.
By following these steps, the Generative AI Engineer ensures that the RAG application is both efficient and effective for the task of answering technical regulation questions.
NEW QUESTION # 87
A Generative Al Engineer is ready to deploy an LLM application written using Foundation Model APIs. They want to follow security best practices for production scenarios Which authentication method should they choose?
Answer: A
Explanation:
The task is to deploy an LLM application using Foundation Model APIs in a production environment while adhering to security best practices. Authentication is critical for securing access to Databricks resources, such as the Foundation Model API. Let's evaluate the options based on Databricks' security guidelines for production scenarios.
* Option A: Use an access token belonging to service principals
* Service principals are non-human identities designed for automated workflows and applications in Databricks. Using an access token tied to a service principal ensures that the authentication is scoped to the application, follows least-privilege principles (via role-based access control), and avoids reliance on individual user credentials. This is a security best practice for production deployments.
* Databricks Reference : " For production applications, use service principals with access tokens to authenticate securely, avoiding user-specific credentials " ( " Databricks Security Best Practices, " 2023). Additionally, the " Foundation Model API Documentation " states: " Service principal tokens are recommended for programmatic access to Foundation Model APIs. "
* Option B: Use a frequently rotated access token belonging to either a workspace user or a service principal
* Frequent rotation enhances security by limiting token exposure, but tying the token to a workspace user introduces risks (e.g., user account changes, broader permissions). Including both user and service principal options dilutes the focus on application-specific security, making this less ideal than a service-principal-only approach. It also adds operational overhead without clear benefits over Option A.
* Databricks Reference : " While token rotation is a good practice, service principals are preferred over user accounts for application authentication " ( " Managing Tokens in Databricks,
" 2023).
* Option C: Use OAuth machine-to-machine authentication
* OAuth M2M (e.g., client credentials flow) is a secure method for application-to-service communication, often using service principals under the hood. However, Databricks' Foundation Model API primarily supports personal access tokens (PATs) or service principal tokens over full OAuth flows for simplicity in production setups. OAuth M2M adds complexity (e.g., managing refresh tokens) without a clear advantage in this context.
* Databricks Reference : " OAuth is supported in Databricks, but service principal tokens are simpler and sufficient for most API-based workloads " ( " Databricks Authentication Guide, "
2023).
* Option D: Use an access token belonging to any workspace user
* Using a user's access token ties the application to an individual's identity, violating security best practices. It risks exposure if the user leaves, changes roles, or has overly broad permissions, and it's not scalable or auditable for production.
* Databricks Reference : " Avoid using personal user tokens for production applications due to security and governance concerns " ( " Databricks Security Best Practices, " 2023).
Conclusion : Option A is the best choice, as it uses a service principal's access token, aligning with Databricks' security best practices for production LLM applications. It ensures secure, application-specific authentication with minimal complexity, as explicitly recommended for Foundation Model API deployments.
NEW QUESTION # 88
A Generative AI Engineer I using the code below to test setting up a vector store: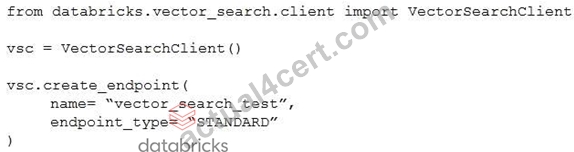
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 89
A Generative Al Engineer has successfully ingested unstructured documents and chunked them by document sections. They would like to store the chunks in a Vector Search index. The current format of the dataframe has two columns: (i) original document file name (ii) an array of text chunks for each document.
What is the most performant way to store this dataframe?
Answer: D
Explanation:
* Problem Context: The engineer needs an efficient way to store chunks of unstructured documents to facilitate easy retrieval and search. The current dataframe consists of document filenames and associated text chunks.
* Explanation of Options:
* Option A: Splitting into train and test sets is more relevant for model training scenarios and not directly applicable to storage for retrieval in a Vector Search index.
* Option B: Flattening the dataframe such that each row contains a single chunk with a unique identifier is the most performant for storage and retrieval. This structure aligns well with how data is indexed and queried in vector search applications, making it easier to retrieve specific chunks efficiently.
* Option C: Creating a unique identifier for each document only does not address the need to access individual chunks efficiently, which is critical in a Vector Search application.
* Option D: Storing each chunk as an independent JSON file creates unnecessary overhead and complexity in managing and querying large volumes of files.
OptionBis the most efficient and practical approach, allowing for streamlined indexing and retrieval processes in a Delta table environment, fitting the requirements of a Vector Search index.
NEW QUESTION # 90
A Generative AI Engineer has been reviewing issues with their company's LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?
Answer: B
Explanation:
Prompt chaining is a fundamental design pattern in LLM application development used to handle complexity. Instead of sending a single, massive, and highly complex prompt to an LLM-which often results in reasoning errors or hallucinations-chaining breaks the logic into a sequence of smaller, targeted steps. For example, a legal assistant might first chain a step to "identify the legal jurisdiction," followed by a step to "extract relevant statutes," and finally a step to "summarize the findings." This modularity improves reliability because each prompt has a narrower focus, making it easier for the model to follow instructions accurately. While it may actually increase latency (contradicting B) and cost (contradicting D) due to multiple API calls, the primary engineering benefit is the significant boost in the quality and robustness of the output. It also allows for intermediate validation and error handling between steps, which is impossible in a single-call architecture.
NEW QUESTION # 91
......
It is easy for you to pass the exam because you only need 20-30 hours to learn and prepare for the exam. You may worry there is little time for you to learn the Databricks-Generative-AI-Engineer-Associate Study Tool and prepare the exam because you have spent your main time and energy on your most important thing such as the job and the learning and can’t spare too much time to learn. But if you buy our Databricks Certified Generative AI Engineer Associate test torrent you only need 1-2 hours to learn and prepare the exam and focus your main attention on your most important thing.
Reliable Databricks-Generative-AI-Engineer-Associate Braindumps: https://www.actual4cert.com/Databricks-Generative-AI-Engineer-Associate-real-questions.html
DOWNLOAD the newest Actual4Cert Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1UIYfpUWEJVVBPP0BQnwrOFolV0xXIFhj