P.S. Free & New DP-600 dumps are available on Google Drive shared by GetValidTest: https://drive.google.com/open?id=1MAf7fxXOnhMWFUBkfiS-f0TL_pqS5w1g
Successful companies are those which identify customers’ requirements and provide the solution to DP-600 exam candidate needs and to make those dreams come true, we are in continuous touch with the exam candidates to get more useful ways. We have favorable quality reputation in the mind of exam candidates these years by trying to provide high quality DP-600 Study Guide with the lowest prices while the highest quality. So you can't miss our DP-600 learning prep.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-600 Reliable Exam Cram <<
Our DP-600 training quiz is the top selling products in the market. You will save a lot of preparation troubles if you purchase our DP-600 study materials. Our DP-600 exam braindumps are highly similar to the real test. Almost all questions of the real exam will be predicated accurately in our DP-600 Practice Questions, which can add you passing rate of the exam. And you will find that our prices for the exam products are quite favorable.
NEW QUESTION # 92
You have a Fabric tenant that contains a semantic model named model1. The two largest columns in model1 are shown in the following table.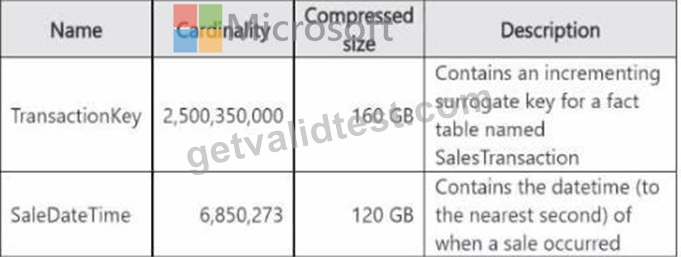
You need to optimize model 1. The solution must meet the following requirements:
* Reduce the model size.
* Increase refresh performance when using Import mode.
* Ensure that the datetime value for each sales transaction is available in the model.
What should you do on each column? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.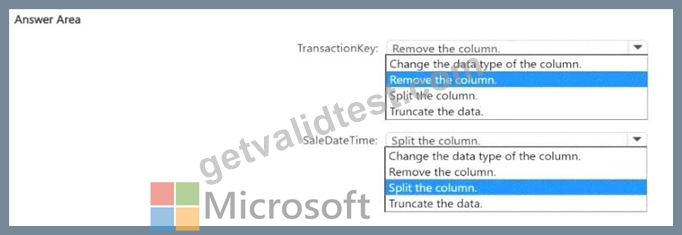
Answer:
Explanation: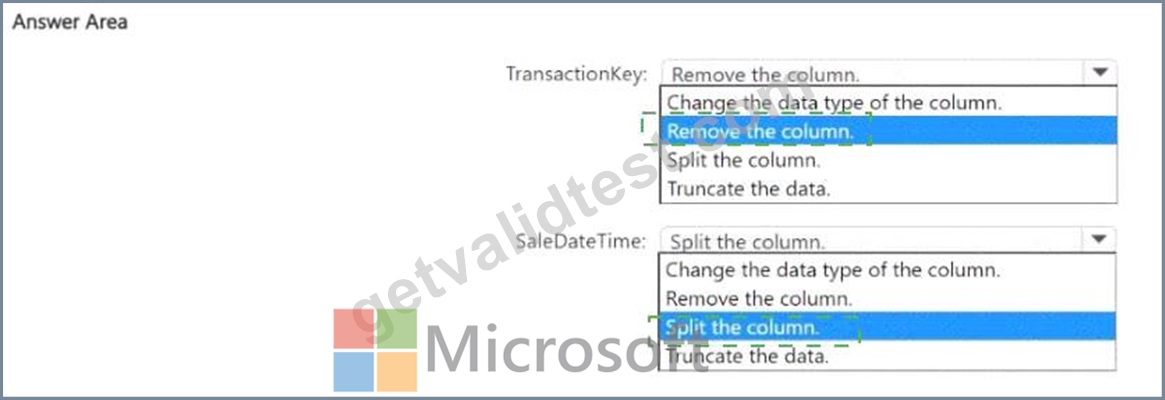
Explanation: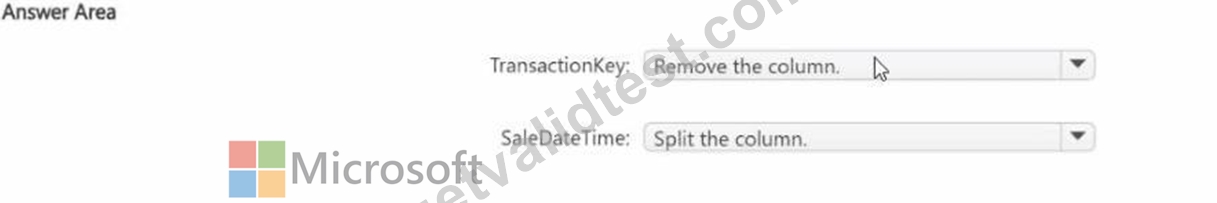
We are optimizing model1 in Fabric with two very large columns:
TransactionKey
Cardinality: 2.5 billion
Size: 160 GB
Description: surrogate key for SalesTransaction fact table.
SaleDateTime
Cardinality: 6.8 million
Size: 120 GB
Description: datetime (to the second) of when a sale occurred.
Goal:
Reduce model size.
Improve refresh performance (Import mode).
Ensure datetime values remain available.
Analysis per column
1. TransactionKey (very high cardinality)
Surrogate keys with extremely high cardinality do not add analytical value in a semantic model because they are not used in measures or grouping.
They take a lot of memory and reduce refresh performance.
Best practice: remove the column from the model.
2. SaleDateTime
Needed to analyze transactions by date and time.
However, storing the full datetime at second-level cardinality causes huge memory usage.
To optimize: split the column into Date and Time columns.
Reduces cardinality significantly.
Preserves full datetime information (can recombine if needed).
Improves compression and refresh speed.
Final Answer:
TransactionKey: Remove the column.
SaleDateTime: Split the column.
References:
Microsoft Fabric optimization guidance - reduce cardinality
Best practices for datetime optimization in semantic models
# Answer Selection:
TransactionKey # Remove the column
SaleDateTime # Split the column
NEW QUESTION # 93
You have a Fabric tenant that contains lakehouse named Lakehousel. Lakehousel contains a Delta table with eight columns. You receive new data that contains the same eight columns and two additional columns.
You create a Spark DataFrame and assign the DataFrame to a variable named df. The DataFrame contains the new data. You need to add the new data to the Delta table to meet the following requirements:
* Keep all the existing rows.
* Ensure that all the new data is added to the table.
How should you complete the code? To answer, select the appropriate options in the answer area.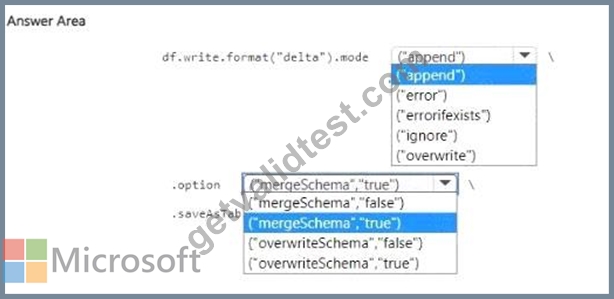
Answer:
Explanation: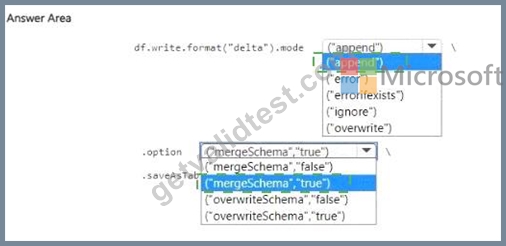
Explanation: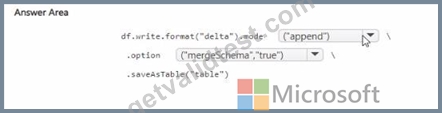
o add new data to the Delta table while meeting the specified requirements:
* You should use the append mode to ensure that all new data is added to the table without affecting the existing rows.
* You should set the mergeSchema option to true to allow the schema of the Delta table to be updated with the new columns found in the DataFrame.
The completed code would look like this:
df.write.format("delta").mode("append")
option("mergeSchema", "true")
saveAsTable("Lakehouse1.TableName")
NEW QUESTION # 94
Which workspace rote assignments should you recommend for ResearchReviewersGroupl and ResearchReviewersGroupZ? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.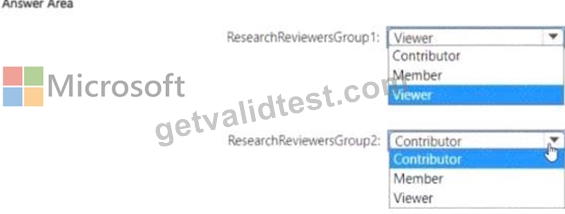
Answer:
Explanation: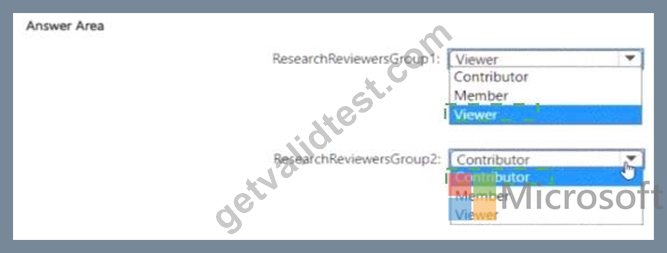
Explanation: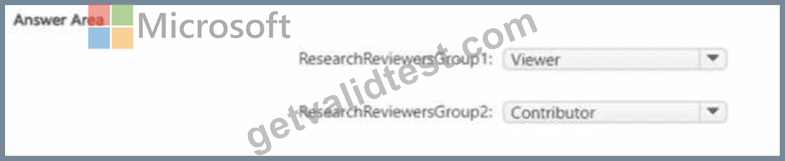
In Azure DevOps workspace (project) security settings, role assignments determine access levels for groups:
Viewer (equivalent to the Readers security group): Grants read-only access to work items, code, pipelines, and other artifacts. Ideal for review-only scenarios where users need to view but not edit content.
Contributor (equivalent to the Contributors security group): Allows full edit and contribute privileges, such as updating work items, code reviews, and pipeline runs. Suitable for active participation in reviews that may involve feedback or changes.
Based on the group names implying review-focused access, Viewer fits Group1 for passive observation, while Contributor fits Group2 for interactive review tasks. These align with default Azure DevOps permissions for secure, least-privilege access.
NEW QUESTION # 95
You are implementing two dimension tables named Customers and Products in a Fabric warehouse.
You need to use slowly changing dimension (SCO) to manage the versioning of data. The solution must meet the requirements shown in the following table.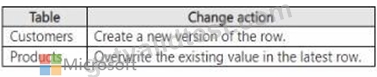
Which type of SCD should you use for each table? To answer, drag the appropriate SCD types to the correct tables. Each SCD type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.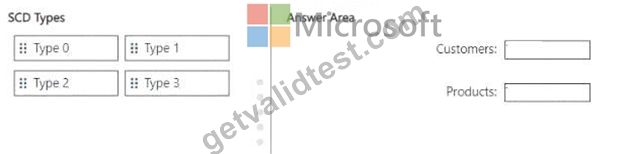
Answer:
Explanation: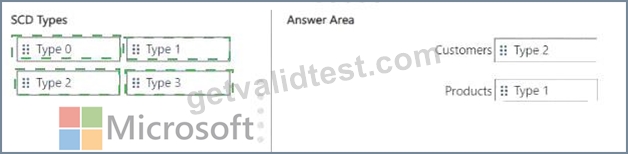
Explanation: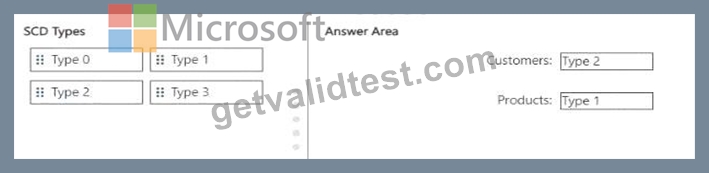
For the Customers table, where the requirement is to create a new version of the row, you would use:
* Type 2 SCD: This type allows for the creation of a new record each time a change occurs, preserving the history of changes over time.
For the Products table, where the requirement is to overwrite the existing value in the latest row, you would use:
* Type 1 SCD: This type updates the record directly, without preserving historical data.
NEW QUESTION # 96
You have a Fabric workspace that contains a DirectQuery semantic model. The model queries a data source that has 500 million rows.
You have a Microsoft Power Bl report named Report1 that uses the model. Report! contains visuals on multiple pages.
You need to reduce the query execution time for the visuals on all the pages.
What are two features that you can use? Each correct answer presents a complete solution.
NOTE: Each correct answer is worth one point.
Answer: B,C
Explanation:
User-defined aggregations (A) and query caching (C) are two features that can help reduce query execution time. User-defined aggregations allow precalculation of large datasets, and query caching stores the results of queries temporarily to speed up future queries. References = Microsoft Power BI documentation on performance optimization offers in-depth knowledge on these features.
NEW QUESTION # 97
......
If you are a child's mother, with DP-600 test answers, you will have more time to stay with your if you are a student, with DP-600 exam torrent, you will have more time to travel to comprehend the wonders of the world. In the other worlds, with DP-600 guide tests, learning will no longer be a burden in your life. You can save much time and money to do other things what meaningful. You will no longer feel tired because of your studies, if you decide to choose and practice our DP-600 Test Answers. Your life will be even more exciting.
DP-600 Study Materials Review: https://www.getvalidtest.com/DP-600-exam.html
BTW, DOWNLOAD part of GetValidTest DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=1MAf7fxXOnhMWFUBkfiS-f0TL_pqS5w1g