BONUS!!! JPTestKing Databricks-Certified-Data-Analyst-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1dpGBCtneGE746cFto-_ef03XeZPG5yDo
変化する地域に対応するには、問題を解決する効率を改善する必要があります。これは、試験に対処するだけでなく、多くの側面を反映しています。 Databricks-Certified-Data-Analyst-Associate実践教材は、あなたがそれを実現するのに役立ちます。これらの時間に敏感な試験の受験者にとって、重要なニュースで構成される高効率のDatabricks-Certified-Data-Analyst-Associate実際のテストは、最高の助けになります。定期的にそれらを練習することによってのみ、あなたはあなたに明らかな進歩が起こったのを見るでしょう。
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Available Languages: | English |
| Exam Price: | $200 USD |
| Real Exam Qty: | 45 |
| Passing Score: | 70% |
| Exam Format: | Multiple Choice |
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
| Exam Way: | Online proctored or test center proctored |
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
>> Databricks Databricks-Certified-Data-Analyst-Associate復習内容 <<
JPTestKingのDatabricksのDatabricks-Certified-Data-Analyst-Associate試験トレーニング資料は受験生が模擬試験場で勉強させます。受験生は問題を選べ、テストの時間もコントロールできます。JPTestKingというサイトで、あなたはストレスと不安なく試験の準備をすることができますから、一般的な間違いを避けられます。そうしたら、あなたは自信を得ることができて、実際の試験で経験を活かして気楽に合格します。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
質問 # 25
Consider the following two statements:
Statement 1: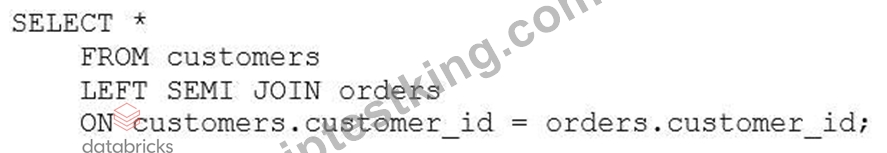
Statement 2:
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
正解:E
解説:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id).
Therefore, the result sets for the two statements will differ in the following way:
* The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
* The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
* A. The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
* C. There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
* D. Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
* E. The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
References: JOIN | Databricks on AWS, JOIN - Azure Databricks - Databricks SQL | Microsoft Learn, array_join function | Databricks on AWS, Hints | Databricks on AWS
質問 # 26
A data analysis team has noticed that their Databricks SQL queries are running too slowly when connected to their always-on SQL endpoint. They claim that this issue is present when many members of the team are running small queries simultaneously. They ask the data engineering team for help. The data engineering team notices that each of the team's queries uses the same SQL endpoint.
Which of the following approaches can the data engineering team use to improve the latency of the team's queries?
正解:C
解説:
Option B is correct. The problem is many users running small queries simultaneously, which is a concurrency issue. Increasing the maximum number of clusters lets the SQL warehouse scale out to serve more concurrent queries. Increasing cluster size is more useful for complex or resource-heavy queries, not necessarily many small simultaneous queries. Auto Stop reduces cost but does not improve active-query latency. Official Databricks extract: "You can increase the maximum clusters if you want to handle more concurrent users," and Databricks recommends monitoring queued queries and adjusting maximum clusters.
質問 # 27
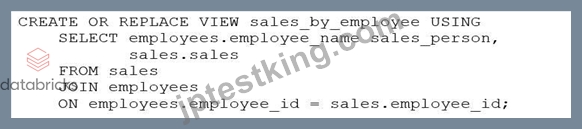
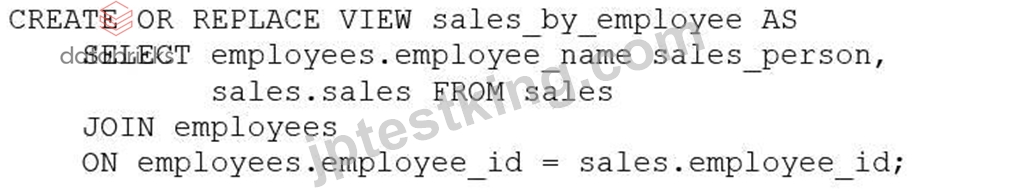
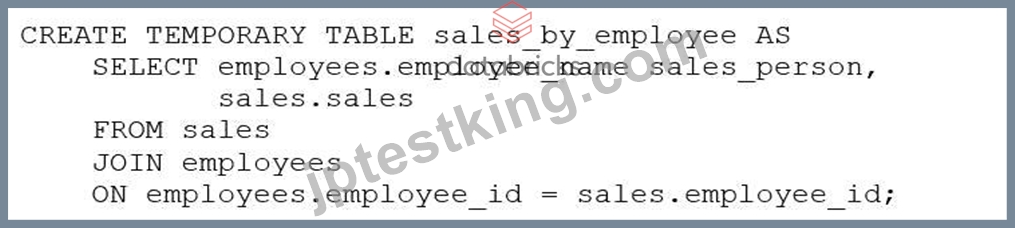
A business analyst has been asked to create a data entity/object called sales_by_employee. It should always stay up-to-date when new data are added to the sales table. The new entity should have the columns sales_person, which will be the name of the employee from the employees table, and sales, which will be all sales for that particular sales person. Both the sales table and the employees table have an employee_id column that is used to identify the sales person.
Which of the following code blocks will accomplish this task?
正解:B
解説:
The SQL code provided in Option D is the correct way to create a view named sales_by_employee that will always stay up-to-date with the sales and employees tables. The code uses the CREATE OR REPLACE VIEW statement to define a new view that joins the sales and employees tables on the employee_id column. It selects the employee_name as sales_person and all sales for each employee, ensuring that the data entity
/object is always up-to-date when new data are added to these tables.
The answer can be verified from Databricks SQL documentation which provides insights on creating views using SQL queries, joining tables, and selecting specific columns to be included in the view. Reference link: Databricks SQL
質問 # 28
Which of the following layers of the medallion architecture is most commonly used by data analysts?
正解:B
解説:
The gold layer of the medallion architecture contains data that is highly refined and aggregated, and powers analytics, machine learning, and production applications. Data analysts typically use the gold layer to access data that has been transformed into knowledge, rather than just information. The gold layer represents the final stage of data quality and optimization in the lakehouse. Reference: What is the medallion lakehouse architecture?
質問 # 29
Which of the following should data analysts consider when working with personally identifiable information (PII) data?
正解:B
解説:
Data analysts should consider all of these factors when working with PII data, as they may affect the data security, privacy, compliance, and quality. PII data is any information that can be used to identify a specific individual, such as name, address, phone number, email, social security number, etc. PII data may be subject to different legal and ethical obligations depending on the context and location of the data collection and analysis. For example, some countries or regions may have stricter data protection laws than others, such as the General Data Protection Regulation (GDPR) in the European Union. Data analysts should also follow the organization-specific best practices for PII data, such as encryption, anonymization, masking, access control, auditing, etc. These best practices can help prevent data breaches, unauthorized access, misuse, or loss of PII data. Reference:
How to Use Databricks to Encrypt and Protect PII Data
Automating Sensitive Data (PII/PHI) Detection
Databricks Certified Data Analyst Associate
質問 # 30
......
Databricks-Certified-Data-Analyst-Associate日本語版受験参考書: https://www.jptestking.com/Databricks-Certified-Data-Analyst-Associate-exam.html
BONUS!!! JPTestKing Databricks-Certified-Data-Analyst-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1dpGBCtneGE746cFto-_ef03XeZPG5yDo