Certified-Data-Engineer-Professional熱門題庫 & Certified-Data-Engineer-Professional最新考證

如果你使用了在VCESoft的Certified-Data-Engineer-Professional考古題之後還是在Certified-Data-Engineer-Professional認證考試中失敗了,那麼你可以拿回你當初購買資料時需要的全部費用。這就是VCESoft對廣大考生的承諾。優秀的資料不是只靠說出來的,更要經受得住大家的考驗。VCESoft的資料完全可以經受得住時間的檢驗。VCESoft能有現在的成就都是大家通過實踐得到的成果。因為是真實可靠的,所以VCESoft的資料才能經過這麼長的時間後越來越受到大家的歡迎。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
| Topic 2: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 3: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 5: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 6: Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Topic 7: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 8: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
| Topic 9: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 10: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
>> Certified-Data-Engineer-Professional熱門題庫 <<
最新的Certified-Data-Engineer-Professional熱門題庫,最新的考試題庫幫助妳壹次性通過Certified-Data-Engineer-Professional考試
如果你覺得你購買VCESoft Databricks的Certified-Data-Engineer-Professional考試培訓資料利用它來準備考試是一場冒險,那麼整個生命就是一場冒險,走得最遠的人常常就是願意去做願意去冒險的人。更何況VCESoft Databricks的Certified-Data-Engineer-Professional考試培訓資料是由眾多考生用實踐證明了,它帶給每位考生的成功也是真實有效的,成功有夢想和希望固然重要,但更重要的是去實踐和證明,VCESoft Databricks的Certified-Data-Engineer-Professional考試培訓資料是被證明一定會成功的,選擇了它,你還有什麼理由不成功呢!
最新的 Databricks Certification Certified-Data-Engineer-Professional 免費考試真題 (Q89-Q94):
問題 #89
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
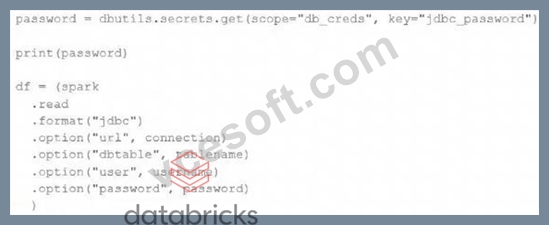
Which statement describes what will happen when the above code is executed?
- A. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- B. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- C. The connection to the external table will succeed; the string "redacted" will be printed.
- D. The connection to the external table will succeed; the string value of password will be printed in plain text.
- E. The connection to the external table will fail; the string "redacted" will be printed.
答案:C
解題說明:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks.
問題 #90
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- B. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- C. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- D. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- E. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
答案:D
解題說明:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
問題 #91
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
assert(myIntegrate(lambda x: x*x, 0, 3) [0] == 9)
Which kind of the test does the above line exemplify?
- A. Unit
- B. Manual
- C. Integration
- D. functional
- E. End-to-end
答案:A
解題說明:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
問題 #92
A data team is working to optimize an existing large, fast-growing table 'orders' with high cardinality columns, which experiences significant data skew and requires frequent concurrent writes. The team notice that the columns 'user_id', 'event_timestamp' and 'product_id' are heavily used in analytical queries and filters, although those keys may be subject to change in the future due to different business requirements. Which partitioning strategy should the team choose to optimize the table for immediate data skipping, incremental management over time, and flexibility?
- A. Partition the table with: ALTER TABLE orders PARTITION BY user_id, product_id, event_timestamp
- B. Z-order the table with OPTIMIZE orders ZORDER BY (user_id, product_id, event_timestamp)
- C. Use z-order after partitiing the table: OPTIMIZE orders ZORDER BY (user_id, product_id) WHERE event_timestamp = current date () - 1 DAY
- D. Cluster the table with: ALTER TABLE orders CLUSTER BY user_id, product_id, event_timestamp
答案:B
解題說明:
Z-ordering optimizes data skipping for selective queries on high-cardinality columns without physically repartitioning the table, making it flexible if query patterns change. Using OPTIMIZE ...
ZORDER BY (user_id, product_id, event_timestamp) improves query performance for filters and joins while allowing incremental writes, avoiding the data skew and maintenance overhead that explicit partitioning or clustering could introduce.
問題 #93
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
- A. Post_time
- B. Date
- C. Post_id
- D. latitude
- E. User_id
答案:B
解題說明:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned. Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
問題 #94
......
如今在IT業裏面臨著激烈的競爭,你會感到力不從心,這是必然的。你要做的是為你的事業保駕護航,當然,你有很多選擇,我推薦VCESoft Databricks的Certified-Data-Engineer-Professional的考試試題及答案,它是幫助你成功獲得IT認證的好幫手,所以你還在等什麼呢,去獲得新的VCESoft Databricks的Certified-Data-Engineer-Professional的考試培訓資料吧。
Certified-Data-Engineer-Professional最新考證: https://www.vcesoft.com/Certified-Data-Engineer-Professional-pdf.html
- Certified-Data-Engineer-Professional題庫分享 🦧 Certified-Data-Engineer-Professional權威認證 😗 Certified-Data-Engineer-Professional考證 🛰 立即打開【 www.newdumpspdf.com 】並搜索⮆ Certified-Data-Engineer-Professional ⮄以獲取免費下載Certified-Data-Engineer-Professional考試資訊
- Certified-Data-Engineer-Professional認證考試 🦳 Certified-Data-Engineer-Professional題庫 💕 Certified-Data-Engineer-Professional題庫 🎓 免費下載「 Certified-Data-Engineer-Professional 」只需在➥ www.newdumpspdf.com 🡄上搜索新版Certified-Data-Engineer-Professional考古題
- 有用的Certified-Data-Engineer-Professional熱門題庫和資格考試中的領先提供者和一流的Certified-Data-Engineer-Professional最新考證 ✔ 打開《 www.newdumpspdf.com 》搜尋【 Certified-Data-Engineer-Professional 】以免費下載考試資料Certified-Data-Engineer-Professional測試引擎
- 有用的Certified-Data-Engineer-Professional熱門題庫和資格考試中的領先提供者和一流的Certified-Data-Engineer-Professional最新考證 🦮 [ www.newdumpspdf.com ]上的免費下載▛ Certified-Data-Engineer-Professional ▟頁面立即打開Certified-Data-Engineer-Professional題庫分享
- Certified-Data-Engineer-Professional熱門題庫和www.newdumpspdf.com - 認證考試材料的領導者和Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional 🧒 《 www.newdumpspdf.com 》是獲取➠ Certified-Data-Engineer-Professional 🠰免費下載的最佳網站Certified-Data-Engineer-Professional考試內容
- Certified-Data-Engineer-Professional題庫 🍉 Certified-Data-Engineer-Professional題庫分享 💷 Certified-Data-Engineer-Professional考證 😚 進入▛ www.newdumpspdf.com ▟搜尋⮆ Certified-Data-Engineer-Professional ⮄免費下載Certified-Data-Engineer-Professional認證指南
- 只有最有效的Certified-Data-Engineer-Professional熱門題庫才能提供100%通過的承諾-關于Databricks Certified Data Engineer Professional 👧 透過{ www.kaoguti.com }輕鬆獲取➽ Certified-Data-Engineer-Professional 🢪免費下載Certified-Data-Engineer-Professional考試大綱
- Certified-Data-Engineer-Professional認證考試考古題 - 最新的Databricks Certified-Data-Engineer-Professional認證考試題庫 ✈ 透過⇛ www.newdumpspdf.com ⇚輕鬆獲取[ Certified-Data-Engineer-Professional ]免費下載Certified-Data-Engineer-Professional認證考試
- www.testpdf.net Certified-Data-Engineer-Professional熱門題庫 /立即下載 🧞 [ www.testpdf.net ]最新➤ Certified-Data-Engineer-Professional ⮘問題集合Certified-Data-Engineer-Professional考試資訊
- Certified-Data-Engineer-Professional考證 🎽 Certified-Data-Engineer-Professional下載 ⭕ Certified-Data-Engineer-Professional考試證照綜述 🌉 到➽ www.newdumpspdf.com 🢪搜索➥ Certified-Data-Engineer-Professional 🡄輕鬆取得免費下載Certified-Data-Engineer-Professional考試證照綜述
- Certified-Data-Engineer-Professional題庫資訊 🦔 Certified-Data-Engineer-Professional下載 💞 Certified-Data-Engineer-Professional證照指南 💡 在“ www.testpdf.net ”搜索最新的▷ Certified-Data-Engineer-Professional ◁題庫Certified-Data-Engineer-Professional下載
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, kaeuchi.jp, network.crcna.org, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, buyerseller.xyz, Disposable vapes