Simplified Document Sharing and Accessibility With Databricks Databricks-Machine-Learning-Professional PDF (Questions)

2026 Latest PDFTorrent Databricks-Machine-Learning-Professional PDF Dumps and Databricks-Machine-Learning-Professional Exam Engine Free Share: https://drive.google.com/open?id=1MFAafwiwrUYjs_0jzvyXbnCSOl_yHjXy
With pass rate reaching 98.75%, Databricks-Machine-Learning-Professional exam torrent has received great popularity among candidates, and they think highly of the exam dumps. In addition, Databricks-Machine-Learning-Professional exam braindumps are high-quality and accuracy, because we have professionals to verify the answers to ensure the accuracy. Databricks-Machine-Learning-Professional exam dumps have most of knowledge points for the exam, and you can mater the major points through practicing. In addition, we have online and offline chat service for Databricks-Machine-Learning-Professional Exam Dumps, and they posse the professional knowledge for the exam. If you have any questions about Databricks-Machine-Learning-Professional exam materials, you can have a conversation with us.
| Topic | Details |
|---|
| Topic 1 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 2 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 3 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 4 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 5 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 6 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 7 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 8 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 9 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
>> Databricks-Machine-Learning-Professional Latest Exam Cost <<
Databricks-Machine-Learning-Professional Latest Test Practice & 100% Databricks-Machine-Learning-Professional Exam Coverage
You have seen PDFTorrent's Databricks Databricks-Machine-Learning-Professional Exam Training materials, it is time to make a choice. You can choose other products, but you have to know that PDFTorrent can bring you infinite interests. Only PDFTorrent can guarantee you 100% success. PDFTorrent allows you to have a bright future. And allows you to work in the field of information technology with high efficiency.
Databricks Certified Machine Learning Professional Sample Questions (Q150-Q155):
NEW QUESTION # 150
A Machine Learning Engineer has automated a model retraining job in Databricks. Each scheduled run trains multiple candidate models with new sales data and logs all runs with MLflow.
The goal is to select and register the best-performing model at the end of each cycle to ensure optimal forecast accuracy. Which approach will meet this goal?
- A. Register the best model based on the primary evaluation metric.
- B. Register the model with the lowest training loss regardless of validation metrics.
- C. Register all models from the run since all of them are trained on newer data and hence will be more accurate.
- D. Register the first model that has an evaluation metric better than the previously deployed model.
Answer: A
Explanation:
Selecting and registering the model that performs best on the primary evaluation metric ensures that only the highest-quality model is promoted at each retraining cycle. This approach aligns with MLOps best practices by basing promotion decisions on objective performance criteria rather than training order or assumptions about data freshness.
NEW QUESTION # 151
A Data Scientist is tasked with developing models to forecast product demand. The company offers 5000 different product types, and the Data Scientist must generate weekly forecasts for each type. They have access to two years of historical purchase data and are given ample project budget.
For their next project, they want to build 5000 separate Random Forest models, one for each product type. They aim to train all the models as quickly as possible with minimal setup.
Which approach meets these requirements?
- A. Use the RandomForest method from MLlib. This will leverage Spark's parallel processing capability to train 5000 different models.
- B. Leverage the pandas function API (Grouped map) to group the data by product type and apply a custom model training function to each group.
- C. Create a Databricks Workflow with 5000 tasks. Each task is configured to accept a product ID as a parameter which will then train a model based on the specified product ID.
- D. Use the DeepSpeed library to distribute the data by product across different nodes to enable the parallel training of multiple models.
Answer: B
Explanation:
The pandas function API with grouped map allows data to be grouped by product type and applies a custom training function independently to each group. This approach enables massive parallelism across the cluster with minimal orchestration or setup, making it well suited for rapidly training thousands of independent models in parallel.
NEW QUESTION # 152
A machine learning engineer has developed the following custom model class with preprocessing logic to combine two columns:
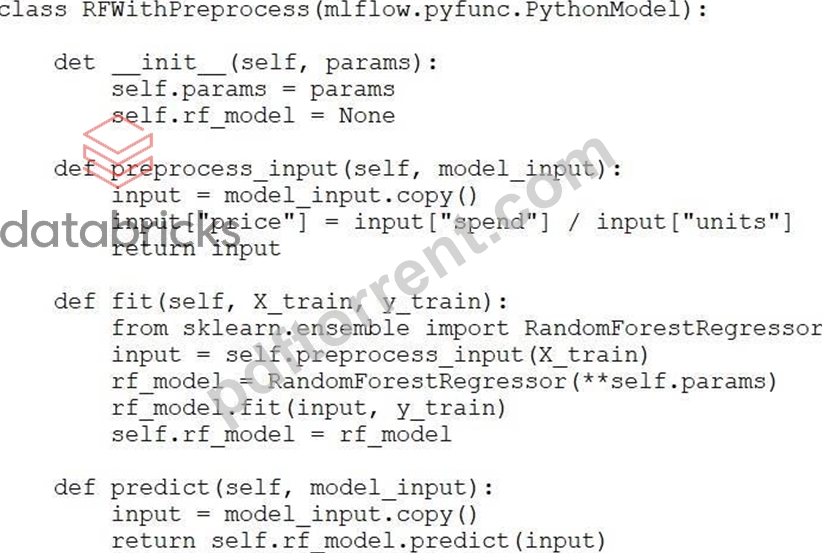
However, instances of this class are unable to compute predictions.
Which set of changes will update the class so predictions can be computed while continuing to apply the preprocessing logic?
- A. Replace model_input.copy() with self.preprocess_input(model_input.copy()) in the preprocess_input method
- B. Remove the self.rf_model = rf_model line from the fit method
- C. Replace model_input.copy() with self.preprocess_input(model_input.copy()) in the predict method
- D. Replace self.rf_model.predict(input) with self.predict(input) in the predict method
Answer: C
Explanation:
The issue is that the predict() method does not apply the same preprocessing as the fit() method.
During training, the model uses preprocessed data (via self.preprocess_input()), but during prediction, it directly uses raw input. This mismatch causes prediction errors because the model expects preprocessed input.
By updating the predict() method to call self.preprocess_input(model_input.copy()), both training and prediction use consistent feature transformations, allowing predictions to be computed successfully.
NEW QUESTION # 153
A Machine Learning Engineer has trained a credit scoring model and needs to evaluate fairness metrics across different customer segments while maintaining different levels of granularity for business reporting. They need to compute metrics like precision, recall, and demographic parity at the individual feature level (credit_score_range, income_bracket) as well as intersectional slices (combinations of features). The model outputs are stored in a Delta table with prediction probabilities and actual default labels. The engineer wants to systematically evaluate model performance across these various feature slices and granularities. Which approach will do this?
- A. Build separate Spark DataFrames for each slice and compute metrics using standard DataFrame operations.
- B. Implement custom MLflow evaluation functions that iterate through all possible feature combinations.
- C. Use Unity Catalog metric views with dimensions defined for each feature and measures for the fairness metrics.
- D. Create Lakehouse Monitoring with slicing expressions for individual features and intersection conditions.
Answer: D
Explanation:
Lakehouse Monitoring supports defining slicing expressions on one or more columns, allowing metrics such as precision, recall, and fairness indicators to be computed at both individual feature levels and intersectional combinations. This provides a systematic, scalable, and governed way to evaluate model performance and fairness across multiple granularities directly from Delta tables without custom metric pipelines.
NEW QUESTION # 154
A machine learning engineer is converting a Hyperopt-based hyperparameter tuning process from manual MLflow logging to MLflow Autologging. They notice that not all details and objects are automatically logged, and they will need to manually log some things. Which of the following will need to be manually logged when performing nested runs with Hyperopt and MLflow Autologging?
- A. Best trial evaluation metric
- B. Trial models
- C. Hyperparameter values
- D. Trial status
- E. Evaluation metrics
Answer: A
Explanation:
When using MLflow Autologging with Hyperopt and nested runs, the best trial evaluation metric is not automatically logged and must be logged manually. Autologging captures trial-level details like hyperparameters and evaluation metrics, but summarizing and logging the overall best trial's result is a manual responsibility of the engineer.
NEW QUESTION # 155
......
Once you decide to pass the Databricks-Machine-Learning-Professional exam and get the certification, you may encounter many handicaps that you don't know how to deal with, so, you may think that it is difficult to pass the Databricks-Machine-Learning-Professional exam and get the certification. In order to help you solve these problem and help you pass the exam easy, we complied such a Databricks-Machine-Learning-Professional Exam Torrent. We can promise that you will have no regret buying our Databricks-Machine-Learning-Professional exam dumps. Our Databricks-Machine-Learning-Professional exam questions have a high pass rate as 99% to 100%, you will pass with it for sure.
Databricks-Machine-Learning-Professional Latest Test Practice: https://www.pdftorrent.com/Databricks-Machine-Learning-Professional-exam-prep-dumps.html
- Get Trustable Databricks-Machine-Learning-Professional Latest Exam Cost and Best Accurate Databricks-Machine-Learning-Professional Latest Test Practice 🥞 Open ➽ www.exam4labs.com 🢪 enter ➤ Databricks-Machine-Learning-Professional ⮘ and obtain a free download 🎋Databricks-Machine-Learning-Professional New APP Simulations
- 100% Pass Quiz 2026 High-quality Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Latest Exam Cost 🍂 Search for ⮆ Databricks-Machine-Learning-Professional ⮄ and download it for free on ➡ www.pdfvce.com ️⬅️ website 🚵Databricks-Machine-Learning-Professional New Braindumps Book
- Databricks-Machine-Learning-Professional New APP Simulations 😮 Databricks-Machine-Learning-Professional Boot Camp 🧷 Databricks-Machine-Learning-Professional New Braindumps Book 🧿 Search for 《 Databricks-Machine-Learning-Professional 》 on ✔ www.vce4dumps.com ️✔️ immediately to obtain a free download 🍳Download Databricks-Machine-Learning-Professional Fee
- Professional Databricks Databricks-Machine-Learning-Professional Latest Exam Cost | Try Free Demo before Purchase 🌕 Go to website ➤ www.pdfvce.com ⮘ open and search for ➡ Databricks-Machine-Learning-Professional ️⬅️ to download for free 🌛Databricks-Machine-Learning-Professional New Braindumps Book
- Get Trustable Databricks-Machine-Learning-Professional Latest Exam Cost and Best Accurate Databricks-Machine-Learning-Professional Latest Test Practice 😒 Search for [ Databricks-Machine-Learning-Professional ] and download it for free immediately on ☀ www.prep4sures.top ️☀️ 🦸Databricks-Machine-Learning-Professional Free Braindumps
- Reliable Databricks-Machine-Learning-Professional Exam Online 🤏 Valid Databricks-Machine-Learning-Professional Cram Materials 🛩 Latest Databricks-Machine-Learning-Professional Exam Vce 🤩 Open website “ www.pdfvce.com ” and search for ☀ Databricks-Machine-Learning-Professional ️☀️ for free download 🤩Pdf Databricks-Machine-Learning-Professional Exam Dump
- Databricks-Machine-Learning-Professional New Braindumps Book 🟤 Databricks-Machine-Learning-Professional New Braindumps Book 🐺 Databricks-Machine-Learning-Professional Free Braindumps 🏴 Open ➡ www.vceengine.com ️⬅️ enter ➡ Databricks-Machine-Learning-Professional ️⬅️ and obtain a free download 🛅Reliable Databricks-Machine-Learning-Professional Exam Online
- Databricks-Machine-Learning-Professional Latest Exam Book 📏 Latest Databricks-Machine-Learning-Professional Exam Vce 🦀 Databricks-Machine-Learning-Professional Free Braindumps 🧿 ▶ www.pdfvce.com ◀ is best website to obtain { Databricks-Machine-Learning-Professional } for free download 🩲Databricks-Machine-Learning-Professional Valid Test Voucher
- Will Databricks Databricks-Machine-Learning-Professional Practice Questions help You to Pass the certification exam? 🔁 Copy URL ✔ www.troytecdumps.com ️✔️ open and search for ▷ Databricks-Machine-Learning-Professional ◁ to download for free 🔂Databricks-Machine-Learning-Professional Boot Camp
- 100% Pass Quiz 2026 High-quality Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Latest Exam Cost 🍶 Immediately open ☀ www.pdfvce.com ️☀️ and search for ⇛ Databricks-Machine-Learning-Professional ⇚ to obtain a free download 💫Databricks-Machine-Learning-Professional Clearer Explanation
- Databricks-Machine-Learning-Professional Latest Exam Book 🔶 New Databricks-Machine-Learning-Professional Dumps Ppt 🐓 Databricks-Machine-Learning-Professional Pass Test Guide 🦨 Immediately open [ www.examcollectionpass.com ] and search for ⇛ Databricks-Machine-Learning-Professional ⇚ to obtain a free download 🌌Databricks-Machine-Learning-Professional Clearer Explanation
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, fortunetelleroracle.com, writeablog.net, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by PDFTorrent: https://drive.google.com/open?id=1MFAafwiwrUYjs_0jzvyXbnCSOl_yHjXy