BONUS!!! Download part of RealExamFree Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1TjCZMchS2_qI90O2qkg_JKAqGO3Gl0p9
Do you want to pass your AWS Certified Data Engineer - Associate (DEA-C01) exam? If so, RealExamFree is the ideal place to begin. RealExamFree provides comprehensive Data-Engineer-Associate exam questions preparation in two simple formats: a pdf file format and an Amazon Data-Engineer-Associate online practice test engine. If you fail your AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) Exam, you can obtain a full refund and a 20% discount! Continue reading to discover more about the essential aspects of these excellent Data-Engineer-Associate exam questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Transform and process data
|
| Topic 2: Data Store Management | 26% | - Design data models
|
| Topic 3: Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
| Topic 4: Data Security and Governance | 18% | - Manage data privacy and compliance
|
>> Reliable Data-Engineer-Associate Test Questions <<
Actually, most people do not like learning the boring knowledge. It is hard to understand if our brain rejects taking the initiative. Now, our company has researched the Data-Engineer-Associate study materials, a kind of high efficient learning tool. Firstly, we have deleted all irrelevant knowledge, which decreases your learning pressure. Then, the difficult questions of the Data-Engineer-Associate Study Materials will have vivid explanations. So you will have a better understanding after you carefully see the explanations.
NEW QUESTION # 235
A company has an Amazon Redshift data warehouse that users access by using a variety of IAM roles. More than 100 users access the data warehouse every day.
The company wants to control user access to the objects based on each user's job role, permissions, andhow sensitive the data is.
Which solution will meet these requirements?
Answer: C
Explanation:
Amazon Redshift supportsRole-Based Access Control (RBAC)to manage access to database objects. RBAC allows administrators to create roles for job functions and assign privileges at the schema, table, or column level based on data sensitivity and user roles.
"RBAC in Amazon Redshift helps manage permissions more efficiently at scale by assigning users to roles that reflect their job function. It simplifies user management and secures access based on job role and data sensitivity."
-Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf RBAC is preferred over RLS or CLS alone because it offers a more comprehensive and scalable solution across multiple users and permissions.
NEW QUESTION # 236
A data engineer needs to run a data transformation job whenever a user adds a file to an Amazon S3 bucket.
The job will run for less than 1 minute. The job must send the output through an email message to the data engineer. The data engineer expects users to add one file every hour of the day.
Which solution will meet these requirements in the MOST operationally efficient way?
Answer: A
NEW QUESTION # 237
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Answer: C
Explanation:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using Amazon Timestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
* A. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream.
These steps can increase the latency and complexity of the solution.
* B. Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
* D. Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
References:
* 1: Amazon Managed Streaming for Apache Flink
* 2: Amazon Timestream
* 3: Amazon QuickSight
* : Analyze data in Amazon Timestream using Grafana
* : Amazon Kinesis Data Firehose
* : Amazon Aurora
* : AWS Glue Bookmarks
* : AWS Glue Job and Crawler Scheduling
NEW QUESTION # 238
A company uses Amazon S3 buckets, AWS Glue tables, and Amazon Athena as components of a data lake. Recently, the company expanded its sales range to multiple new states. The company wants to introduce state names as a new partition to the existing S3 bucket, which is currently partitioned by date.
The company needs to ensure that additional partitions will not disrupt daily synchronization between the AWS Glue Data Catalog and the S3 buckets.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
Scheduling an AWS Glue crawler to periodically update the Data Catalog automates the process of detecting new partitions and updating the catalog, which minimizes manual maintenance and operational overhead.
NEW QUESTION # 239
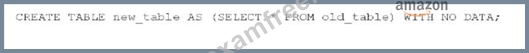
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?



Answer: C
Explanation:
* Problem Analysis:
* The goal is to create a new empty table in Athena with the same schema as an existing table (old_table).
* The solution must avoid copying any data.
* Key Considerations:
* CREATE TABLE AS (CTAS) is commonly used in Athena for creating new tables based on an existing table.
* Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
* Solution Analysis:
* Option A: Copies both schema and data. Does not meet the requirement for an empty table.
* Option B: Inserts data into an existing table, which does not create a new table.
* Option C: Creates an empty table but does not copy the schema.
* Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
* Final Recommendation:
* Use D. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATA to create an empty table with the same schema.
:
Athena CTAS Queries
CREATE TABLE Statement in Athena
NEW QUESTION # 240
......
RealExamFree offers actual and updated Data-Engineer-Associate Dumps after seeing the students struggling to prepare quickly for the test. We have made this product after consulting with a lot of professionals so the students can be successful. RealExamFree has hired a team of professionals who work on a daily basis without caring about themselves to update the Amazon Data-Engineer-Associate practice material.
Questions Data-Engineer-Associate Exam: https://www.realexamfree.com/Data-Engineer-Associate-real-exam-dumps.html
BTW, DOWNLOAD part of RealExamFree Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1TjCZMchS2_qI90O2qkg_JKAqGO3Gl0p9