DOWNLOAD the newest Itbraindumps Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1pzwaXPNltmWnFbKW0ldzaS0vd1dvyJy3
As you can find that on our website, we have three versions of our Databricks-Generative-AI-Engineer-Associate study materials for you: the PDF, Software and APP online. The PDF can be printale. While the Software and APP online can be used on computers. When you find it hard for you to learn on computers, you can learn the printed materials of the Databricks-Generative-AI-Engineer-Associate Exam Questions. What is more, you absolutely can afford fort the three packages. The price is set reasonably. And the Value Pack of the Databricks-Generative-AI-Engineer-Associate practice guide contains all of the three versions with a more favourable price.
| Section | Objectives |
|---|---|
| Foundations of Generative AI | - Large Language Models (LLMs)
|
| Databricks Mosaic AI Platform | - Model development and serving
|
| Responsible AI and Governance | - Model governance
|
| Prompt Engineering | - Prompt evaluation
|
| Retrieval-Augmented Generation (RAG) | - RAG architecture
|
>> Databricks-Generative-AI-Engineer-Associate Latest Exam Preparation <<
To be well-prepared, you require trustworthy and reliable Itbraindumps practice material. You also require accurate Itbraindumps study material to polish your capabilities and improve your chances of passing the Databricks-Generative-AI-Engineer-Associate Certification Exam. Itbraindumps facilitates your study with updated Databricks Databricks-Generative-AI-Engineer-Associate exam dumps.
NEW QUESTION # 80
A Generative Al Engineer is working with a retail company that wants to enhance its customer experience by automatically handling common customer inquiries. They are working on an LLM-powered Al solution that should improve response times while maintaining a personalized interaction. They want to define the appropriate input and LLM task to do this.
Which input/output pair will do this?
Answer: A
Explanation:
The task described in the question involves enhancing customer experience by automatically handling common customer inquiries using an LLM-powered AI solution. This requires the system to process input data (customer inquiries) and generate personalized, relevant responses efficiently. Let's evaluate the options step-by-step in the context of Databricks Generative AI Engineer principles, which emphasize leveraging LLMs for tasks like question answering, summarization, and retrieval-augmented generation (RAG).
Option A: Input: Customer reviews; Output: Group the reviews by users and aggregate per-user average rating, then respond This option focuses on analyzing customer reviews to compute average ratings per user. While this might be useful for sentiment analysis or user profiling, it does not directly address the goal of handling common customer inquiries or improving response times for personalized interactions. Customer reviews are typically feedback data, not real-time inquiries requiring immediate responses.
Databricks Reference: Databricks documentation on LLMs (e.g., "Building LLM Applications with Databricks") emphasizes that LLMs excel at tasks like question answering and conversational responses, not just aggregation or statistical analysis of reviews.
Option B: Input: Customer service chat logs; Output: Group the chat logs by users, followed by summarizing each user's interactions, then respond This option uses chat logs as input, which aligns with customer service scenarios. However, the output-grouping by users and summarizing interactions-focuses on user-specific summaries rather than directly addressing inquiries. While summarization is an LLM capability, this approach lacks the specificity of finding answers to common questions, which is central to the problem.
Databricks Reference: Per Databricks' "Generative AI Cookbook," LLMs can summarize text, but for customer service, the emphasis is on retrieval and response generation (e.g., RAG workflows) rather than user interaction summaries alone.
Option C: Input: Customer service chat logs; Output: Find the answers to similar questions and respond with a summary This option uses chat logs (real customer inquiries) as input and tasks the LLM with identifying answers to similar questions, then providing a summarized response. This directly aligns with the goal of handling common inquiries efficiently while maintaining personalization (by referencing past interactions or similar cases). It leverages LLM capabilities like semantic search, retrieval, and response generation, which are core to Databricks' LLM workflows.
Databricks Reference: From Databricks documentation ("Building LLM-Powered Applications," 2023), an exact extract states: "For customer support use cases, LLMs can be used to retrieve relevant answers from historical data like chat logs and generate concise, contextually appropriate responses." This matches Option C's approach of finding answers and summarizing them.
Option D: Input: Customer reviews; Output: Classify review sentiment
This option focuses on sentiment classification of reviews, which is a valid LLM task but unrelated to handling customer inquiries or improving response times in a conversational context. It's more suited for feedback analysis than real-time customer service.
Databricks Reference: Databricks' "Generative AI Engineer Guide" notes that sentiment analysis is a common LLM task, but it's not highlighted for real-time conversational applications like customer support.
Conclusion: Option C is the best fit because it uses relevant input (chat logs) and defines an LLM task (finding answers and summarizing) that meets the requirements of improving response times and maintaining personalized interaction. This aligns with Databricks' recommended practices for LLM-powered customer service solutions, such as retrieval-augmented generation (RAG) workflows.
NEW QUESTION # 81
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user's query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: B,D
NEW QUESTION # 82
A Generative AI Engineer has deployed a customer-support agent in production that retrieves product documentation and generates responses. SMEs have been reviewing agent responses and providing feedback through a web interface that captures ratings of 1-5 stars and written comments. The engineer needs to systematically collect this feedback and use it to create an evaluation dataset that can be used to compare future agent versions against the current baseline performance.
Which approach should the engineer use to accomplish this task?
Answer: A
Explanation:
Option B preserves the relationships between each user query, generated response, and expert assessment.
That context is necessary to turn production feedback into reusable evaluation cases. The engineer can curate representative examples from the Delta table, map them into MLflow's evaluation schema, and retain the dataset for consistent comparisons between agent versions. Where correctness scoring is required, experts should provide corrected answers or expected facts; a star rating alone is not a ground-truth answer. Keeping only written comments loses essential request context. Selecting only five-star interactions biases the dataset and excludes failure cases that future versions should improve. Deploying highly rated responses is not a substitute for evaluating an updated agent against a stable, representative benchmark. Databricks documentation
NEW QUESTION # 83
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
Answer: A
Explanation:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
NEW QUESTION # 84
A company has a typical RAG-enabled, customer-facing chatbot on its website.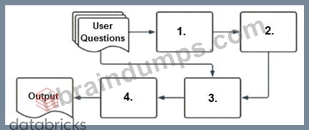
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 85
......
We committed to providing you with the best possible Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice test material to succeed in the Databricks Databricks-Generative-AI-Engineer-Associate exam. With real Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam questions in PDF, customizable Databricks Databricks-Generative-AI-Engineer-Associate practice exams, free demos, and 24/7 support, you can be confident that you are getting the best possible Databricks-Generative-AI-Engineer-Associate Exam Material for the test. Buy today and start your journey to Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam success with Itbraindumps!
Latest Databricks-Generative-AI-Engineer-Associate Test Materials: https://www.itbraindumps.com/Databricks-Generative-AI-Engineer-Associate_exam.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Itbraindumps: https://drive.google.com/open?id=1pzwaXPNltmWnFbKW0ldzaS0vd1dvyJy3