2026 Latest PassTestking DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=17HDz4P8LNInHPvUcJVRN-TPLQ0l_13vy
Our DP-100 training quiz will be your best teacher who helps you to find the key and difficulty of the exam, so that you no longer feel confused when review. Our DP-100 study materials will be your best learning partner and will accompany you through every day of the review. Our DP-100 Exam Quiz will help you to deal with all the difficulties you have encountered in the learning process and make you walk more easily and happily on the road of studying.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Explore data and run experiments | 20-25% | - Implement pipelines
|
| Topic 2: Design and prepare a machine learning solution | 20-25% | - Manage compute resources
|
| Topic 3: Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
|
| Topic 4: Train and deploy models | 25-30% | - Manage models
|
If you want to ace the Designing and Implementing a Data Science Solution on Azure (DP-100) test, the main problem you may face is not finding updated DP-100 practice questions to crack this test quickly. After examining the situation, the PassTestking has come with the idea to provide you with updated and actual Sitecore DP-100 Exam Dumps so you can pass DP-100 test on the first attempt.
NEW QUESTION # 111
You use the Azure Machine Learning designer to create and run a training pipeline.
The pipeline must be run every night to inference predictions from a large volume of files. The folder where the files will be stored is defined as a dataset.
You need to publish the pipeline as a REST service that can be used for the nightly inferencing run.
What should you do?
Answer: B
Explanation:
Azure Machine Learning Batch Inference targets large inference jobs that are not time-sensitive.
Batch Inference provides cost-effective inference compute scaling, with unparalleled throughput for asynchronous applications. It is optimized for high-throughput, fire-and-forget inference over large collections of data.
You can submit a batch inference job by pipeline_run, or through REST calls with a published pipeline.
Reference:
https://github.com/Azure/MachineLearningNotebooks/blob/master/how-to-use-azureml/machine- learning-pipelines/parallel-run/README.md
NEW QUESTION # 112
You need to configure the Permutation Feature Importance module for the model training requirements.
What should you do? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.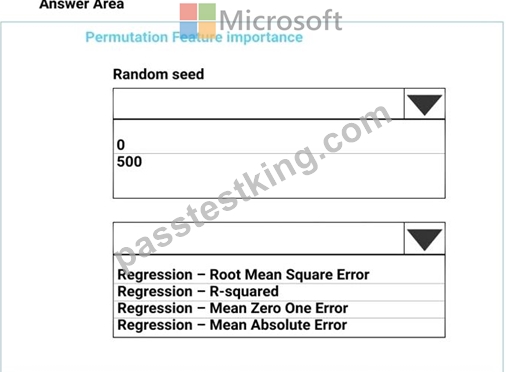
Answer:
Explanation: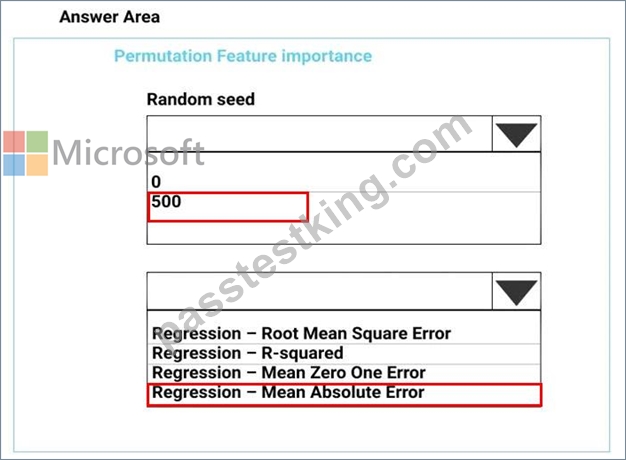
Explanation:
Box 1: 500
For Random seed, type a value to use as seed for randomization. If you specify 0 (the default), a number is generated based on the system clock.
A seed value is optional, but you should provide a value if you want reproducibility across runs of the same experiment.
Here we must replicate the findings.
Box 2: Mean Absolute Error
Scenario: Given a trained model and a test dataset, you must compute the Permutation Feature Importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
Regression. Choose one of the following: Precision, Recall, Mean Absolute Error , Root Mean Squared Error, Relative Absolute Error, Relative Squared Error, Coefficient of Determination References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance
NEW QUESTION # 113
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.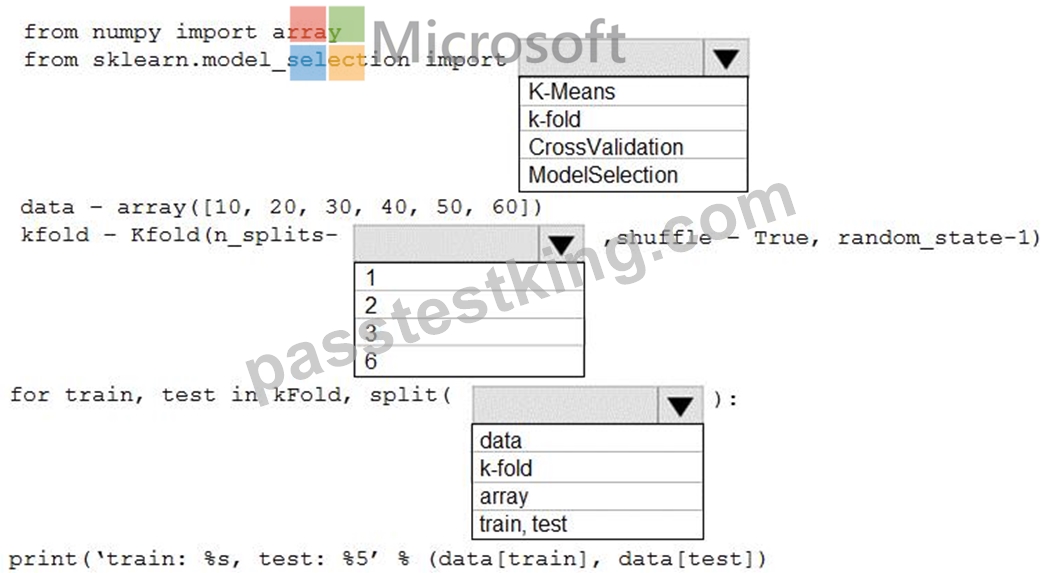
Answer:
Explanation: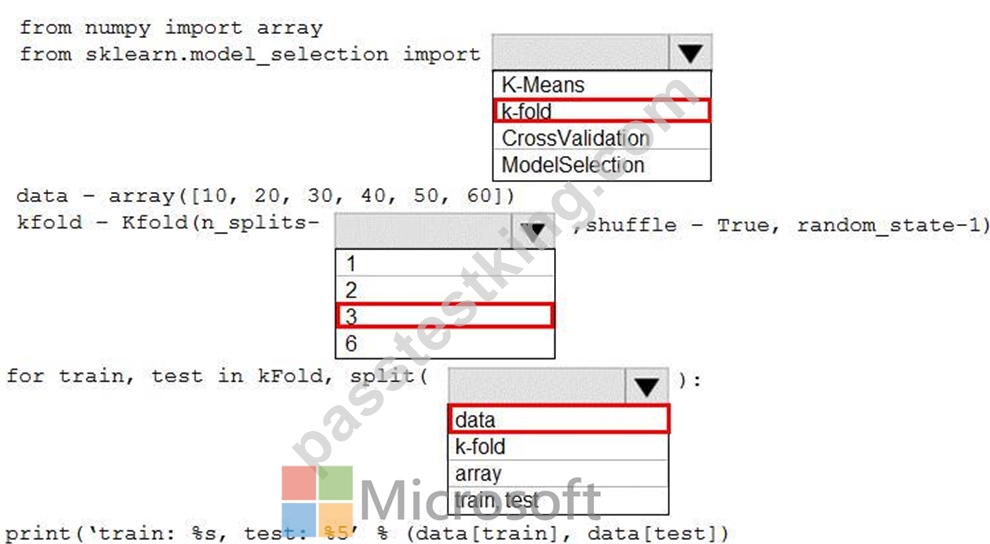
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
NEW QUESTION # 114
You register a file dataset named csvjolder that references a folder. The folder includes multiple com ma-separated values (CSV) files in an Azure storage blob container. You plan to use the following code to run a script that loads data from the file dataset. You create and instantiate the following variables: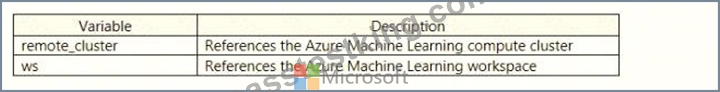
You have the following code: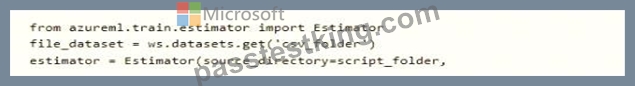
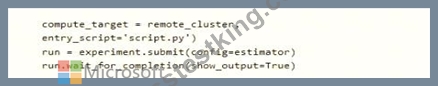
You need to pass the dataset to ensure that the script can read the files it references. Which code segment should you insert to replace the code comment?


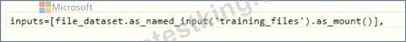

Answer: A
Explanation:
Explanation
Example:
from azureml.train.estimator import Estimator
script_params = {
# to mount files referenced by mnist dataset
'--data-folder': mnist_file_dataset.as_named_input('mnist_opendataset').as_mount(),
'--regularization': 0.5
}
est = Estimator(source_directory=script_folder,
script_params=script_params,
compute_target=compute_target,
environment_definition=env,
entry_script='train.py')
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-train-models-with-aml
NEW QUESTION # 115
You have an Azure Machine Learning workspace.
You have the following code: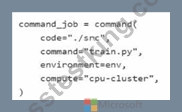
You plan to rely on serverless compute to train a model by using Azure Machine Learning Python SDK v2.
The serverless compute must use a designated number of nodes of a specific virtual machine type.
You need to modify the code to run the training job according to the plan.
How should you modify the command object? To answer, select the appropriate oations in the answer area.
NOTE: Each correct selection is worth one point.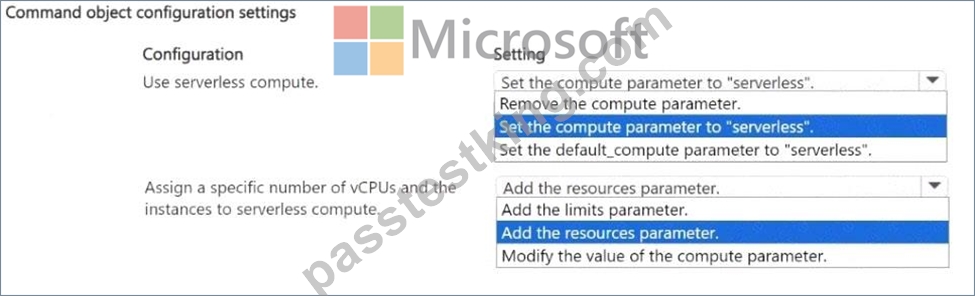
Answer:
Explanation: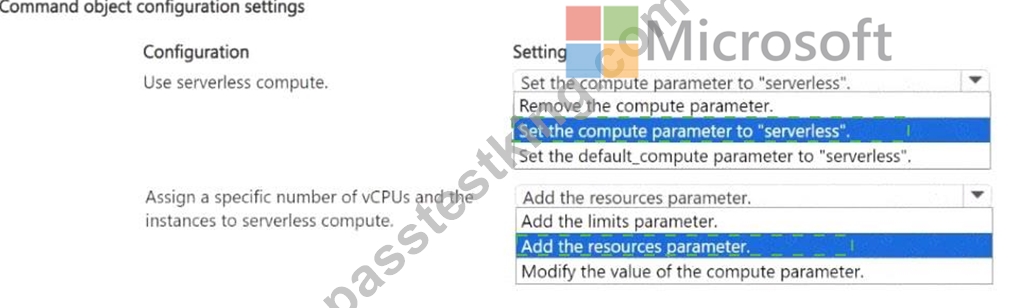
Explanation: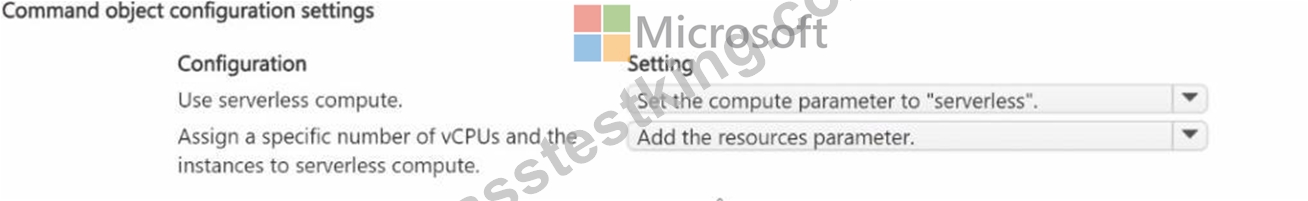
NEW QUESTION # 116
......
We have three versions packages of the DP-100 exam questions to help you comprehensively. Also, all contents are carefully prepared by our researchers. So you needn’t to read and memorize the boring reference books of the DP-100 Exam. Most people have successfully passed the exam under the assistance of our study materials. So try to trust us. Our DP-100 study materials will help you generate a wonderful life.
DP-100 Best Study Material: https://www.passtestking.com/Microsoft/DP-100-practice-exam-dumps.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by PassTestking: https://drive.google.com/open?id=17HDz4P8LNInHPvUcJVRN-TPLQ0l_13vy