What's more, part of that Exam4Tests Mule-Arch-201 dumps now are free: https://drive.google.com/open?id=1I44hSLgoOaezuPMgGLeA5OCo5asQRxsb
Being devoted to this area for over ten years, our experts keep the excellency of our Salesforce Certified MuleSoft Platform Architect exam question like always. They are distinguished experts in this area who can beef up your personal capacity. By cutting through the clutter of tremendous knowledge, they picked up the essence into our Mule-Arch-201 guide prep. Up to now our Mule-Arch-201 real exam materials become the bible of practice material of this industry. Ten years have gone, and three versions have been made for your reference. They made the biggest contribution to the efficiency and quality of our Salesforce Certified MuleSoft Platform Architect practice materials, and they were popularizing the ideal of passing the exam easily and effectively. All Mule-Arch-201 Guide prep is the successful outcomes of professional team.
| Section | Objectives |
|---|---|
| Integration Architecture Strategy | - Designing enterprise integration architecture - API-led connectivity principles - System, process, and experience APIs |
| Anypoint Platform Architecture | - Anypoint Platform components and capabilities - Deployment models (CloudHub, hybrid, on-premises) - Runtime Fabric architecture overview |
| Data Integration and Transformation | - Data mapping and transformation strategies - Batch vs real-time integration patterns |
| Security and Compliance | - Secure API exposure and threat protection - Authentication and authorization mechanisms |
| API Management and Governance | - Governance frameworks and best practices - API security policies and enforcement - API lifecycle management |
| Performance and Scalability | - High availability design patterns - Scaling Mule applications |
>> Reliable Mule-Arch-201 Test Materials <<
Our Mule-Arch-201 study materials include 3 versions and they are the PDF version, PC version, APP online version. You can understand each version's merits and using method in detail before you decide to buy our Mule-Arch-201 study materials. For instance, PC version of our Mule-Arch-201 training quiz is suitable for the computers with the Windows system and supports the MS Operation System. It is a software application which can be installed and it stimulates the real exam’s environment and atmosphere. It builds the users’ confidence and the users can practice and learn our Mule-Arch-201 learning guide at any time.
NEW QUESTION # 144
A retail company with thousands of stores has an API to receive data about purchases and insert it into a single database. Each individual store sends a batch of purchase data to the API about every 30 minutes. The API implementation uses a database bulk insert command to submit all the purchase data to a database using a custom JDBC driver provided by a data analytics solution provider. The API implementation is deployed to a single CloudHub worker. The JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker, and then the data is sent to an analytics engine using a proprietary protocol. This process usually takes less than a few minutes. Sometimes a request fails. In this case, the logs show a message from the JDBC driver indicating an out-of-file-space message. When the request is resubmitted, it is successful. What is the best way to try to resolve this throughput issue?
Answer: D
Explanation:
Correct Answe r: Increase the size of the CloudHub worker(s)
*****************************************
The key details that we can take out from the given scenario are:
>> API implementation uses a database bulk insert command to submit all the purchase data to a database
>> JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker
>> Sometimes a request fails and the logs show a message indicating an out-of-file-space message Based on above details:
>> Both auto-scaling options does NOT help because we cannot set auto-scaling rules based on error messages. Auto-scaling rules are kicked-off based on CPU/Memory usages and not due to some given error or disk space issues.
>> Increasing the number of CloudHub workers also does NOT help here because the reason for the failure is not due to performance aspects w.r.t CPU or Memory. It is due to disk-space.
>> Moreover, the API is doing bulk insert to submit the received batch data. Which means, all data is handled by ONE worker only at a time. So, the disk space issue should be tackled on "per worker" basis. Having multiple workers does not help as the batch may still fail on any worker when disk is out of space on that particular worker.
Therefore, the right way to deal this issue and resolve this is to increase the vCore size of the worker so that a new worker with more disk space will be provisioned.
NEW QUESTION # 145
What CANNOT be effectively enforced using an API policy in Anypoint Platform?
Answer: B
Explanation:
Correct Answe r: Guarding against Denial of Service attacks
*****************************************
>> Backend system overloading can be handled by enforcing "Spike Control Policy"
>> Logging HTTP requests and responses can be done by enforcing "Message Logging Policy"
>> Credentials can be tamper-proofed using "Security" and "Compliance" Policies However, unfortunately, there is no proper way currently on Anypoint Platform to guard against DOS attacks.
NEW QUESTION # 146
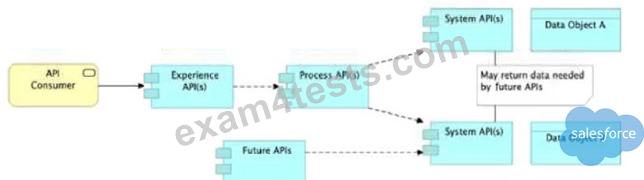
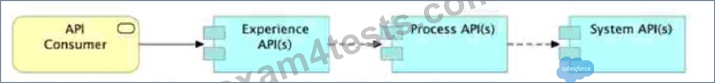
Refer to the exhibits.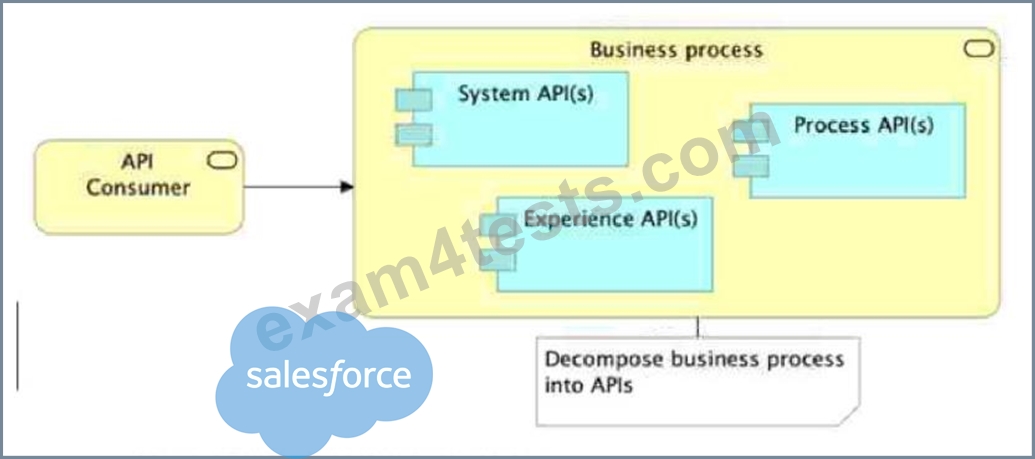
Which architectural constraint is compatible with the API-led connectivity architectural style?
Answer: C
Explanation:
Understanding API-led Connectivity Layers:
In MuleSoft's API-led connectivity approach, APIs are categorized into three layers:
Experience Layer: This layer is responsible for providing data to the end-user applications and is often customized to meet the needs of different user interfaces.
Process Layer: This layer is used to orchestrate and combine data from multiple System APIs. It acts as a mediator and business logic layer without directly interacting with the backend systems.
System Layer: This layer provides direct access to the backend systems (e.g., databases, ERPs) and is usually focused on exposing atomic data operations.
Evaluating the Architectural Constraints:
Option A: Always using a strict tiered approach by creating exactly one API per layer is not necessarily an architectural constraint of API-led connectivity. While a layered approach is recommended, it is common to have multiple APIs in each layer as needed for different functionalities.
Option B (Correct Answer): In API-led connectivity, Process APIs are generally responsible for orchestrating calls to System APIs and should not call other Process APIs. This maintains a clear separation of concerns, ensuring that Process APIs aggregate data from System APIs only and provide it to Experience APIs.
Option C: System APIs are generally designed to provide only the necessary data to meet current business requirements. Allowing them to return extra data that is not needed by Process or Experience APIs is not a best practice, as it can lead to inefficiencies.
Option D: Customizations specific to end-user applications are typically handled at the Experience Layer rather than the Process Layer, as the Experience Layer is intended to tailor the data to fit the needs of each specific client or front-end application.
Conclusion:
Option B is the correct answer as it aligns with the API-led connectivity principles. In this architectural style, Process APIs should orchestrate System APIs but should avoid interacting with other Process APIs to keep a clear separation of responsibilities across the layers.
For additional details, refer to MuleSoft documentation on API-led connectivity best practices, particularly around the roles of each layer in API orchestration and data handling.
NEW QUESTION # 147
A company is building an application network using MuleSoft's recommendations for various API layers.
What is the main (default) role of a process API in an application network?
Answer: B
Explanation:
Role of Process API in API-led Connectivity:
In MuleSoft's API-led connectivity approach, a Process API is used to coordinate, aggregate, and orchestrate data from various System APIs. It is primarily responsible for implementing business logic that spans multiple backend systems or entities, transforming and combining data as needed to support business processes.
Process APIs are not directly exposed to end-user clients; rather, they work between System APIs and Experience APIs, providing business logic and orchestration capabilities.
Evaluating the Options:
Option A: Process APIs are not typically responsible for large data dumps or data synchronization. That function would be handled by a System API or a specialized batch process.
Option B: Managing direct, secure communication between back-end systems and end-user clients is typically the role of Experience APIs rather than Process APIs.
Option C (Correct Answer): Process APIs are designed to coordinate and orchestrate calls to multiple other APIs in the network, which supports the automation of business processes.
Option D: Securing and managing communication with end-user clients is typically the role of Experience APIs, not Process APIs.
Conclusion:
Option C is the correct answer, as the main role of a Process API is to coordinate and orchestrate interactions between other APIs, enabling business processes to function seamlessly across multiple systems.
Refer to MuleSoft's API-led connectivity documentation for further explanation of the roles and responsibilities of Process APIs in an application network.
NEW QUESTION # 148
A large lending company has developed an API to unlock data from a database server and web server. The API has been deployed to Anypoint Virtual Private Cloud (VPC) on CloudHub 1.0.
The database server and web server are in the customer's secure network and are not accessible through the public internet. The database server is in the customer's AWS VPC, whereas the web server is in the customer's on-premises corporate data center.
How can access be enabled for the API to connect with the database server and the web server?
Answer: A
Explanation:
Scenario Overview:
The API resides in Anypoint Virtual Private Cloud (VPC) on CloudHub 1.0, where it requires connectivity to both an AWS-hosted database server and an on-premises web server.
Both servers are isolated from the public internet: the database server is within the customer's AWS VPC, and the web server is within the customer's on-premises corporate data center.
Connectivity Requirements:
To connect to the AWS database server from the API in Anypoint VPC, VPC peering is ideal. This would allow a private network connection between the MuleSoft Anypoint VPC and the customer's AWS VPC, enabling secure, direct access to the database.
To connect to the on-premises web server, a VPN tunnel is suitable. This would establish a secure, encrypted connection from the Anypoint VPC to the customer's corporate data center, allowing secure data flow between the API and the on-premises web server.
Analysis of Options:
Option A (Correct Answer): Setting up VPC peering with AWS VPC enables private network connectivity with the database server, while a VPN tunnel to the on-premises data center allows secure access to the web server. This combination meets the requirements for secure, controlled access to both resources.
Option B: VPC peering alone would not suffice because it does not support a connection from the Anypoint VPC directly to an on-premises network. A VPN is necessary for on-premises access.
Option C: Setting up a transit gateway would provide connectivity within AWS but would not enable direct connectivity from CloudHub to the on-premises network.
Option D: VPC peering with the on-premises network is not possible because VPC peering is typically used to connect two VPCs, not a VPC with an on-premises network.
Conclusion:
Option A is the correct choice, as it provides a complete solution by using VPC peering for AWS VPC connectivity and a VPN tunnel for secure on-premises connectivity. This setup aligns with Anypoint Platform best practices for connecting Anypoint VPCs to both AWS-hosted and on-premises systems, ensuring secure, controlled access to both the database and web server.
For more detailed reference, MuleSoft documentation on Anypoint VPC peering and VPN connectivity provides additional context on best practices for setting up these connections within a hybrid network infrastructure.
NEW QUESTION # 149
......
As is known to us, a suitable learning plan is very important for all people. For the sake of more competitive, it is very necessary for you to make a learning plan. We believe that our Mule-Arch-201 actual exam will help you make a good learning plan. You can have a model test in limited time by our Mule-Arch-201 Study Materials, if you finish the model test, our system will generate a report according to your performance. And in this way, you can have the best pass percentage on your Mule-Arch-201 exam.
Mule-Arch-201 Reliable Test Pdf: https://www.exam4tests.com/Mule-Arch-201-valid-braindumps.html
BTW, DOWNLOAD part of Exam4Tests Mule-Arch-201 dumps from Cloud Storage: https://drive.google.com/open?id=1I44hSLgoOaezuPMgGLeA5OCo5asQRxsb