当社Microsoftが採用した「小利益」の方針により、すべてのお客様と当社の間で双方に有利な状況を達成することを目指しているため、AI-200のすべてのお客様の信頼を獲得することができました。 当社Japancertが長年にわたってこのAI-200試験問題の分野で業界のリーダーになっており、当社のAI-200試験のDeveloping AI Cloud Solutions on Azure教材が世界中でこんなに迅速に販売されているにもかかわらず、手頃な価格を維持しているのはそのためです。 すべてのお客様向けのAI-200学習ガイドであり、有名なブランドを活用したくない。
| Section | Objectives |
|---|---|
| Topic 1: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 2: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 3: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 4: Connect to and consume Azure services | - Integrate Azure services
|
AI-200スタディガイドの優れた利点の1つは、高い合格率です。これは99%に達し、同業他社の平均合格率よりもはるかに高くなっています。当社の高い合格率は、当社が業界トップのAI-200準備ガイドである理由を説明しています。自信の源は、素晴らしいAI-200試験問題です。 AI-200学習教材の練習を約20〜30時間続ける限り、試験に合格しても問題はありません。私たちの専門家は、実際の試験問題に合わせてAI-200の質問と回答を設計しました。これは、高い能力で試験に合格するのに役立ちます。
質問 # 122
You are troubleshooting a production Azure OpenAI service that is experiencing intermittent connectivity issues. All telemetry is sent to a Log Analytics workspace.
You must write a KQL query that analyzes the AppRequests table. The query must filter for requests that occurred within the last 30 minutes and have a failed status.
The final output must display the total number of failures for each unique operation.
You need to select the KQL operators required to filter the time range and aggregate the failure counts.
Which two operators should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:A、B
解説:
You should use both the where and summarize operators to achieve this. The where operator filters the data by time and status, while the summarize operator aggregates the failure counts by operation.
Example code:
AppRequests
| where TimeGenerated > ago(30m)
| where Success == false
| summarize FailureCount = count() by OperationName
Reference:
https://digitalmaterial.ch/blog/query-data-from-the-application-insights-workspace-with-the-rest-api/
質問 # 123
You are designing an Azure Database for PostgreSQL table for semantic search. Queries frequently filter on the created_at column. The schema must support vector similarity search and reliable date filtering You need to ensure that the table meets the requirements.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two NOTE: Each correct selection is worth one point.
正解:B、C
解説:
Detailed Explanation: A semantic-search schema should use the pgvector vector type for embeddings so PostgreSQL can apply vector distance operators and vector indexes. The creation timestamp should use an actual timestamp data type so comparisons, range predicates, ordering, and indexes use date semantics rather than string ordering. Storing vectors or dates as free-form character data would sacrifice type validation and make similarity or date filtering less efficient and less reliable.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
質問 # 124
A company is implementing a publish-subscribe (Pub/Sub) messaging component by using Azure Service Bus. You are developing the first subscription application.
In the Azure portal you see that messages are being sent to the subscription for each topic. You create and initialize a subscription client object by supplying the correct details, but the subscription application is still not consuming the messages.
You need to ensure that the subscription client processes all messages.
Which code segment should you use?
正解:A
解説:
Detailed Explanation: Creating a subscription client establishes the client object but does not start application-level message processing. The message handler must be registered so received subscription messages are delivered to the application callback. Adding a default TrueFilter is only necessary when subscription rules require adjustment and does not start the receiver; the default subscription rule already accepts messages in a normal subscription. Closing the client would stop processing rather than enable it.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message transfers, locks, and settlement
質問 # 125
You are developing a solution that uses several Azure Service Bus queues. You create an Azure Event Grid subscription for the Azure Service Bus namespace. You use Azure Functions as subscribers to process the messages.
You need to ensure that events can be sent to Azure Event Grid from the queues. The solution must use the principle of least privilege and minimize costs.
Which Azure Service Bus role and tier level should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.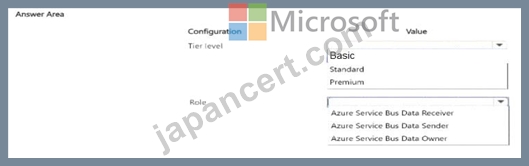
正解:
解説: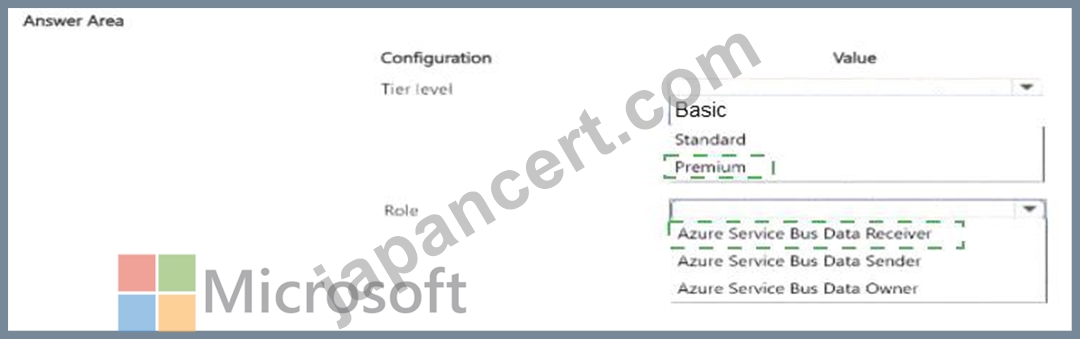
Explanation: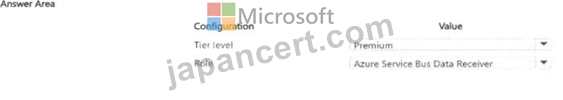
Verified answer: Tier: Premium. Role: Azure Service Bus Data Receiver.
Detailed Explanation: Microsoft documents Event Grid integration for Service Bus queues and topics as requiring a Service Bus Premium namespace. The Azure Function subscriber must then receive messages from the queue; the least-privilege built-in data-plane role for that purpose is Azure Service Bus Data Receiver. Data Sender does not permit receiving, and Data Owner is broader than necessary. Premium therefore satisfies the feature prerequisite, while Data Receiver satisfies the stated least-privilege requirement.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus to Event Grid integration | Authenticate Service Bus with Microsoft Entra ID
質問 # 126
You are implementing the expiration requirement for AI-generated summaries in the Redis cache.
You need to purge the AI summaries five minutes after creation, regardless of how often they are accessed.
What should you do?
正解:B
解説:
TTL (Time-To-Live) with a fixed duration of five minutes is the exact Redis feature you need to purge AI-generated summaries regardless of access frequency.
Redis TTL and Expiration Features
Core Expiration Feature
EXPIRE command: Sets a timeout in seconds on a key. Use EXPIRE key 300 to remove the summary after 300 seconds (five minutes).
PX command: Sets a timeout in milliseconds. Use PX key 300000 for precise millisecond control.
EXPIREAT / PEXPIREAT: Sets an absolute Unix timestamp for expiration instead of a relative duration.
Reference:
https://dev.to/truongpx396/30-common-redis-interview-questions-1ai
質問 # 127
......
時間が経つとともに、Japancertはより多くの受験生から大好評を博します。弊社のAI-200資料は99%の成功率を持っていますから、弊社のMicrosoftのAI-200練習問題を利用したら、最もよい結果を得ることができます。弊社のAI-200練習問題さえ使用すれば試験の成功までもっと近くなります。
AI-200試験番号: https://www.japancert.com/AI-200.html