2026 Latest PassLeader AI-200 PDF Dumps and AI-200 Exam Engine Free Share: https://drive.google.com/open?id=1eoWaHar5rlmTeFZ5YbUndkjupBZNs8_Y
You can take multiple Developing AI Cloud Solutions on Azure AI-200 practice exam attempts and identify and overcome your mistakes. Furthermore, through Developing AI Cloud Solutions on Azure AI-200 practice test software you will improve your time-management skills. You will easily manage your time while attempting the Actual AI-200 Test.
| Section | Objectives |
|---|---|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
The customizable mock tests make an image of a real-based Developing AI Cloud Solutions on Azure (AI-200) exam which is helpful for you to overcome the pressure of taking the final examination. Customers of PassLeader can take multiple Microsoft AI-200 practice tests and improve their preparation to achieve the AI-200 Certification. You can even access your previously given tests from the history, which allows you to be careful while giving the mock test next time and prepare for Microsoft AI-200 certification in a better way.
NEW QUESTION # 47
You need to ensure that responses from your Azure OpenAI application include citations back to the specific source documents used, to support user trust and verification.
What should you implement?
Answer: A
Explanation:
A retrieval-augmented generation (RAG) architecture is the correct mechanism when generated answers must be traceable to specific source documents. RAG first retrieves relevant document chunks from a search index or other knowledge source, supplies those chunks to the language model as grounding context, and then generates an answer based on that retrieved information. Microsoft specifically documents that RAG enables responses containing citations back to source content .
For reliable citation generation, each retrieved chunk should carry identifying metadata such as a source identifier, document title, section, page, or URL . Microsoft's Azure RAG guidance recommends labeling retrieved chunks and including source metadata with them, then explicitly instructing the model to cite the corresponding sources in its response. This allows users to verify individual claims against the underlying documents.
Modern Azure AI Search agentic retrieval can also return structured references and grounding metadata , specifically designed for citation linking.
Increasing top_p only alters token sampling. Content filtering addresses safety, not provenance. Using a base model without retrieval provides no authoritative document linkage.
Study Guide references: RAG architecture; grounding data; retrieval metadata; Azure AI Search references; prompt engineering for citations.
NEW QUESTION # 48
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.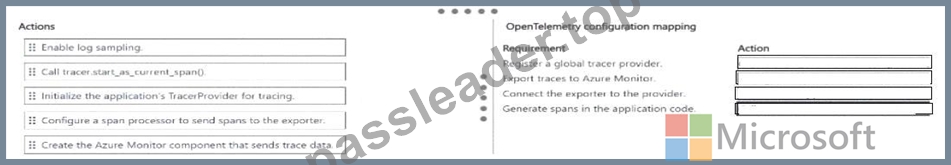
Answer:
Explanation: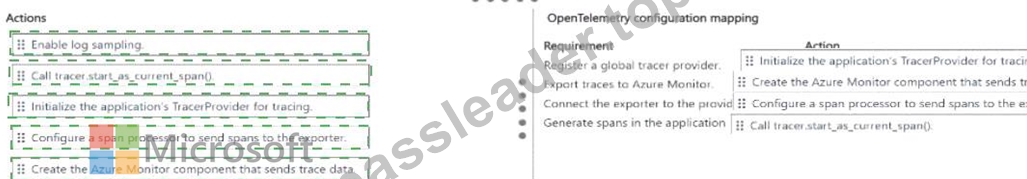
Explanation:
Verified Answer: Register a global trace provider # initialize the application TraceProvider. Export traces to Azure Monitor # create/configure AzureMonitorTraceExporter. Connect exporter to provider # add a span processor. Generate spans # use tracer.start_as_current_span(...).
Detailed Explanation: OpenTelemetry tracing is a pipeline: the application obtains a tracer from a configured provider, creates spans, passes ended spans through a span processor, and exports them using the Azure Monitor exporter. Creating spans alone is insufficient; without the provider/processor/exporter chain, no telemetry reaches Azure Monitor. Log sampling and legacy Application Insights TrackEvent calls are unrelated to the required OpenTelemetry trace-export path.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 49
You maintain multiple versions of a container image in Azure Container Registry.
The production deployment must always run the exact same image build even if tags are changed later.
You need to ensure predictable and immutable image selection during deployment.
What should you do?
Answer: A
Explanation:
Deploying a container image by its unique SHA-256 digest digest instead of its tag ensures a predictable and immutable deployment. Tags can be overwritten or moved to different image builds, but a digest is a cryptographic hash that never changes.
Reference:
https://container-registry.com/posts/container-image-versioning/
NEW QUESTION # 50
A RAG application ' s retrieval step is returning documents that are topically related but not precisely relevant to the user ' s question.
You need to improve retrieval precision without retraining any model.
What should you do?
Answer: D
Explanation:
Enable semantic ranking in Azure AI Search . Semantic ranking is a query-time secondary re-ranking stage that evaluates the initial candidate results using Microsoft language-understanding models and promotes documents that are more semantically aligned with the user ' s actual query intent. It can operate over BM25 results, hybrid results, and the textual content associated with vector-search results.
This directly addresses the stated problem. Vector similarity retrieval often has strong recall but can return passages that are broadly related rather than specifically useful for answering the question. Microsoft ' s RAG guidance explains that reranking improves precision by taking the retrieved candidate set and reordering it so that the most query-relevant chunks are placed first. This reduces irrelevant context passed to the generation model and improves grounding quality without retraining either the embedding model or the LLM.
Increasing embedding dimensionality alone does not guarantee better relevance. Disabling vector search sacrifices semantic retrieval capability, while reducing the index size arbitrarily removes potentially useful content rather than improving ranking quality.
Therefore, semantic re-ranking is the correct precision-improvement mechanism .
Study Guide references: Azure AI Search # semantic ranker; RAG information retrieval; hybrid/vector search; secondary ranking; relevance optimization.
NEW QUESTION # 51
You are investigating high latency in an AI search application that processes millions of requests daily.
Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
* Include only data from the last 24 hours.
* Filter for failed requests only.
* Calculate the average duration of dependencies, grouped by operation.
The query must follow best practice to optimize the performance by minimizing the initial data scan.
You need to create the query.
In which order should perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.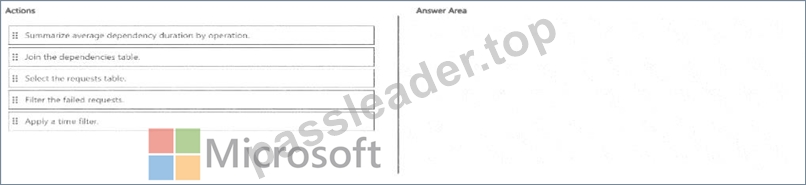
Answer:
Explanation: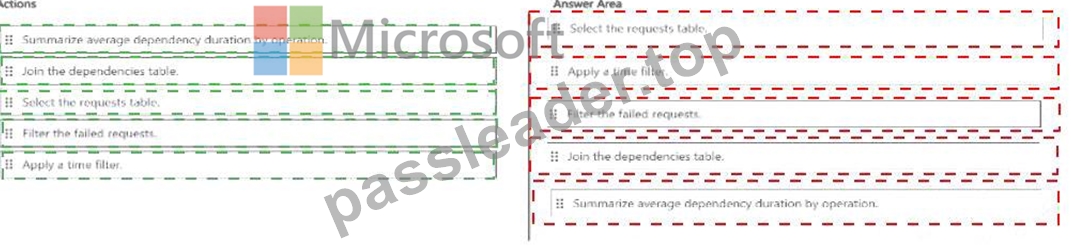
Explanation: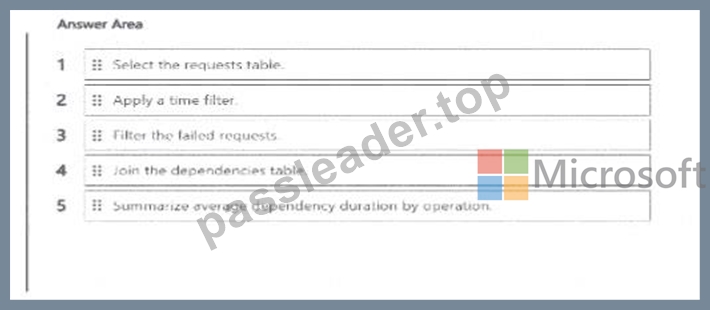
Verified Answer: 1) Select the requests table; 2) apply the 24-hour time filter; 3) filter failed requests; 4) join the dependencies table; 5) summarize average dependency duration by operation.
Detailed Explanation: KQL performs best when high-selectivity filters are applied as early as possible, especially the time predicate that limits the amount of data scanned. Starting from AppRequests, restricting to the last 24 hours, and then filtering failures reduces the left-side dataset before the join. The dependency table is then correlated with those requests, and aggregation is performed last to calculate average dependency duration by operation. Joining or summarizing before the time and failure filters would process more data than necessary.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Optimize log queries in Azure Monitor
NEW QUESTION # 52
......
PassLeader constantly attract students to transfer their passion into progresses for the worldwide feedbacks from our loyal clients prove that we are number one in this field to help them achieve their dream in the AI-200 exams. For we have the guarantee of high quality on our AI-200 exam questions, so our AI-200 practice materials bring more outstanding teaching effect. And instead of the backward information accumulation of learning together can make students feel great burden, our latest AI-200 exam guide can meet the needs of all kinds of students on validity or accuracy.
AI-200 Examcollection: https://www.passleader.top/Microsoft/AI-200-exam-braindumps.html
BTW, DOWNLOAD part of PassLeader AI-200 dumps from Cloud Storage: https://drive.google.com/open?id=1eoWaHar5rlmTeFZ5YbUndkjupBZNs8_Y