Developing AI-Enabled Database Solutions DP-800は、技術的な精度の最高水準を高め、認定された主題と専門家のみを使用します。最新の正確なDP-800試験トレントをクライアントに提供し、提供する質問と回答は実際の試験に基づいています。合格率が高く、約98%-100%であることをお約束します。また、DP-800テストブレインダンプは高いヒット率を高め、試験を刺激してDP-800試験の準備を整えることができます。あなたの成功は、DP-800試験問題に縛られています。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
DP-800試験準備が高い合格率であるだけでなく、当社のサービスも完璧であるため、当社の製品を購入すると便利です。さらに、このアップデートでは、最新かつ最も有用なDP-800試験ガイドを提供し、より多くのことを学び、さらにマスターすることを支援します。販売前後のさまざまなバージョンを選択できる優れたカスタマーサービスを提供しています。無料デモをダウンロードして、購入前にDP-800ガイドトレントの品質を確認できます。 DP-800試験問題の購入に失望することはありません。
質問 # 82
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.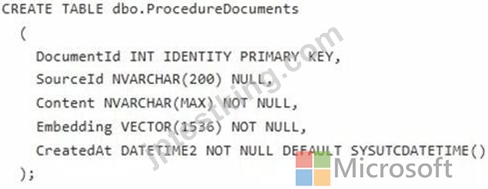
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.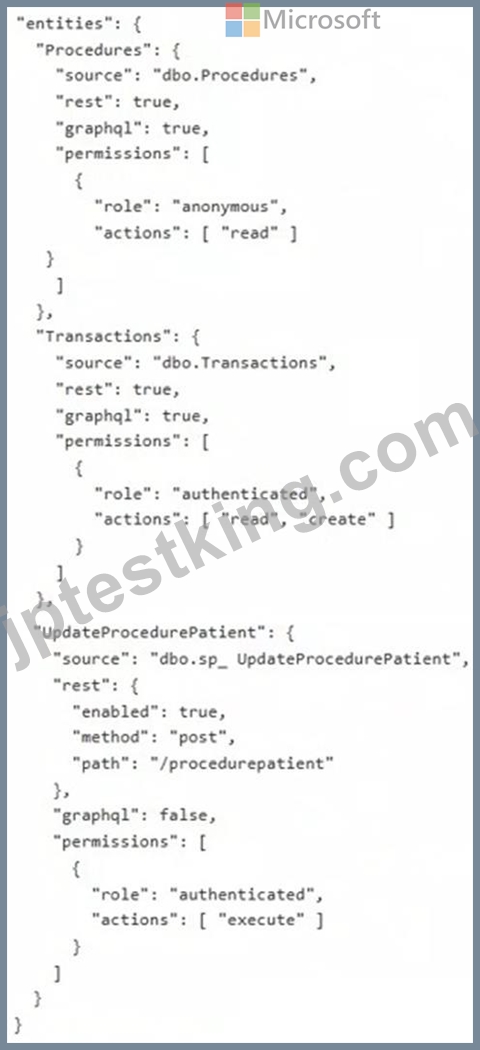
Hotspot Question
You create an SDK-style SQL database project in Microsoft Visual Studio Code named Database.sqlproj and add the project to a GitHub repository.
You need to configure a GitHub Actions workflow to support the planned changes for DB1.
How should you complete the workflow? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.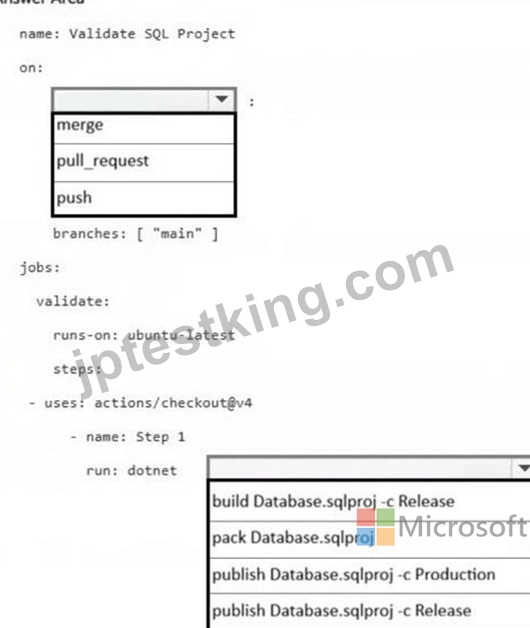
正解:
解説: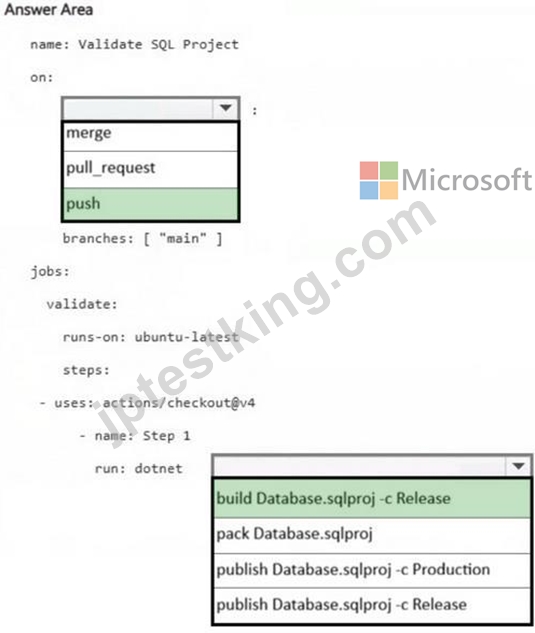
質問 # 83
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution: Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(nonth, -36, SYSUTCDATETIME());
Does this meet the goal?
正解:A
解説:
This does not meet the goal. A row-by-row DELETE against the oldest month is not the lowest-impact way to purge data from a monthly partitioned table. Microsoft's partitioning guidance specifically says partitioning lets you perform maintenance and retention operations more efficiently by targeting just the relevant partition, including the ability to truncate data in a single partition .
The proposed statement:
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
would log row deletions and can hold locks longer, creating more overhead for other queries than a partition- level maintenance operation. Since the table is already partitioned by month , the expected low-impact approach is to operate on the oldest partition directly, not issue a broad delete predicate over rows. Microsoft explicitly highlights partition-targeted truncation as a faster, more efficient retention operation than working against the whole table or rowset.
質問 # 84
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
正解:B、D
解説:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft's JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design.
Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam- consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
* Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
* A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
* Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.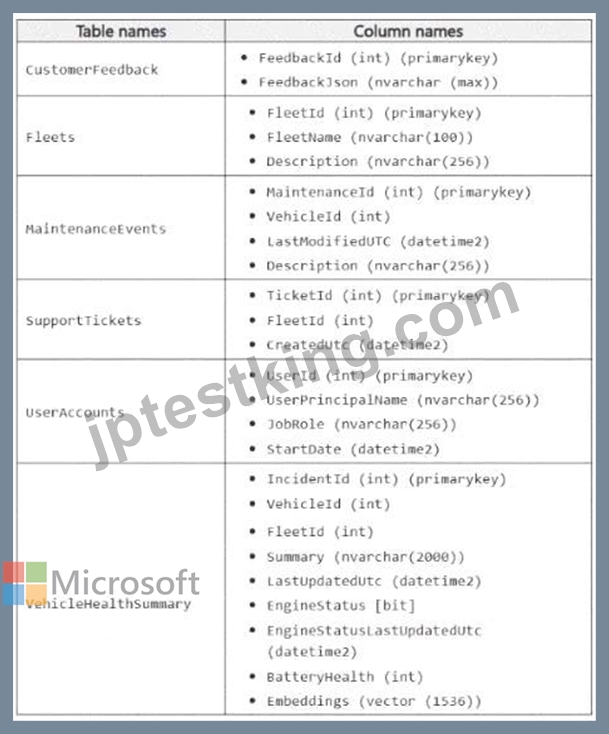
The FeedbackJson column has a full-text index and stores JSON documents in the following format.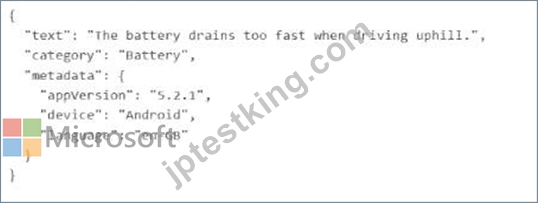
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
質問 # 85
You have a SQL database in Microsoft Fabric that contains a column named Payload. pay load stores customer data in JSON documents that have the following format.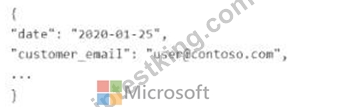
Data analysis shows that some customers have subaddressing in their email address, for example, user1+promo@contoso.com.
You need to return a normalized email value that removes the subaddressing, for example, user! + promo@contoso.com must be normalized to userl@contoso.com.
Which Transact SQL expression should you use?