What's more, part of that DumpStillValid NCM-MCI-6.10 dumps now are free: https://drive.google.com/open?id=1havzBBCBtyjTVI1XrK2X8FZbZPk4e4Ej
In order to make all customers feel comfortable, our company will promise that we will offer the perfect and considerate service for all customers. If you buy the NCM-MCI-6.10 study materials from our company, you will have the right to enjoy the perfect service. We have employed a lot of online workers to help all customers solve their problem. If you have any questions about the NCM-MCI-6.10 Study Materials, do not hesitate and ask us in your anytime, we are glad to answer your questions and help you use our NCM-MCI-6.10 study materials well.
| Section | Weight | Objectives |
|---|---|---|
| Network Performance and Security | 20% | - Tune overlay networking and traffic flow - Implement and analyze Flow security policies - Network troubleshooting and optimization - Optimize physical and virtual network configurations |
| Advanced Platform Configuration and Troubleshooting | 25% | - API and CLI-based operations - Cluster management, expansion and maintenance - Security configuration and compliance - Integration with third-party systems - Prism Central and Prism Element configuration |
| Virtualization and VM Performance Optimization | 15% | - Performance metrics analysis and tuning - High availability and migration management - VM resource adjustment and optimization - AHV administration and workload management |
| Monitoring, Automation and Operational Efficiency | 5% | - Monitoring and alerting configuration - Operational process optimization - Automation workflows and tools |
| Business Continuity and Disaster Recovery | 15% | - Failover and failback operations - BCDR testing and validation - Replication and recovery configuration - Disaster recovery strategy implementation |
| Analyze and Optimize Storage Performance | 20% | - Optimize storage configuration and settings - Troubleshoot storage performance bottlenecks - Evaluate and resolve competing workload requirements - Understand storage internals and I/O patterns |
The NCM-MCI-6.10 Exam Questions is of the highest quality, and it enables participants to pass the NCM-MCI-6.10 exam on their first try. For successful preparation, it is essential to have good NCM-MCI-6.10 exam dumps and to prepare questions that may come up in the exam. DumpStillValid helps candidates overcome all the difficulties they may encounter in their exam preparation. To ensure the candidates' satisfaction, DumpStillValid has a support team that is available 24/7 to assist with a wide range of issues.
NEW QUESTION # 10
Task 13
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
NEW QUESTION # 11
TASK 1
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to
"SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named MonitorSQL02 and send the report as a PDF on a daily basis to perf_group@ACME.org. Reports should not be retained. If any new objects need to be created, use monitovm2 in the name.
Finally, correct the issue within "SQL02".
Notes:
* Do not power on the VMs.
* While you will be creating a session, you will need to examine the VM configurations to determine the issue.
* Do not delete the VM to resolve the issue, any other destructive change is acceptable.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to all three tasks, performed within the Nutanix Prism interface.
Task 1: Create Monitoring Session & Save Metrics
* From the Prism Central dashboard, navigate to Operations > Analysis.
* Click the + New Session button.
* Name the session Monitor SQL02.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart.
* Title: Storage IOPS
* Metric: Storage Controller IOPS
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Latency
* Metric: Storage Controller Latency
* Click Add.
* Click Add Charts > New Chart.
* Title: Storage Bandwidth
* Metric: Storage Controller Bandwidth
* Click Add.
* Click Save Session.
* With the "Monitor SQL02" session open, right-click anywhere on the page and click Select All.
* Right-click again and select Copy.
* Open Notepad, paste the content, and save the file to the desktop as Task 1.txt.
(The content pasted into Task 1.txt would be the session's chart configurations, showing metrics for SQL01 and SQL02.)
Task 2: Create and Schedule the Report
* While still in the "Monitor SQL02" analysis session, click the Save as Report button (it looks like a bookmark icon).
* Name the report MonitorSQL02 and click Save.
* Navigate to Operations > Reports.
* Find the MonitorSQL02 report in the list. Select its checkbox.
* Click the Actions dropdown and select Schedule.
* Configure the schedule with the following settings:
* Schedule Name: monitovm2_daily_report
* Recurrence: Daily
* Start Time: (Set to a time, e.g., 8:00 AM)
* Repeat every: 1 day(s)
* Retention Policy: Uncheck the "Retain a copy of the report" box. (This ensures reports are not retained).
* Email Report: Check this box.
* Format: PDF
* Recipients: perf_group@ACME.org
* Click Save.
Task 3: Identify and Correct the Performance Issue
This task is performed without powering on the VMs, indicating a configuration error.
Investigation
* Navigate to VMs > Table view.
* Click on the SQL01 (the good VM) and select the Configuration tab.
* Expand the Disks section. Observe that the primary disk is attached to a SCSI bus (e.g., scsi.0). This is the high-performance standard.
* Return to the VM list and click on SQL02 (the problem VM).
* Expand the Disks section.
Root Cause
You discover that the primary disk for SQL02 is attached to an IDE bus. The IDE bus has significant performance limitations and is not suitable for a database server, causing the poor storage performance.
Correction
* With the SQL02 VM selected, click the Update button.
* In the "Update VM" dialog, scroll down to the Disks section.
* Find the disk attached to the IDE bus. Click the Edit (pencil) icon for that disk.
* Change the Bus Type dropdown from IDE to SCSI.
* The Device Index will automatically populate (e.g., scsi.0).
* Click Save in the "Update Disk" dialog.
* (Note: A "VirtIO SCSI Controller" will be automatically added to the VM configuration if one was not already present.)
* Click Save in the "Update VM" dialog.
The VM SQL02 is now configured to use the high-performance VirtIO-SCSI controller, which will resolve the storage performance discrepancy once the VM is powered on.
NEW QUESTION # 12
Task 12
The application team is reporting performance degradation for a business-critical application that runs processes all day on Saturdays.
The team is requesting monitoring or processor, memory and storage utilization for the three VMs that make up the database cluster for the application: ORA01, ORA02 and ORA03.
The report should contain tables for the following:
At the cluster level, only for the current cluster:
The maximum percentage of CPU used
At the VM level, including any future VM with the prefix ORA:
The maximum time taken to process I/O Read requests
The Maximum percentage of time a VM waits to use physical CPU, out of the local CPU time allotted to the VM.
The report should run on Sundays at 12:00 AM for the previous 24 hours. The report should be emailed to appdev@cyberdyne.net when competed.
Create a report named Weekends that meets these requirements
Note: You must name the report Weekends to receive any credit. Any other objects needed can be named as you see fit. SMTP is not configured.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To create a report named Weekends that meets the requirements, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter Weekends as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select Cluster. Click Next.
Under the Custom Columns option, add the following variable: CPU Usage (%). Click Next.
Under the Aggregation option for CPU Usage (%), select Max. Click Next.
Under the Filter option, select Current Cluster from the drop-down menu. Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Custom Views section, select Data Table again. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, I/O Read Latency (ms), VM Ready Time (%). Click Next.
Under the Aggregation option for I/O Read Latency (ms) and VM Ready Time (%), select Max. Click Next.
Under the Filter option, enter ORA* in the Name field. This will include any future VM with the prefix ORA.
Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Report Settings option, select Weekly from the Schedule drop-down menu and choose Sunday as the day of week. Enter 12:00 AM as the time of day. Enter appdev@cyberdyne.net as the Email Recipient.
Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.
NEW QUESTION # 13
Task 5
An administrator has noticed that after a host failure, the SQL03 VM was not powered back on from another host within the cluster. The Other SQL VMs (SQL01, SQL02) have recovered properly in the past.
Resolve the issue and configure the environment to ensure any single host failure affects a minimal number os SQL VMs.
Note: Do not power on any VMs
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
One possible reason why the SQL03 VM was not powered back on after a host failure is that the cluster was configured with the default (best effort) VM high availability mode, which does not guarantee the availability of VMs in case of insufficient resources on the remaining hosts. To resolve this issue, I suggest changing the VM high availability mode to guarantee (reserved segments), which reserves some memory on each host for failover of VMs from a failed host. This way, the SQL03 VM will have a higher chance of being restarted on another host in case of a host failure.
To change the VM high availability mode to guarantee (reserved segments), you can follow these steps:
Log in to Prism Central and select the cluster where the SQL VMs are running.
Click on the gear icon on the top right corner and select Cluster Settings.
Under Cluster Services, click on Virtual Machine High Availability.
Select Guarantee (Reserved Segments) from the drop-down menu and click Save.
To configure the environment to ensure any single host failure affects a minimal number of SQL VMs, I suggest using anti-affinity rules, which prevent VMs that belong to the same group from running on the same host. This way, if one host fails, only one SQL VM will be affected and the other SQL VMs will continue running on different hosts.
To create an anti-affinity rule for the SQL VMs, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Group.
Enter a name for the group, such as SQL Group, and click Next.
Select the SQL VMs (SQL01, SQL02, SQL03) from the list and click Next.
Select Anti-Affinity from the drop-down menu and click Next.
Review the group details and click Finish.
I hope this helps. How else can I help?
https://portal.nutanix.com/page/documents/details?targetId=AHV-Admin-Guide-v6_5:ahv-affinity-policies-c.html
A screenshot of a computer Description automatically generated with medium confidence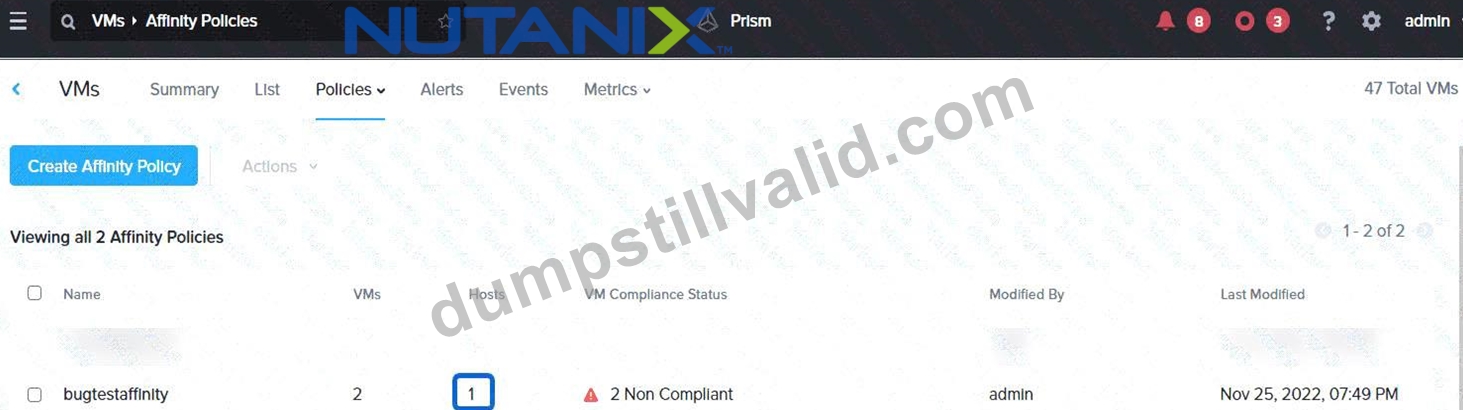
NEW QUESTION # 14
An administrator regularly sees a WARN for backup_schedule_check and also receives alerts for Pulse not being enabled on Cluster 1.
Detailed information for backup_schedule_check:
Node xx.xx.xx.xx:
WARN: Backup schedule(s) exist for protection domain NoVMs; however, there are no entities in the protection domain.
Refer
to KB 1910 (http://portal.nutanix.com/kb/1910) for details on backup_schedule_check or Recheck with: ncc health_checks data_protection_checks protection_domain_checks backup_schedule_check.
This shows up in NCC, however, it is something set up by the company and they do not want the NCC check to be run.
Configure Cluster 1 to no longer have messages in NCC about the backup_schedule_check.
Turn off the alert for Pulse not being enabled, and resolve the alert. They would like messages about Pulse to be recorded, but do not want an alert.
Note: You may need to run the "Pulse is not enabled" check in order to have one to resolve.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure Cluster 1 from its Prism Element interface.
1. Disable the backup_schedule_check NCC Check
This will prevent the WARN message for the NoVMs protection domain.
* Log in to the Cluster 1 Prism Element (PE) interface.
* Navigate to the Health dashboard (click the "heart" icon in the top-left).
* In the left-hand menu, select NCC.
* In the search bar for the checks, type backup_schedule_check to find the specific check.
* Select the checkbox next to the backup_schedule_check in the list.
* Click the Disable button that appears above the table. This will stop this check from running during NCC health reports.
2. Configure and Resolve Pulse Alerts
This process involves two parts: disabling the alerting policy, and then enabling Pulse itself to resolve the underlying condition.
A. Disable the Alert Policy
This stops the system from generating a new alert if Pulse is ever disabled, satisfying the "do not want an alert" requirement.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type Pulse to find the policy.
* Select the checkbox for the alert policy named Pulse is not enabled (or pulse_disabled_alert).
* Click the Update button.
* Uncheck the Enable box for the policy.
* Click Save.
B. Enable Pulse (to Resolve the Condition)
This enables the Pulse service to record messages (as requested) and fixes the root cause of the alert, allowing it to be resolved.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Pulse.
* Click the Enable Pulse button (or "Update" if it's already partially configured).
* Check the box for Enable Pulse.
* (Note: Any "Enable alerts for Pulse" boxes would remain unchecked or be ignored, as the main Alert Policy itself is now disabled.)
* Click Save.
C. Resolve the Active Alert
* Navigate to the Alerts dashboard (click the "bell" icon in the top-left).
* Find the active alert: Pulse is not enabled.
* (Note: If the alert is not present, you would first go to the Health dashboard, run the check_pulse NCC check to generate it, and then return to the Alerts dashboard.)
* Select the checkbox next to the "Pulse is not enabled" alert.
* Click the Resolve button that appears at the top of the list. Since the underlying condition (Pulse being disabled) is now fixed, the alert will be successfully resolved.
NEW QUESTION # 15
......
These Nutanix NCM-MCI-6.10 questions will give you an accurate foresight of the Nutanix NCM-MCI-6.10 examination format. This Nutanix NCM-MCI-6.10 is easily downloadable and even printable, this way you can also pursue paper study if that is your preferred method. The portability of this material makes it handier since you can access it on any smart device such as smart phones, laptops, tablets, etc. These Nutanix NCM-MCI-6.10 features make this prep method the most comfortable one.
NCM-MCI-6.10 Cost Effective Dumps: https://www.dumpstillvalid.com/NCM-MCI-6.10-prep4sure-review.html
What's more, part of that DumpStillValid NCM-MCI-6.10 dumps now are free: https://drive.google.com/open?id=1havzBBCBtyjTVI1XrK2X8FZbZPk4e4Ej