BTW, DOWNLOAD part of CramPDF Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1CQYKPRkvGDtQpP2i0XKecdkC9DAtJFzW
Using our products does not take you too much time but you can get a very high rate of return. Our Databricks-Certified-Professional-Data-Engineer quiz guide is of high quality, which mainly reflected in the passing rate. We can promise higher qualification rates for our Databricks-Certified-Professional-Data-Engineer exam question than materials of other institutions. Because our products are compiled by experts from various industries and they are based on the true problems of the past years and the development trend of the industry. What's more, according to the development of the time, we will send the updated materials of Databricks-Certified-Professional-Data-Engineer Test Prep to the customers soon if we update the products. Under the guidance of our study materials, you can gain unexpected knowledge. Finally, you will pass the exam and get a Databricks certification.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Delta Lake | 20-25% | - Delta Lake operations
|
>> Original Databricks-Certified-Professional-Data-Engineer Questions <<
God is fair, and everyone is not perfect. As we all know, the competition in the IT industry is fierce. So everyone wants to get the IT certification to enhance their value. I think so, too. But it is too difficult for me. Fortunately, I found CramPDF's Databricks Databricks-Certified-Professional-Data-Engineer exam training materials on the Internet. With it, I would not need to worry about my exam. CramPDF's Databricks Databricks-Certified-Professional-Data-Engineer Exam Training materials are really good. It is wide coverage, and targeted. If you are also one of the members in the IT industry, quickly add the CramPDF's Databricks Databricks-Certified-Professional-Data-Engineer exam training materials to your shoppingcart please. Do not hesitate, do not hovering. CramPDF's Databricks Databricks-Certified-Professional-Data-Engineer exam training materials are the best companion with your success.
NEW QUESTION # 47
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the " Owner " for each job. They attempt to transfer " Owner " privileges to the " DevOps " group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
Answer: D
Explanation:
The reason why the junior data engineer cannot transfer "Owner" privileges to the "DevOps" group is that Databricks jobs must have exactly one owner, and the owner must be an individual user, not a group. A job cannot have more than one owner, and a job cannot have a group as an owner. The owner of a job is the user who created the job, or the user who was assigned the ownership by another user. The owner of a job has the highest level of permission on the job, and can grant or revoke permissions to other users or groups. However, the owner cannot transfer the ownership to a group, only to another user. Therefore, the junior data engineer's attempt to transfer "Owner" privileges to the "DevOps" group is not possible. References:
* Jobs access control : https://docs.databricks.com/security/access-control/table-acls/index.html
* Job permissions : https://docs.databricks.com/security/access-control/table-acls/privileges.html#job- permissions
NEW QUESTION # 48
A data engineer deploys a multi-task Databricks job that orchestrates three notebooks. One task intermittently fails with Exit Code 1 but succeeds on retry. The engineer needs to collect detailed logs for the failing attempts, including stdout/stderr and cluster lifecycle context, and share them with the platform team.
What steps the data engineer needs to follow using built-in tools?
Answer: C
Explanation:
The recommended way to troubleshoot and collect detailed job logs is through the Job Run Details page in Databricks. From there, engineers can export run logs or configure automatic log delivery to a storage destination. The driver and event logs available under compute details provide stdout, stderr, and cluster lifecycle context required for root-cause analysis.
Reference Source: Databricks Jobs Monitoring and Logging Documentation - "Access driver logs and configure log delivery."
NEW QUESTION # 49
At the end of the inventory process, a file gets uploaded to the cloud object storage, you are asked to build a process to ingest data which of the following method can be used to ingest the data in-crementally, schema of the file is expected to change overtime ingestion process should be able to handle these changes automatically.
Below is the auto loader to command to load the data, fill in the blanks for successful execution of below code.
1.spark.readStream
2..format("cloudfiles")
3..option("_______","csv)
4..option("_______", 'dbfs:/location/checkpoint/')
5..load(data_source)
6..writeStream
7..option("_______",' dbfs:/location/checkpoint/')
8..option("_______", "true")
9..table(table_name))
Answer: B
Explanation:
Explanation
The answer is cloudfiles.format, cloudfiles.schemalocation, checkpointlocation, mergeSchema.
Here is the end to end syntax of streaming ELT, below link contains complete options Auto Loader options | Databricks on AWS
1.spark.readStream
2..format("cloudfiles") # Returns a stream data source, reads data as it arrives based on the trigger.
3..option("cloudfiles.format","csv") # Format of the incoming files
4..option("cloudfiles.schemalocation", "dbfs:/location/checkpoint/") The location to store the inferred schema and subsequent changes
5..load(data_source)
6..writeStream
7..option("checkpointlocation","dbfs:/location/checkpoint/") # The location of the stream's checkpoint
8..option("mergeSchema", "true") # Infer the schema across multiple files and to merge the schema of each file. Enabled by default for Auto Loader when inferring the schema.
9..table(table_name)) # target table
NEW QUESTION # 50
While reviewing a query's execution in the Databricks Query Profiler, a data engineer observes that the Top Operators panel shows a Sort operator with high Time Spent and Memory Peak metrics. The Spark UI also reports frequent data spilling.
How should the data engineer address this issue?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
When Spark performs wide transformations such as sortBy or orderBy, large data volumes can exceed memory limits, causing disk spilling. The official Databricks performance tuning guide recommends increasing the shuffle partition count to distribute the data more evenly across executors. By default, Spark uses a fixed number of shuffle partitions (e.g., 200), which can lead to memory imbalance and spill if some partitions are too large. Increasing this number (via spark.sql.shuffle.partitions) results in smaller partitions, reduced in-memory pressure, and improved sort performance. Other options like broadcast joins or single partition sorts do not apply to single-table sorts, and converting to filters changes query logic. Thus, option D is the correct remedy.
NEW QUESTION # 51
The data engineering team noticed that one of the job fails randomly as a result of using spot in-stances, what feature in Jobs/Tasks can be used to address this issue so the job is more stable when using spot instances?
Answer: A
Explanation:
Explanation
The answer is, Add a retry policy to the task
Tasks in Jobs support Retry Policy, which can be used to retry a failed tasks, especially when using spot instance it is common to have failed executors or driver.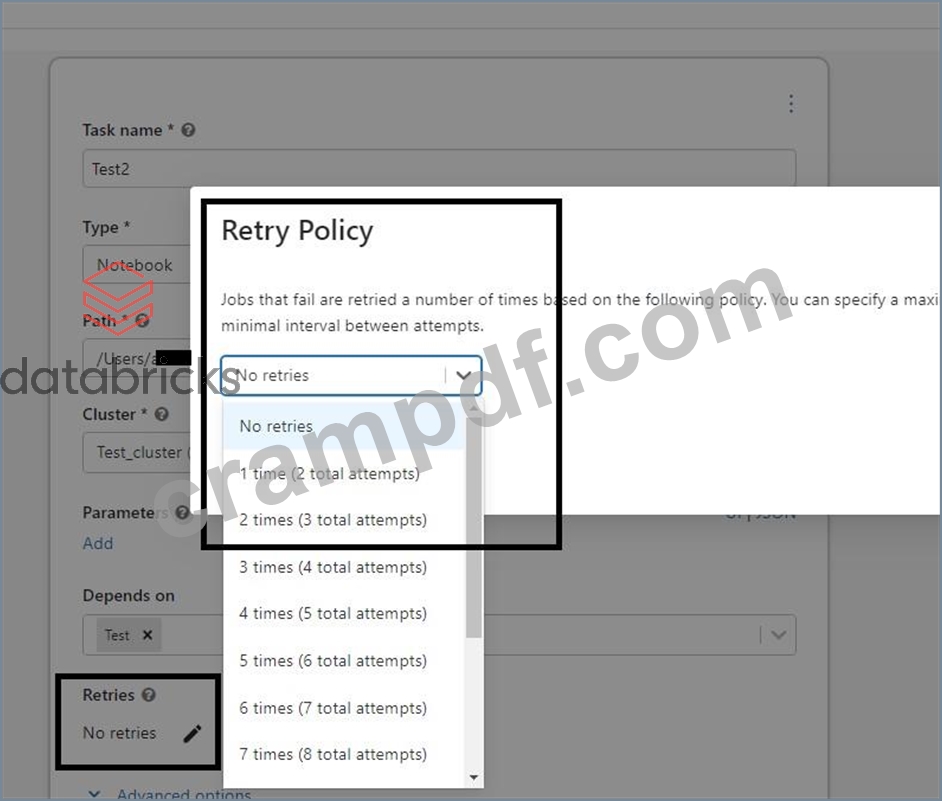
NEW QUESTION # 52
......
Databricks-Certified-Professional-Data-Engineer practice software creates an atmosphere just like a real Databricks exam thus developing your confidence and leaving no space for any surprises that make you anxious on the day of the exam. Moreover, the software is developed by CramPDF in a way that is simple to use and helps you perform better at the Databricks Certified Professional Data Engineer Exam exam. But in case you face any problem in accessing the Databricks Databricks-Certified-Professional-Data-Engineer exam questions while preparing for the Databricks Certified Professional Data Engineer Exam exam, there is a product support team at CramPDF to help you with it. You get guaranteed money back – if despite proper preparation using the Databricks Databricks-Certified-Professional-Data-Engineer by CramPDF you are unable to pass the exam. Grab the opportunity to learn, pass the Databricks Certified Professional Data Engineer Exam exam, and grow your career. By taking Databricks certification you can even improve your potential earning power and build a better professional network.
Databricks-Certified-Professional-Data-Engineer Study Materials Review: https://www.crampdf.com/Databricks-Certified-Professional-Data-Engineer-exam-prep-dumps.html
P.S. Free & New Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by CramPDF: https://drive.google.com/open?id=1CQYKPRkvGDtQpP2i0XKecdkC9DAtJFzW