Many candidates who take the qualifying exams are not aware of our products and are not guided by our systematic guidance, and our users are much superior to them. In similar educational products, the Databricks-Certified-Professional-Data-Engineer quiz guide is absolutely the most practical. Also, from an economic point of view, our Databricks Certified Professional Data Engineer Exam exam dumps is priced reasonable, so the Databricks-Certified-Professional-Data-Engineer test material is very responsive to users, user satisfaction is also leading the same products. So economical and practical learning platform, I believe that will be able to meet the needs of users. Users can deeply depend on our Databricks Certified Professional Data Engineer Exam exam dumps when you want to get a qualification. There may be many problems and difficulties you will face, but believe in our Databricks Certified Professional Data Engineer Exam exam dumps if you want to be the next beneficiary, our Databricks-Certified-Professional-Data-Engineer Quiz guide is not only superior in price than any other makers in the educational field , but also are distinctly superior in the quality of our products.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
| Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Handling missing or inconsistent data - Data validation and quality checks |
| Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Data transformation and aggregation - Batch and incremental processing logic |
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs |
| Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Monitoring and Alerting | 10% | - Pipeline observability and logging - Performance and health monitoring - Setting up alerts and notifications |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) |
>> Databricks-Certified-Professional-Data-Engineer Detailed Study Dumps <<
Students often feel helpless when purchasing test materials, because most of the test materials cannot be read in advance, students often buy some products that sell well but are actually not suitable for them. But if you choose Databricks-Certified-Professional-Data-Engineer practice test, you will certainly not encounter similar problems. All the materials in Databricks-Certified-Professional-Data-Engineer Exam Torrent can be learned online or offline. You can use your mobile phone, computer or print it out for review. With Databricks-Certified-Professional-Data-Engineer practice test, if you are an office worker, you can study on commute to work, while waiting for customers, and for short breaks after work.
NEW QUESTION # 164
When defining external tables using formats CSV, JSON, TEXT, BINARY any query on the exter-nal tables caches the data and location for performance reasons, so within a given spark session any new files that may have arrived will not be available after the initial query. How can we address this limitation?
Answer: A
Explanation:
Explanation
The answer is REFRESH TABLE table_name
REFRESH TABLE table_name will force Spark to refresh the availability of external files and any changes.
When spark queries an external table it caches the files associated with it, so that way if the table is queried again it can use the cached files so it does not have to retrieve them again from cloud object storage, but the drawback here is that if new files are available Spark does not know until the Refresh command is ran.
NEW QUESTION # 165
What statement is true regarding the retention of job run history?
Answer: A
Explanation:
Explanation
This is the correct answer because it is true regarding the retention of job run history. Job run history is the information about each run of a job, such as the start time, end time, status, logs, and output. Job run history is retained for 30 days by default, during which time you can view it in the Jobs UI or access it through the Jobs API. You can also deliver job run logs to DBFS or S3 using the Log Delivery feature, which allows you to specify a destination path and a delivery frequency for each job. By delivering job run logs to DBFS or S3, you can preserve them beyond the 30-day retention period and use them for further analysis or troubleshooting. Verified References: [Databricks Certified Data Engineer Professional], under "Databricks Jobs" section;Databricks Documentation, under "Job run history" section; Databricks Documentation, under
"Log Delivery" section.
NEW QUESTION # 166
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.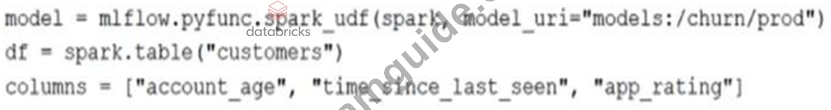
Which code block will output DataFrame with the schema ' ' customer_id LONG, predictions DOUBLE ' ' ?
Answer: D
Explanation:
Given the information that the model is registered with MLflow and assuming predict is the method used to apply the model to a set of columns, we use the model.predict() function to apply the model to the DataFrame df using the specified columns . The model.predict() function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictions column. When working with PySpark, this predictions column needs to be selected alongside the customer_id to create a new DataFrame with the schema customer_id LONG, predictions DOUBLE .
References:
MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.
html#python-function-python
PySpark MLlib documentation on model prediction: https://spark.apache.org/docs/latest/ml-pipeline.
html#pipeline
NEW QUESTION # 167
A facilities-monitoring team is building a near-real-time PowerBI dashboard off the Delta table device_readings:
Columns:
device_id (STRING, unique sensor ID)
event_ts (TIMESTAMP, ingestion timestamp UTC)
temperature_c (DOUBLE, temperature in °C)
Requirement:
For each sensor, generate one row per non-overlapping 5-minute interval, offset by 2 minutes (e.g., 00:02-00:07, 00:07-00:12, ...).
Each row must include interval start, interval end, and average temperature in that slice.
Downstream BI tools (e.g., Power BI) must use the interval timestamps to plot time-series bars.
Options:
Answer: D
Explanation:
The correct way to satisfy non-overlapping windows with an offset in Databricks SQL is to use the window function with three parameters: window duration, slide duration, and start offset.
In option A, the function call:
window(event_ts, '5 minutes', '2 minutes', '5 minutes')
creates 5-minute windows that slide every 5 minutes, with a 2-minute offset, which exactly matches the requirement (intervals like 00:02-00:07, 00:07-00:12, ...).
Option B is incorrect because it uses a windowed aggregation with RANGE, which produces overlapping sliding averages, not discrete non-overlapping buckets.
Option C manually constructs bucket boundaries with date_trunc and offsets, but this is brittle and less efficient than the built-in window function.
Option D incorrectly passes four parameters to window but with the wrong ordering (5 minutes, 5 minutes, 2 minutes). This creates a sliding window every 5 minutes with overlap, rather than true non-overlapping shifted windows.
Reference (Databricks SQL Windowing Functions):
Databricks documentation specifies that:
window(time_col, windowDuration, slideDuration, startTime)
produces tumbling or sliding windows. When slideDuration = windowDuration, it produces non-overlapping tumbling windows. The startTime argument allows for offset windows, which is why '2 minutes' ensures alignment at 00:02, 00:07, etc.
Thus, A is the only correct solution as it directly implements non-overlapping, offset-based tumbling windows.
NEW QUESTION # 168
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: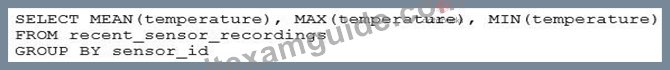
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120 . Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Answer: B
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified References: [Databricks Certified Data Engineer Professional], under "SQL Analytics" section; Databricks Documentation, under "Alerts" section.
NEW QUESTION # 169
......
Perhaps now you are one of the candidates of the Databricks Databricks-Certified-Professional-Data-Engineer exam, perhaps now you are worried about not passing the exam smoothly. Now we have good news for you: our Databricks-Certified-Professional-Data-Engineer study materials will solve all your worries and help you successfully pass it. With the high pass rate as 98% to 100%, you will find that we have the best Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer learning braindumps which contain the most accurate real exam questions.
Databricks-Certified-Professional-Data-Engineer Test Study Guide: https://www.itexamguide.com/Databricks-Certified-Professional-Data-Engineer_braindumps.html