さらに、GoShiken NCA-GENMダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=10h04yQRG0qE26Lu47nfNA3Chwfk1_LIF
当社GoShikenの製品は、主要な質問と回答で精巧に構成されています。 NCA-GENMガイドの質問を完了するために、過去の資料からキーを選択しています。 練習するのに20時間から30時間しかかかりません。 効果的な練習の後、NVIDIAのNCA-GENMテスト問題から試験ポイントをマスターできます。 そうすれば、合格するのに十分な自信があります。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Core ML & AI Knowledge | 20% | - Key algorithms and techniques - Basic concepts and terminology |
| Topic 2: Data Analysis & Visualization | 10% | - Data preprocessing and feature engineering - Visualization techniques for multimodal data |
| Topic 3: Trustworthy AI | 5% | - Ensuring fairness and transparency - Ethical considerations in AI development |
| Topic 4: Software Development & Engineering | 15% | - Integration and deployment of multimodal AI systems - Python libraries for multimodal AI |
| Topic 5: Performance Optimization | 10% | - Techniques for optimizing AI performance - Monitoring and improving system efficiency |
| Topic 6: Experimentation | 25% | - Model evaluation and comparison - Hypothesis testing - Experimental design - A/B testing |
| Topic 7: Multimodal Data | 15% | - Handling and integrating text, image, and audio data - Applications and use cases |
優れたNCA-GENM試験問題を使用すると、NCA-GENM認定資格を取得して自分自身を向上させ、より良い未来とより良い未来を実現することができます。 NCA-GENMトレーニングガイドを使用すると、職業で認められます。 NCA-GENM試験のブレーンダンプは、より大きな会社に注目させる能力を証明できます。 その後、より良い仕事を取得し、適切な職場に行くための選択肢があります。 NCA-GENM試験問題を試してみてはいかがですか。NCA-GENM試験問題が最高の準備資料であることに驚かれることでしょう。
質問 # 49
You are using NeMo to fine-tune a pre-trained language model for a specific text generation task. You want to implement a custom data augmentation technique to improve the model's robustness. Which of the following approaches is most appropriate for integrating your custom augmentation within the NeMo framework?
正解:D
解説:
Creating a custom 'Dataset' class that inherits from 'nemo.core.Dataset' is the recommended and most maintainable way to integrate custom data augmentation in NeMo. This allows you to leverage NeMo's data loading and processing pipelines while seamlessly incorporating your specific augmentation logic within the '_getitem method. Modifying core NeMo files (A) is strongly discouraged. Using a separate pipeline (C) disconnects augmentation from the NeMo workflow. Monkey-patching (D) is brittle. Augmenting within the training loop (E) can be inefficient.
質問 # 50
Consider the following PyTorch code snippet intended for training a variational autoencoder (VAE):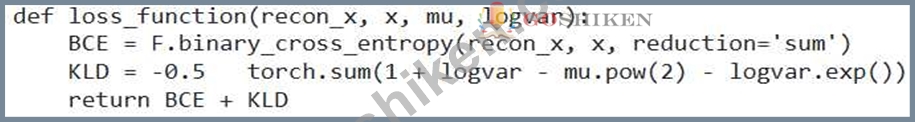
What potential issue(s) exist(s) in this code, and how would you address them?
正解:A
解説:
All the mentioned issues exist. Firstly, BCE requires inputs between 0 and 1 . Secondly, KLD loss needs to be scaled according to batch size for proper gradients during training. Thirdly, simply summing the BCE isn't ideal, average is better. Finally, the KLD calculation is indeed reverse of what it should be.
質問 # 51
Which of the following statements accurately describes the role of attention mechanisms in Transformer-based multimodal models?
(Select all that apply)
正解:A、B
解説:
Attention mechanisms enable the model to selectively focus on relevant parts of the input and learn relationships between modalities. They don't compress the input into a fixed-length vector, nor are they primarily for reducing computational cost or preventing vanishing gradients (although they can indirectly help with the latter).
質問 # 52
You are training a multimodal model that combines audio and video dat
a. You observe that the model performs well on the training data but generalizes poorly to unseen data. Which of the following regularization techniques is MOST likely to improve the generalization performance in this scenario?
正解:D
解説:
Data augmentation is the most effective regularization technique in this scenario because it increases the diversity of the training data, making the model more robust to variations in unseen data L1 and L2 regularization can help prevent over fitting, but data augmentation directly addresses the issue of limited training data. Dropout also helps, but data augmentation is generally more impactful for multimodal data where variations are significant. Early stopping can also help, but it is not as effective as data augmentation.
質問 # 53
You are tasked with building a Generative A1 model to generate realistic images of outdoor scenes. The training dataset contains a large number of images with varying lighting conditions, weather conditions, and object compositions. Which data augmentation techniques would be MOST effective in improving the model's robustness and generalization ability?
正解:A
解説:
Color jittering, adding Gaussian noise, and random perspective transformations simulate variations in lighting, noise, and camera angles, making the model more robust to different real-world scenarios. Random cropping and resizing are also helpful, but less impactful than changes in the color space and noise. Horizontal flipping can be useful but is limited. A fixed rotation or Vertical flipping is not a general augmentation and might harm the model's performance.
質問 # 54
......
NCA-GENM試験の質問は、GoShikenお客様のニーズを最大限に満たすことができます。また、NCA-GENM学習教材は、お客様の観点から最大限に設計されています。 したがって、運用の複雑さを心配する必要はありません。 システムの学習インターフェイスに入り、WindowsソフトウェアでNCA-GENM学習教材の練習を開始すると、インターフェイスに小さなボタンが表示されます。 これらのボタンには回答が表示され、学習プロセスを妨げないように、NCA-GENM試験クイズのNVIDIA Generative AI Multimodal学習中に回答を非表示にすることができます。 すべての面が完璧です。
NCA-GENM日本語版と英語版: https://www.goshiken.com/NVIDIA/NCA-GENM-mondaishu.html
無料でクラウドストレージから最新のGoShiken NCA-GENM PDFダンプをダウンロードする:https://drive.google.com/open?id=10h04yQRG0qE26Lu47nfNA3Chwfk1_LIF