無料でクラウドストレージから最新のJpexam DP-600 PDFダンプをダウンロードする:https://drive.google.com/open?id=1xRWCyPmQ3wN2-dZSoq2T-GHKsEgLdee4
我々は弊社のDP-600問題集を利用するあなたは一発で試験に合格できると信じています。我々はIT業界の権威で専門家たちは数年以来の努力を通して、DP-600問題集の開発に就職しています。我々のDP-600問題集を利用してから、あなたは短い時間でリラクスで試験に合格することができるだけでなく、試験に必要な技能を身につけることもできます。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Real Exam Qty: | 40-60 |
| Passing Score: | 700/1000 |
| Exam Price: | $165 USD |
| Exam Format: | Drag-and-drop, Multiple-choice, Case studies |
| Available Languages: | Japanese, Korean, English, Chinese (Simplified) |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
| Certificate Validity Period: | 1 year |
| Exam Duration: | 120 minutes |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or in-person testing center |
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
今日の社会では、能力を高めるために証明書を取得することを優先する人がますます増えています。 Microsoftまったく新しい観点から、JpexamのDP-600学習資料は、DP-600認定の取得を目指すほとんどのオフィスワーカーに役立つように設計されています。 当社のDP-600テストガイドは、現代の人材開発に歩調を合わせ、すべての学習者を社会のニーズに適合させます。 Implementing Analytics Solutions Using Microsoft Fabricの最新の質問が、関連する知識の蓄積と能力強化のための最初の選択肢になることは間違いありません。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 37
You have a Fabric tenant that contains lakehouse named Lakehousel. Lakehousel contains a Delta table with eight columns. You receive new data that contains the same eight columns and two additional columns.
You create a Spark DataFrame and assign the DataFrame to a variable named df. The DataFrame contains the new data. You need to add the new data to the Delta table to meet the following requirements:
* Keep all the existing rows.
* Ensure that all the new data is added to the table.
How should you complete the code? To answer, select the appropriate options in the answer area.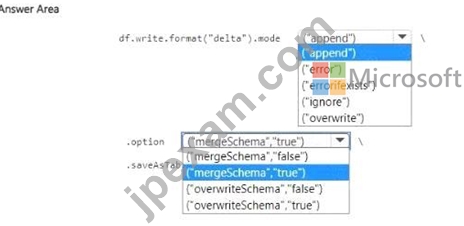
正解:
解説: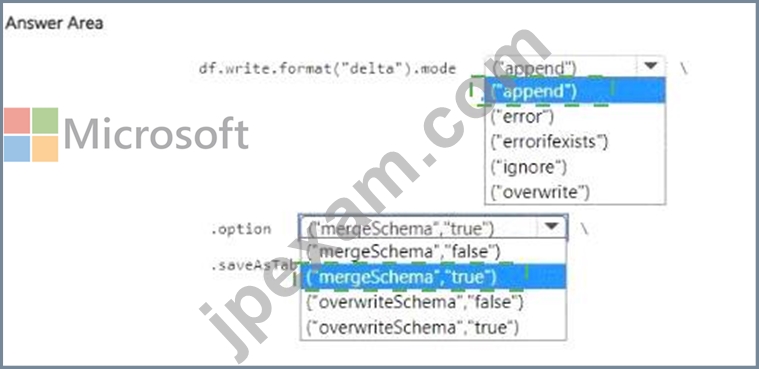
Explanation: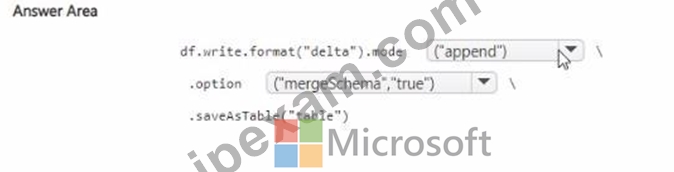
o add new data to the Delta table while meeting the specified requirements:
* You should use the append mode to ensure that all new data is added to the table without affecting the existing rows.
* You should set the mergeSchema option to true to allow the schema of the Delta table to be updated with the new columns found in the DataFrame.
The completed code would look like this:
df.write.format("delta").mode("append")
option("mergeSchema", "true")
saveAsTable("Lakehouse1.TableName")
質問 # 38
Case Study 1 - Contoso
Overview
Contoso, Ltd. is a US-based health supplements company. Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Existing Environment
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroup1 and ResearchReviewersGroup2.
Data Environment
Contoso has the following data environment:
- The Sales division uses a Microsoft Power BI Premium capacity.
- The semantic model of the Online Sales department includes a fact table named Orders that uses Import made. In the system of origin, the OrderID value represents the sequence in which orders are created.
- The Research department uses an on-premises, third-party data warehousing product.
- Fabric is enabled for contoso.com.
- An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Productline1. - The data is in the delta format.
- A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Requirements
Planned Changes
Contoso plans to make the following changes:
- Enable support for Fabric in the Power BI Premium capacity used by the Sales division.
- Make all the data for the Sales division and the Research division available in Fabric.
- For the Research division, create two Fabric workspaces named Productline1ws and Productine2ws.
- In Productline1ws, create a lakehouse named Lakehouse1.
- In Lakehouse1, create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
- All the workspaces for the Sales division and the Research division must support all Fabric experiences.
- The Research division workspaces must use a dedicated, on-demand capacity that has per- minute billing.
- The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
- For the Research division workspaces, the members of ResearchReviewersGroup1 must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
- For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
- All the semantic models and reports for the Research division must use version control that supports branching.
Data Preparation Requirements
Contoso identifies the following data preparation requirements:
- The Research division data for Productline1 must be retrieved from Lakehouse1 by using Fabric notebooks.
- All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models:
- The number of rows added to the Orders table during refreshes must be minimized.
- The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
- Follow the principle of least privilege when applicable.
- Minimize implementation and maintenance effort when possible.
Hotspot Question
You need to migrate the Research division data for Productline1. The solution must meet the data preparation requirements.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.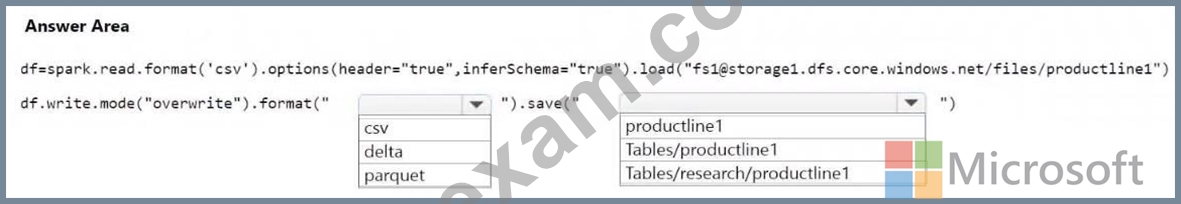
正解:
解説: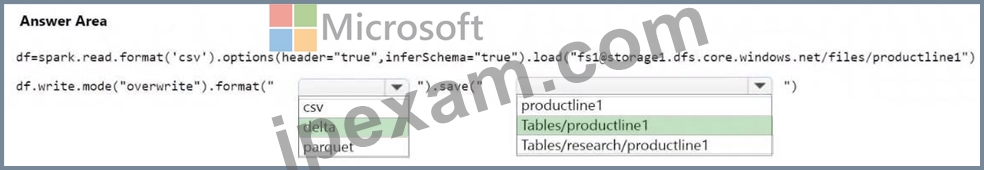
Explanation:
Requirements: Use managed tables.
If you use saveAsTable() you don't need to specify the path "Table/"
If you you save() you specify the full path
質問 # 39
You have a Fabric tenant that contains the workspaces shown in the following table.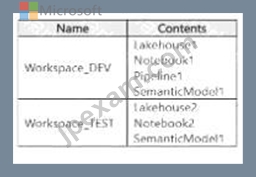
You have a deployment pipeline named Pipeline1 that deploys items from Workspace_DEV to Workspace_TEST. In Pipeline1, all items that have matching names are paired.
You deploy the contents of Workspace_DEV to Workspace_TEST by using Pipeline1.
What will the contents of Workspace_TEST be once the deployment is complete?
正解:A
解説:
Workspace_DEV contents:
Lakehouse1, Notebook1, Pipeline1, SemanticModel1
Workspace_TEST contents (before deployment):
Lakehouse2, Notebook2, SemanticModel1
After deployment:
SemanticModel1 # same name, so it will be paired and overwritten with the DEV version.
Lakehouse1 and Notebook1 # new items, so they will be added to TEST.
Lakehouse2 and Notebook2 # remain because they don't conflict in name.
Pipeline1 # new item, so it will also be added.
So the final content is:
Lakehouse1, Lakehouse2, Notebook1, Notebook2, Pipeline1, SemanticModel1 Reference:
Deployment pipelines pairing behavior
質問 # 40
You have two Microsoft Power Bl queries named Employee and Retired Roles.
You need to merge the Employee query with the Retired Roles query. The solution must ensure that rows in the Employee query that match the Retired Roles query are removed.
Which column and Join Kind should you use in Power Query Editor? To answer, select the appropriate options in the answer area.
NOTE: Each correct answer is worth one point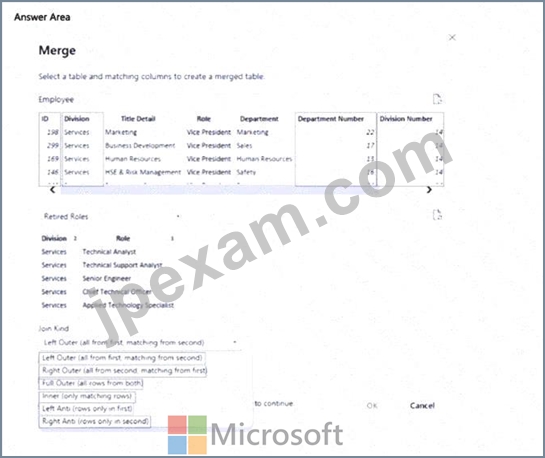
正解:
解説: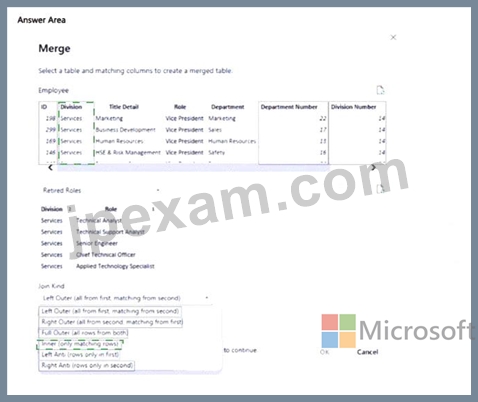
Explanation: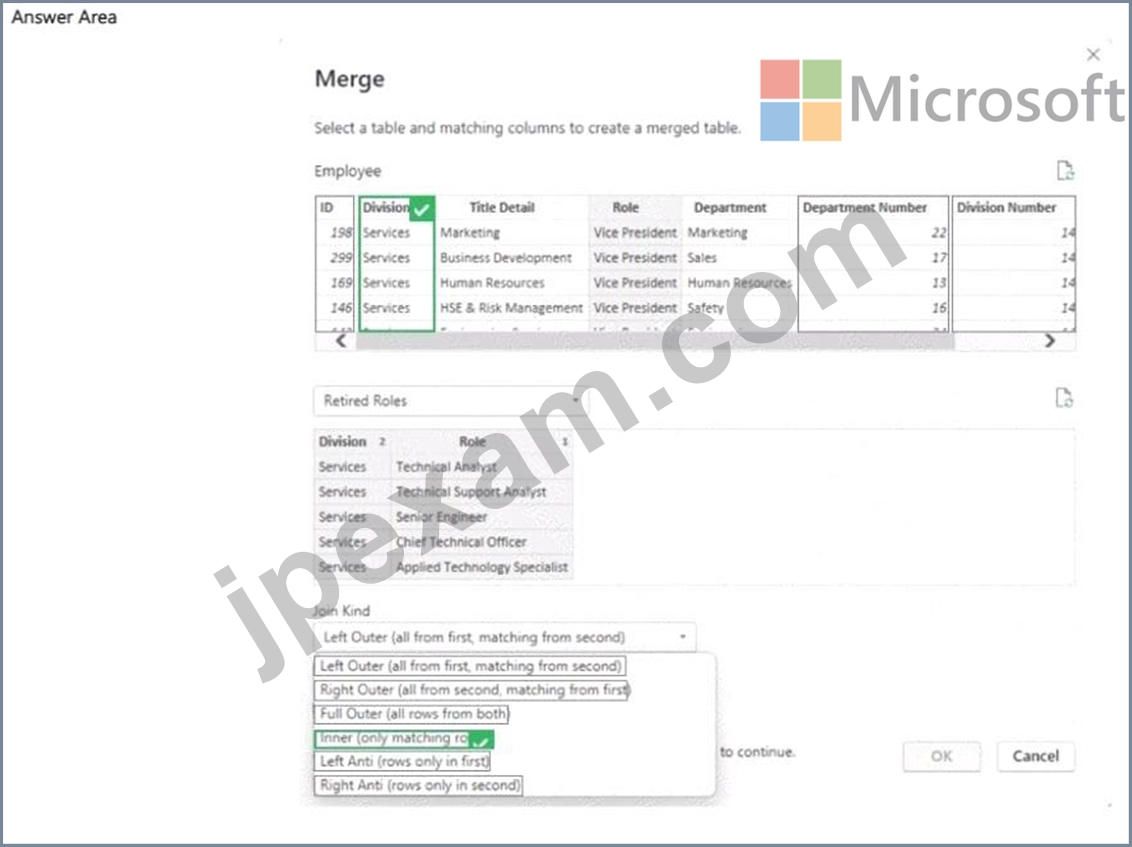
質問 # 41
You have an Amazon Web Services (AWS) subscription that contains an Amazon Simple Storage Service (Amazon S3) bucket named bucketl.
You have a Fabric tenant that contains a lakehouse named LH1.
In LH1, you plan to create a OneLake shortcut to bucketl.
You need to configure authentication for the connection.
Which two values should you provide? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:C、E
解説:
When creating a OneLake shortcut to Amazon S3, authentication uses the standard AWS access key ID + secret access key pair.
SAS token is for Azure Storage, not AWS.
Certificate thumbprint is not used for S3.
Access ID is incorrect naming; the correct term is access key ID.
Correct answers: B and D.
Reference: Create shortcuts to Amazon S3 in OneLake
質問 # 42
......
DP-600最新テスト: https://www.jpexam.com/DP-600_exam.html
2026年Jpexamの最新DP-600 PDFダンプおよびDP-600試験エンジンの無料共有:https://drive.google.com/open?id=1xRWCyPmQ3wN2-dZSoq2T-GHKsEgLdee4