If you are clueless about the oncoming exam, our AI-500 guide materials are trustworthy materials for your information. More than tens of thousands of exam candidate coincide to choose our AI-500practice materials and passed their exam with satisfied scores, a lot of them even got full marks. According to the data that are proved and tested by our loyal customers, the pass rate of our AI-500 Exam Questions is high as 98% to 100%.
| Section | Weight | Objectives |
|---|---|---|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
| Develop multi-agent solutions in Azure | 30-35% | - Build and integrate tool ecosystems
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
>> New Microsoft AI-500 Test Price <<
The aim of Microsoft AI-500 test torrent is to help you optimize your IT technology and get the AI-500 certification by offerring the high quality and best accuracy AI-500 study material. If you want to pass your AI-500 Actual Exam with high score, Dumpcollection AI-500 latest exam cram is the best choice for you. The high hit rate of AI-500 test practice will help you pass and give you surprise.
NEW QUESTION # 47
You have a Microsoft Foundry agent built by using LangGraph. The agent retrieves policy content from a vector store. The LangGraph orchestration runs in Azure Container Apps, and the operations team uses Azure Monitor to inspect agent runs.
You discover that the vector store is sometimes unreachable during Azure regional maintenance windows You need to configure the tool ecosystem to ensure that the agent can answer policy questions during outages The solution must meet the following requirements:
* Use the project vector store without adding a local retrieval node for the primary path.
* Run the cached-policy lookup in the same compute environment as the LangGraph code.
* Emit agent, model, and tool spans that can be inspected in Azure Monitor How should you configure the tool ecosystem? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.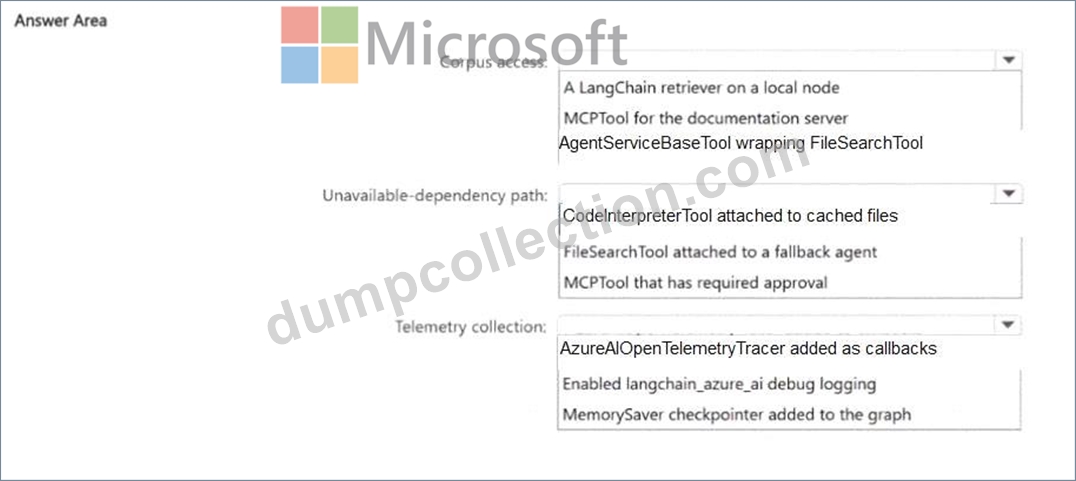
Answer:
Explanation: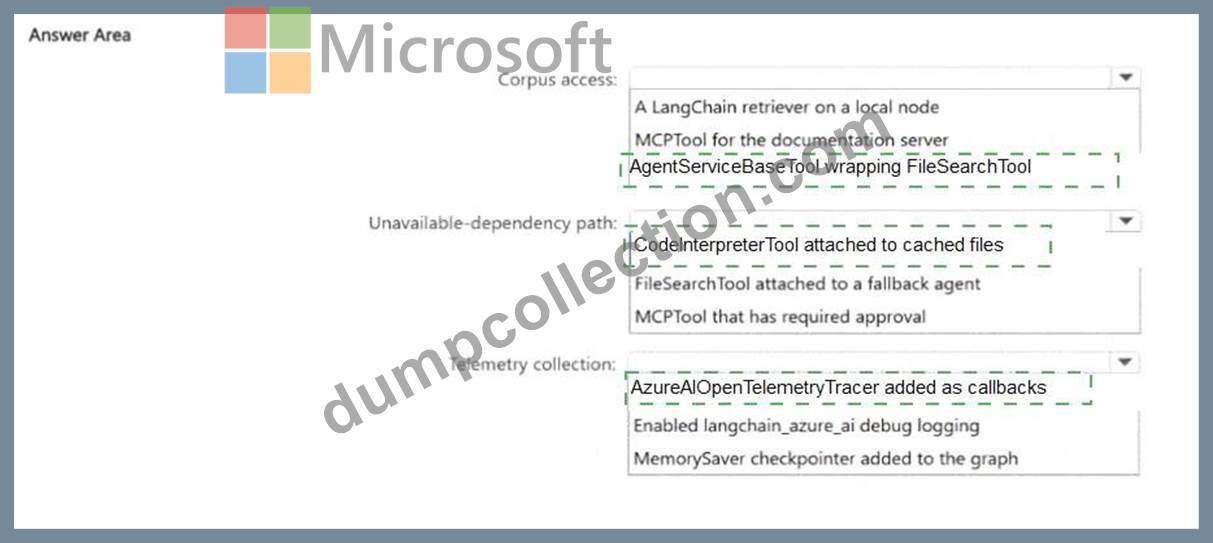
Explanation:
Corpus access: AgentServiceBaseTool wrapping FileSearchTool; Outage fallback: No listed option fully satisfies the requirement to run the cached-policy lookup in the same Azure Container Apps compute; Telemetry: AzureAIOpenTelemetryTracer added as callbacks.
Current Microsoft LangGraph integration guidance supports wrapping Foundry ' s FileSearchTool through AgentServiceBaseTool for the primary project-vector-store path and attaching AzureAIOpenTelemetryTracer through LangGraph callbacks for OpenTelemetry traces. The problematic part is the proposed outage fallback. Code Interpreter is a Foundry-hosted built-in tool, so it does not execute in the same Azure Container Apps compute environment as the LangGraph application. That means a CodeInterpreterTool- based fallback cannot satisfy the explicit same-compute requirement. A technically correct design would use a local LangGraph/LangChain callable or tool over cached policy content mounted or stored with the Container Apps workload. Because that local-tool option is absent from the answer set, there is no fully valid listed selection for the fallback row. The updated answer therefore preserves the two valid selections and explicitly identifies the missing valid option rather than endorsing an inconsistent one. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents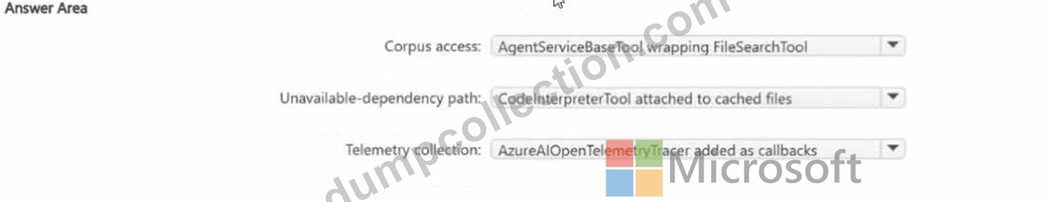
NEW QUESTION # 48
You have a Microsoft Foundry project that contains an incident triage agent.
You have a Model Context Protocol (MCP) server registered in the organizational tool catalog. The MCP server exposes two tools named docs_search and deployment_delete.
You need to ensure that the agent can only invoke docs_search.
What should you configure?
Answer: D
Explanation:
The restriction belongs in the agent ' s MCP tool configuration because Microsoft Foundry supports an
`allowed_tools` allowlist that controls which tools discovered from an MCP server are exposed to the agent.
Configuring the allowlist to include only `docs_search` makes `deployment_delete` unavailable for model selection. This is stronger than adding a sentence to the agent instructions because instructions influence behavior but do not remove a dangerous tool from the callable surface. Project details describe resources rather than per-agent tool exposure, and a transient run setting is not the appropriate persistent configuration boundary for the registered MCP integration. Therefore C, the agent tool configuration, is the correct answer.
Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action.
Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry agents - Model Context Protocol tools
NEW QUESTION # 49
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.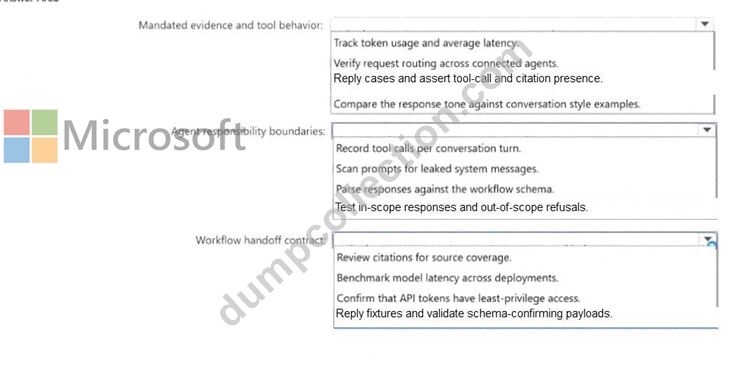
Answer:
Explanation: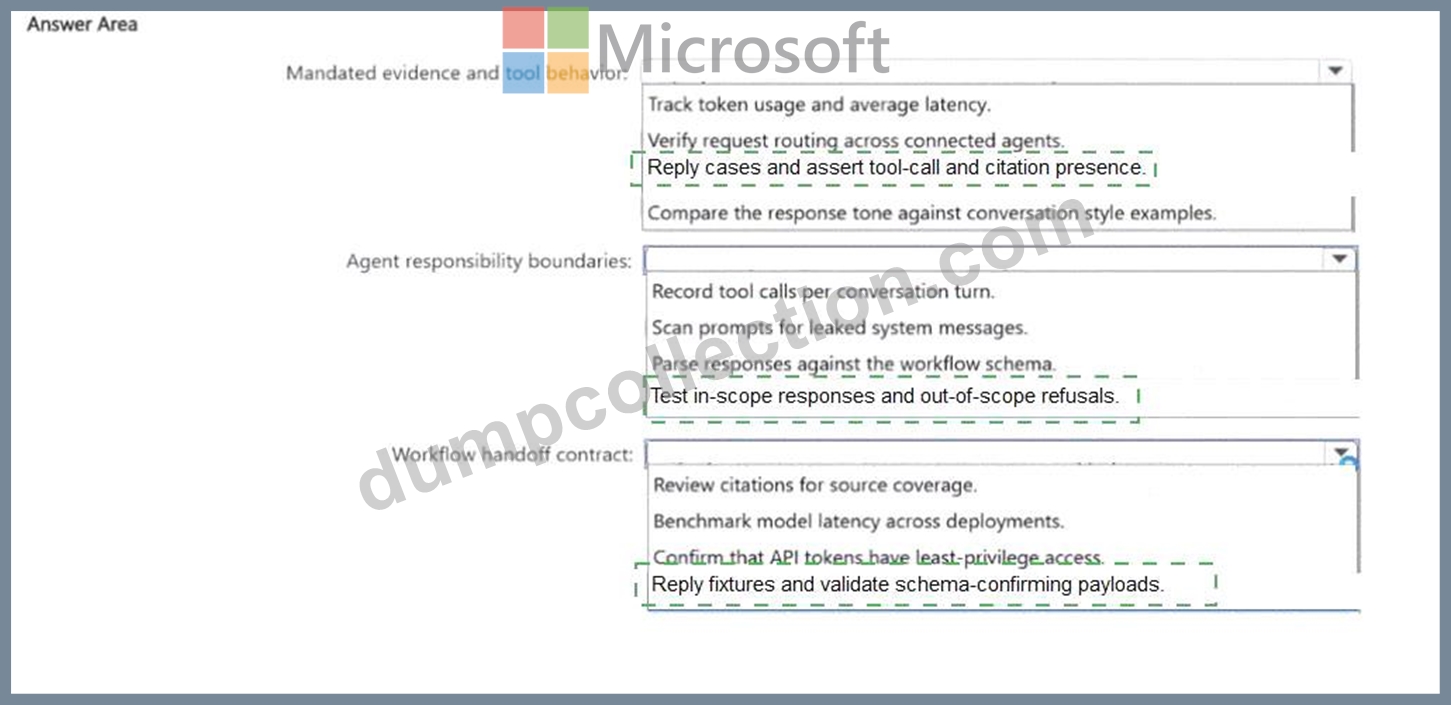
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets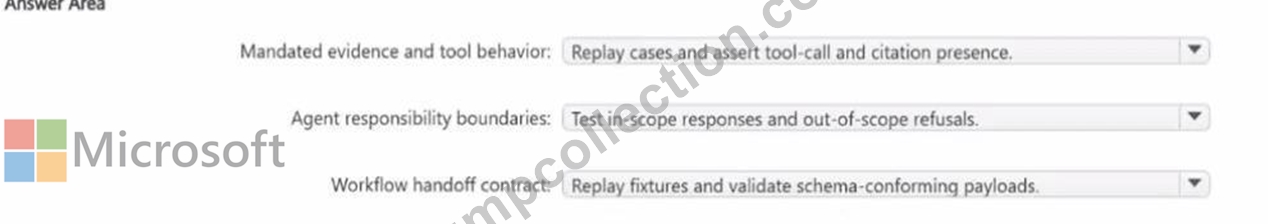
NEW QUESTION # 50
You have a Microsoft Foundry resource that hosts Azure OpenAI model deployments for three projects. Each project is for a different business unit. The projects share the same Foundry resource.
You need to implement a Microsoft Cost Management view that separates the shared model spend by the project The solution must meet the following requirements:
* Use cost data that can be reconciled by using Azure Cost Management.
* Minimize manual tagging.
What should you use?
Answer: A
Explanation:
When multiple projects share one Foundry resource, grouping costs only by Azure resource cannot distinguish project consumption because the resource boundary is shared. Microsoft Foundry integrates with Azure Cost Management by attributing model usage to project metadata/tags, allowing a Cost Analysis view to filter shared resource spending by project. This supports showback or chargeback without requiring administrators to manually tag every usage event. Subscription-level service filters or meter grouping identify the service or billing meter but not which of the three business-unit projects generated the usage. Therefore a Foundry-resource-scoped Cost Analysis view filtered by the project tag is the configuration that both reconciles to Azure Cost Management and minimizes manual tagging. D remains correct. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - Manage costs
NEW QUESTION # 51
You have a Microsoft Foundry multi-agent solution for loan applications. Each agent scores a full application independently and does NOT require output from other agents.
You need to recommend an orchestration pattern that meets the following requirements:
Produces one aggregated recommendation
Preserves independent scoring -
Minimizes end-to-end latency -
Minimize development effort -
What should you recommend?
Answer: A
Explanation:
The scoring agents do not depend on each other ' s output, so their work should be fanned out in parallel and aggregated afterward. Microsoft Agent Framework concurrent orchestration is intended for independent participants that can process the same input simultaneously. That minimizes end-to-end latency because completion time approaches the slowest individual scorer instead of the sum of all scorers. The concurrent workflow also provides a fan-in stage that can aggregate the separate scores into one recommendation without requiring a complex custom conversation protocol. Sequential orchestration wastes time by serializing independent work. Group chat and Magentic-style collaboration introduce unnecessary coordination and planning overhead when the agents simply need independent scoring. Therefore D, concurrent, is the simplest and fastest orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 52
......
There is a ton of Designing and Implementing Multi-Agent AI Solutions (AI-500) prep material available on the internet. But the main thing to notice is their validity and reliability. Many applicants remain unsuccessful in locating the right Designing and Implementing Multi-Agent AI Solutions (AI-500) practice test and lose their time and money.
Study AI-500 Tool: https://www.dumpcollection.com/AI-500_braindumps.html