최신버전Databricks-Machine-Learning-Professional최신버전시험덤프공부완벽한시험대비덤프자료

2026 PassTIP 최신 Databricks-Machine-Learning-Professional PDF 버전 시험 문제집과 Databricks-Machine-Learning-Professional 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1RljKkIvLfBtVSYRroQ4OaJlwW6V9_EIc
PassTIP는 가장 효율높은 Databricks Databricks-Machine-Learning-Professional시험대비방법을 가르쳐드립니다. 저희 Databricks Databricks-Machine-Learning-Professional덤프는 실제 시험문제의 모든 범위를 커버하고 있어 Databricks Databricks-Machine-Learning-Professional덤프의 문제만 이해하고 기억하신다면 제일 빠른 시일내에 시험패스할수 있습니다. 경쟁율이 심한 IT시대에 Databricks Databricks-Machine-Learning-Professional시험 패스만으로 이 사회에서 자신만의 위치를 보장할수 있고 더욱이는 한층 업된 삶을 누릴수도 있습니다.
Databricks Databricks-Machine-Learning-Professional 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| 주제 2 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| 주제 3 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| 주제 4 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| 주제 5 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| 주제 6 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| 주제 7 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| 주제 8 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| 주제 9 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| 주제 10 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| 주제 11 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
>> Databricks-Machine-Learning-Professional최신버전 시험덤프공부 <<
Databricks-Machine-Learning-Professional최신버전 시험덤프문제 & Databricks-Machine-Learning-Professional퍼펙트 최신버전 공부자료
PassTIP을 선택함으로 100%인증시험을 패스하실 수 있습니다. 우리는Databricks Databricks-Machine-Learning-Professional시험의 갱신에 따라 최신의 덤프를 제공할 것입니다. PassTIP에서는 무료로 24시간 온라인상담이 있으며, PassTIP의 덤프로Databricks Databricks-Machine-Learning-Professional시험을 패스하지 못한다면 우리는 덤프전액환불을 약속 드립니다.
최신 ML Data Scientist Databricks-Machine-Learning-Professional 무료샘플문제 (Q34-Q39):
질문 # 34
A Machine Learning Engineer wants to use on-demand features to train a model. They have a Python UDF, which relies on data fetched from a FeatureLookup. However, in online serving, the pipeline falls when the lookup ID is not found. Which solution will resolve this issue?
- A. Log the model correctly via the FeatureEngineeringClient, so it automatically evaluates on- demand features.
- B. Add a default ID when defining the FeatureLookup, so it does not return None values.
- C. Register the UDF to Unity Catalog, so None values are handled automatically.
- D. Update the UDF so that it handles both NaNs and None values.
정답:D
설명:
When an on-demand feature relies on a FeatureLookup, missing lookup keys can result in None values during online serving. Updating the Python UDF to explicitly handle None and NaN values ensures the feature computation is robust to missing lookups, preventing runtime failures while preserving correct behavior during both training and online inference.
질문 # 35
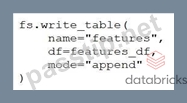
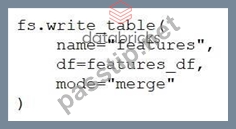
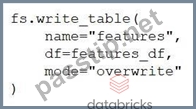
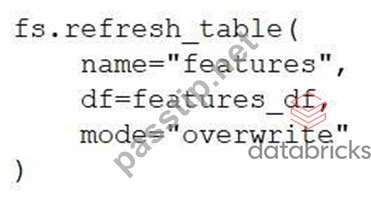
A data scientist has computed updated rows that contain new feature values for primary keys already stored in the Feature Store table features. The updated feature values are stored in the DataFrame features_df. They want to update the rows in features if the associated primary key is in features_df. If a row's primary key is not in features_df, they want the row to remain unchanged in features. Which code block can they use to perform this task using the Feature Store Client fs?
정답:B
설명:
To update existing rows based on primary keys while leaving other rows unchanged, the correct mode to use with fs.write_table() is "merge". This performs an upsert operation - updating rows where keys match and keeping others intact - making it ideal for updating feature values in a Feature Store table.
질문 # 36
A machine learning engineer is migrating a machine learning pipeline to use Databricks Machine Learning. The pipeline needs to automatically refresh its model each time it runs. The project is attached to the existing model model_name in the MLflow Model Registry.
They are using the following code block as part of their solution:
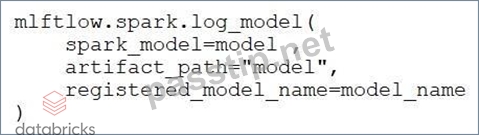
Which statement describes the impact of the registered_model_name=model_name parameter and argument given that model_name already exists in the MLflow Model Registry?
- A. It registers a new model called model_name in the MLflow Model Registry.
- B. It registers the new version of the model_name model in the MLflow Model Registry.
- C. It identifies the name of the logged model in the MLflow Experiment.
- D. It avoids the need to specify the model name in the subsequent required call to mflow.register_model.
정답:B
설명:
When using registered_model_name=model_name in mlflow.spark.log_model(), MLflow automatically registers the logged model under the specified model name. If that model name already exists in the MLflow Model Registry, MLflow creates a new version of that existing registered model rather than a new model entry. This enables automatic versioning and continuous model refresh with each pipeline run.
질문 # 37
A machine learning engineer has developed a random forest model using scikit-learn, logged the model using MLflow as random_forest_model, and stored its run ID in the run_id Python variable. They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df.
Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
- A.
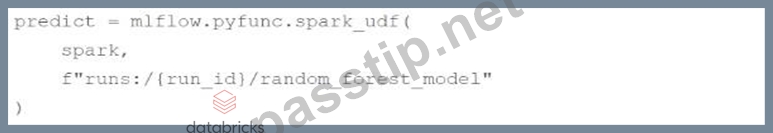
- B.
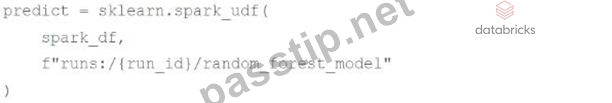
- C.
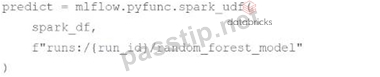
- D.
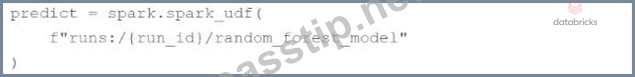
- E. It is not possible to deploy a scikit-learn model on a Spark DataFrame.
정답:D
질문 # 38
A Machine Learning Engineer is using joblibspark and MLflowCallback to perform a distributed hyperparameter tuning experiment via Optuna. Assuming they have a single objective they are optimizing for, what will be the default sampler implemented by Optuna?
- A. GridSampler
- B. NSGAIISampler
- C. RandomSampler
- D. TPESampler
정답:D
설명:
For single-objective optimization, Optuna uses the Tree-structured Parzen Estimator (TPE) sampler by default. TPESampler is a Bayesian optimization method that efficiently explores the hyperparameter space by modeling promising parameter regions, making it well suited for scalable hyperparameter tuning with joblibspark and MLflowCallback.
질문 # 39
......
Databricks인증Databricks-Machine-Learning-Professional시험은 국제적으로 승인해주는 IT인증시험의 한과목입니다. 근 몇년간 IT인사들에게 최고의 인기를 누리고 있는 과목으로서 그 난이도 또한 높습니다. 자격증을 취득하여 직장에서 혹은 IT업계에서 자시만의 위치를 찾으련다면 자격증 취득이 필수입니다. Databricks인증Databricks-Machine-Learning-Professional시험을 패스하고 싶은 분들은PassTIP제품으로 가보세요.
Databricks-Machine-Learning-Professional최신버전 시험덤프문제: https://www.passtip.net/Databricks-Machine-Learning-Professional-pass-exam.html
- 인기자격증 Databricks-Machine-Learning-Professional최신버전 시험덤프공부 시험덤프공부 🐯 무료 다운로드를 위해 지금⇛ www.pass4test.net ⇚에서“ Databricks-Machine-Learning-Professional ”검색Databricks-Machine-Learning-Professional최신 덤프데모
- Databricks-Machine-Learning-Professional최신버전 시험덤프공부 시험 최신 덤프 🏤 「 www.itdumpskr.com 」에서「 Databricks-Machine-Learning-Professional 」를 검색하고 무료 다운로드 받기Databricks-Machine-Learning-Professional최신 업데이트 인증시험자료
- Databricks-Machine-Learning-Professional최신버전 시험덤프공부 시험준비에 가장 좋은 인기시험자료 🚃 시험 자료를 무료로 다운로드하려면⏩ www.itdumpskr.com ⏪을 통해➤ Databricks-Machine-Learning-Professional ⮘를 검색하십시오Databricks-Machine-Learning-Professional최신버전 시험덤프
- Databricks-Machine-Learning-Professional최신버전 시험덤프공부 최신 인증시험 공부자료 🔨 { www.itdumpskr.com }은➤ Databricks-Machine-Learning-Professional ⮘무료 다운로드를 받을 수 있는 최고의 사이트입니다Databricks-Machine-Learning-Professional최신 업데이트버전 인증시험자료
- 시험패스에 유효한 Databricks-Machine-Learning-Professional최신버전 시험덤프공부 최신버전 덤프샘풀문제 다운 받기 🕥 검색만 하면{ www.pass4test.net }에서⇛ Databricks-Machine-Learning-Professional ⇚무료 다운로드Databricks-Machine-Learning-Professional시험대비 인증덤프자료
- Databricks-Machine-Learning-Professional최신버전 시험덤프자료 😧 Databricks-Machine-Learning-Professional인증덤프샘플 다운 🍨 Databricks-Machine-Learning-Professional인증자료 🌀 【 www.itdumpskr.com 】웹사이트를 열고▷ Databricks-Machine-Learning-Professional ◁를 검색하여 무료 다운로드Databricks-Machine-Learning-Professional시험패스 인증덤프
- Databricks-Machine-Learning-Professional최고품질 인증시험자료 🚔 Databricks-Machine-Learning-Professional최신버전 시험덤프 🚜 Databricks-Machine-Learning-Professional최고품질 덤프문제보기 😲 ➡ www.koreadumps.com ️⬅️에서“ Databricks-Machine-Learning-Professional ”를 검색하고 무료 다운로드 받기Databricks-Machine-Learning-Professional최고품질 덤프문제보기
- 인기자격증 Databricks-Machine-Learning-Professional최신버전 시험덤프공부 시험덤프공부 🥯 무료 다운로드를 위해 지금⮆ www.itdumpskr.com ⮄에서“ Databricks-Machine-Learning-Professional ”검색Databricks-Machine-Learning-Professional최고품질 덤프데모 다운
- Databricks-Machine-Learning-Professional최고품질 인증시험자료 ⚾ Databricks-Machine-Learning-Professional합격보장 가능 인증덤프 📱 Databricks-Machine-Learning-Professional최신버전 시험공부자료 ✳ 무료 다운로드를 위해➡ Databricks-Machine-Learning-Professional ️⬅️를 검색하려면▛ www.dumptop.com ▟을(를) 입력하십시오Databricks-Machine-Learning-Professional최고품질 인증시험자료
- Databricks-Machine-Learning-Professional최고품질 덤프문제보기 💌 Databricks-Machine-Learning-Professional최신 업데이트버전 인증시험자료 🦚 Databricks-Machine-Learning-Professional시험대비 공부문제 🤞 무료로 다운로드하려면⏩ www.itdumpskr.com ⏪로 이동하여➤ Databricks-Machine-Learning-Professional ⮘를 검색하십시오Databricks-Machine-Learning-Professional최신 덤프데모
- Databricks-Machine-Learning-Professional시험대비 인증덤프자료 🏔 Databricks-Machine-Learning-Professional완벽한 덤프문제 🔥 Databricks-Machine-Learning-Professional최고품질 인증시험자료 💡 지금▷ www.exampassdump.com ◁을(를) 열고 무료 다운로드를 위해➥ Databricks-Machine-Learning-Professional 🡄를 검색하십시오Databricks-Machine-Learning-Professional최신 업데이트버전 인증시험자료
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, fortunetelleroracle.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
그 외, PassTIP Databricks-Machine-Learning-Professional 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1RljKkIvLfBtVSYRroQ4OaJlwW6V9_EIc