Trustworthy Databricks Certified-Data-Engineer-Professional Practice | Exam Certified-Data-Engineer-Professional PDF

Our Certified-Data-Engineer-Professional exam guide question is recognized as the standard and authorized study materials and is widely commended at home and abroad. Our Certified-Data-Engineer-Professional study materials boost superior advantages and the service of our products is perfect. We choose the most useful and typical questions and answers which contain the key points of the test and we try our best to use the least amount of questions and answers to showcase the most significant information. Our Certified-Data-Engineer-Professional learning guide provides a variety of functions to help the clients improve their learning and pass the Certified-Data-Engineer-Professional exam.
| Section | Objectives |
|---|
| Topic 1: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Topic 2: Data Sharing and Federation | - Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 4: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
|
| Topic 5: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 6: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Configure environments, dependencies, memory, and retry behavior
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Compare streaming tables and materialized views
- 5. Develop unit and integration tests for data processing code
- 6. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 7. Use control flow operators in pipeline components
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Topic 8: Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 9: Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Topic 10: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
|
>> Trustworthy Databricks Certified-Data-Engineer-Professional Practice <<
Exam Certified-Data-Engineer-Professional PDF | Exam Certified-Data-Engineer-Professional Format
The education level of the country has been continuously improved. At present, there are more and more people receiving higher education, and even many college graduates still choose to continue studying in school. Getting the test Certified-Data-Engineer-Professional certification maybe they need to achieve the goal of the learning process, have been working for the workers, have more qualifications can they provide wider space for development. The Certified-Data-Engineer-Professional Study Materials can provide them with efficient and convenient learning platform so that they can get the certification as soon as possible in the shortest possible time.
Databricks Certified Data Engineer Professional Sample Questions (Q61-Q66):
NEW QUESTION # 61
What statement is true regarding the retention of job run history?
- A. It is retained until you export or delete job run logs
- B. It is retained for 90 days or until the run-id is re-used through custom run configuration
- C. It is retained for 60 days, after which logs are archived
- D. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- E. It is retained for 60 days, during which you can export notebook run results to HTML
Answer: E
Explanation:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
NEW QUESTION # 62
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
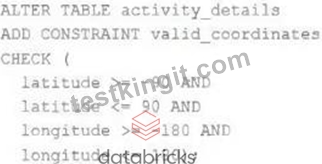
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- B. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- C. The activity details table already exists; CHECK constraints can only be added during initial table creation.
- D. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- E. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
Answer: B
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 63
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion.
However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A. All data should be deleted biweekly; Delta Lake's time travel functionality should be leveraged to maintain a history of non-PII information.
- B. Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
- C. Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
- D. Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
- E. Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
Answer: C
Explanation:
By default partitionning by a column will create a separate folder for each subset data linked to the partition.
NEW QUESTION # 64
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
assert(myIntegrate(lambda x: x*x, 0, 3) [0] == 9)
Which kind of the test does the above line exemplify?
- A. Unit
- B. End-to-end
- C. Integration
- D. functional
- E. Manual
Answer: A
Explanation:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
NEW QUESTION # 65
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
- A. Because the REST API was used for job creation and triggering runs, user identity will not be captured in the audit logs.
- B. Because the REST API was used for job creation and triggering runs, a Service Principal will be automatically used to identity these events.
- C. Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events.
- D. Because User A created the jobs, their identity will be associated with both the job creation events and the job run events.
- E. Because User B last configured the jobs, their identity will be associated with both the job creation events and the job run events.
Answer: C
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 66
......
It is known that our Certified-Data-Engineer-Professional valid study guide materials have dominated the leading position in the global market with the decades of painstaking efforts of our experts and professors. There are many special functions about Certified-Data-Engineer-Professional study materials to help a lot of people to reduce the heavy burdens when they are preparing for the Certified-Data-Engineer-Professional Exams for the Certified-Data-Engineer-Professional study practice question from our company can help all customers to make full use of their sporadic time. Hust buy our Certified-Data-Engineer-Professional exam questions, you will be able to pass the Certified-Data-Engineer-Professional exam easily.
Exam Certified-Data-Engineer-Professional PDF: https://www.testkingit.com/Databricks/latest-Certified-Data-Engineer-Professional-exam-dumps.html
- New Certified-Data-Engineer-Professional Study Guide 🐔 New Certified-Data-Engineer-Professional Test Fee 👙 Certified-Data-Engineer-Professional Latest Test Pdf 🏞 Enter ▛ www.practicevce.com ▟ and search for ( Certified-Data-Engineer-Professional ) to download for free 🌳New Certified-Data-Engineer-Professional Study Guide
- Certified-Data-Engineer-Professional Valid Exam Braindumps 🍡 Reliable Certified-Data-Engineer-Professional Test Camp 🧕 Test Certified-Data-Engineer-Professional Engine 😻 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free on ▛ www.pdfvce.com ▟ website 🌗Test Certified-Data-Engineer-Professional Lab Questions
- Actual Certified-Data-Engineer-Professional Test Answers 🐳 Pass Certified-Data-Engineer-Professional Exam 🌹 Actual Certified-Data-Engineer-Professional Test Answers 💫 Search for ➥ Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ⏩ www.vce4dumps.com ⏪ 🎑Free Certified-Data-Engineer-Professional Practice Exams
- Free Certified-Data-Engineer-Professional Practice Exams 💙 Test Certified-Data-Engineer-Professional Engine 🚅 New Certified-Data-Engineer-Professional Test Voucher 🦍 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download exam materials for free through ⏩ www.pdfvce.com ⏪ 🗼New Certified-Data-Engineer-Professional Study Guide
- Does Databricks Certified-Data-Engineer-Professional Certification Help you Polish your Skills? 🐌 Open ▛ www.exam4labs.com ▟ enter ▶ Certified-Data-Engineer-Professional ◀ and obtain a free download 🛬Test Certified-Data-Engineer-Professional Engine
- Certified-Data-Engineer-Professional Valid Exam Camp 👇 Pass Certified-Data-Engineer-Professional Exam 🏄 Test Certified-Data-Engineer-Professional Dumps 🌜 Simply search for ✔ Certified-Data-Engineer-Professional ️✔️ for free download on ⏩ www.pdfvce.com ⏪ 👭Pass Certified-Data-Engineer-Professional Exam
- Reliable Certified-Data-Engineer-Professional Exam Answers 🔫 Review Certified-Data-Engineer-Professional Guide 🧭 Reliable Certified-Data-Engineer-Professional Test Camp 🍢 Go to website [ www.practicevce.com ] open and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free 🧕Review Certified-Data-Engineer-Professional Guide
- Databricks Reliable Trustworthy Certified-Data-Engineer-Professional Practice – Pass Certified-Data-Engineer-Professional First Attempt ⏺ Easily obtain “ Certified-Data-Engineer-Professional ” for free download through ⮆ www.pdfvce.com ⮄ 🥽New Certified-Data-Engineer-Professional Test Voucher
- Test Certified-Data-Engineer-Professional Lab Questions 🕔 Test Certified-Data-Engineer-Professional Centres 📧 Test Certified-Data-Engineer-Professional Dumps ↗ Open ⇛ www.exam4labs.com ⇚ enter ➠ Certified-Data-Engineer-Professional 🠰 and obtain a free download 🌘Free Certified-Data-Engineer-Professional Practice Exams
- Databricks Reliable Trustworthy Certified-Data-Engineer-Professional Practice – Pass Certified-Data-Engineer-Professional First Attempt 🧎 Easily obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download through ⇛ www.pdfvce.com ⇚ 👜Review Certified-Data-Engineer-Professional Guide
- Real Databricks Certified-Data-Engineer-Professional Dumps PDF Format 🏄 ➽ www.examcollectionpass.com 🢪 is best website to obtain ▛ Certified-Data-Engineer-Professional ▟ for free download 🦪Free Certified-Data-Engineer-Professional Practice Exams
- www.stes.tyc.edu.tw, jobs.electronicsweekly.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, writeablog.net, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, Disposable vapes