選擇我們最好的考試認證資料Certified-Data-Engineer-Professional真題: Databricks Certified Data Engineer Professional,復習準備Databricks Certified-Data-Engineer-Professional很輕松

目前Databricks的Certified-Data-Engineer-Professional認證考試真的是一門人氣很高的考試。還沒有取得這個考試的認證資格的你,是不是也想參加考試呢?確實,這是一門很難的考試。但是這並不代表不能獲得高分輕鬆通過考試。那麼,還不知道通過這個考試的捷徑在哪里的你,是不是想知道通過考試的技巧呢?現在我來告訴你,就是利用Fast2test的Certified-Data-Engineer-Professional考古題。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Implement scalable Python/SQL code and project structures
- Manage dependencies, libraries, and UDFs
|
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools
- Optimize queries, clusters, and storage
|
| Security and Governance | ~10% | - Implement row-level security, column masking, and compliance
- Manage Unity Catalog permissions and ACLs
|
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics
- Implement reliable streaming pipelines
|
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API
- Implement testing and deployment pipelines
|
| Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
>> Certified-Data-Engineer-Professional真題 <<
最新Databricks Certified-Data-Engineer-Professional題庫資訊,Certified-Data-Engineer-Professional最新考證
作為IT認證考試相關資料的專業提供者,Fast2test一直在為考生們提供優秀的參考資料,並且幫助了數不清的人通過了考試。Fast2test的Certified-Data-Engineer-Professional考古題可以給你通過考試的自信,讓你輕鬆地迎接考試。利用這個考古題,只要你經過很短時間段額準備你就可以通過考試。覺得不可思議嗎?但是,這是真的。只要你用,Fast2test就可以讓你看到奇跡的發生。
最新的 Databricks Certification Certified-Data-Engineer-Professional 免費考試真題 (Q206-Q211):
問題 #206
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
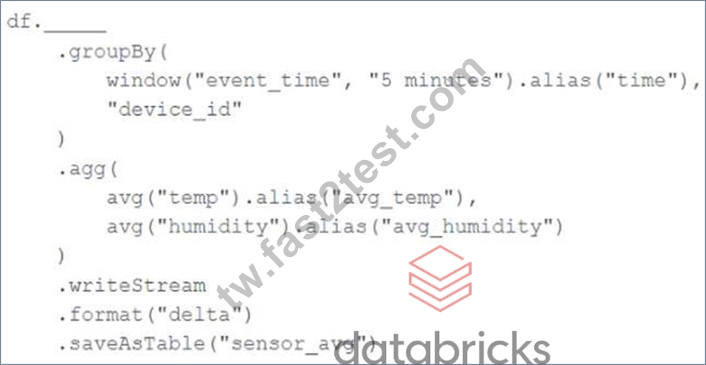
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. await("event_time + `10 minutes'")
- B. withWatermark("event_time", "10 minutes")
- C. awaitArrival("event_time", "10 minutes")
- D. slidingWindow("event_time", "10 minutes")
- E. delayWrite("event_time", "10 minutes")
答案:B
解題說明:
This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming.
問題 #207
Which statement describes the default execution mode for Databricks Auto Loader?
- A. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
- B. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- C. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- D. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- E. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
答案:B
解題說明:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
問題 #208
A data engineer is troubleshooting a slow-running Delta Lake query on Databricks SQL involves complex joins and large datasets. They need to identify whether the root cause is related to poor data skipping, inefficient join strategies, or excessive data shuffling. Which approach should identify the specific bottlenecks using native Databricks tools?
- A. Check the query's execution time in the Jobs UI and correlate it with cluster resource utilization metrics.
- B. Use the LIMIT clause to run a subset of the query and compare execution times with the full dataset.
- C. Analyze the Top Operators panel in the Query Profile to identify high-cost operations like BroadcastNestedLoopJoin
- D. Enable the EXPLAIN command to review the parsed logical plan and manually estimate shuffle sizes.
答案:C
解題說明:
The Query Profile's Top Operators panel surfaces the most expensive operators in the query execution, making it possible to directly identify bottlenecks such as inefficient join strategies, poor data skipping, or excessive shuffling. This native visualization highlights where time and resources are spent, enabling precise root-cause analysis for slow-running queries.
問題 #209
A data engineer is designing a secure data sharing strategy for their organization. The company needs to share sensitive customer analytics data with two different partners. Partner A uses Databricks with Unity Catalog enabled, while Partner B uses Apache Spark on AWS without Databricks. How should the company implement secure data sharing for these scenarios?
- A. For Partner A, implement Databricks-to-Databricks sharing (D2D) with Unit Catalog integration and no-token exchange system. For Partner B, use open sharing protocol (D2O) with either bearer tokens or OIDC federation for authentication, ensuring both approaches maintain robust security and governance.
- B. Open sharing protocol (D2O) should be used for both partners because it provides better security than D2D sharing. The bearer token approach is always more secure than Unity Catalog's native authentication.
- C. Databricks-to-Databricks sharing (D2D) can only be used within the same cloud provider, so you must use open sharing (D2O) for any cross-cloud scenarios. Unit Catalog governance is not available when sharing with external platforms.
- D. Both partners should use the same Delta Sharing approach since security requirements are identical. You should create bearer tokens for both partners and use the open sharing protocol (D2O) for maximum compatibility.
答案:A
解題說明:
Databricks-to-Databricks sharing with Unity Catalog provides the most seamless and secure option for Partner A by enabling native governance, fine-grained access controls, and a no-token exchange model. For Partner B, which does not use Databricks, the open sharing protocol enables secure access from external Spark environments using standard authentication mechanisms such as bearer tokens or OIDC federation, while still enforcing sharing policies and protecting sensitive data.
問題 #210
Which statement describes Delta Lake optimized writes?
- A. An asynchronous job runs after the write completes to detect if files could be further compacted; yes, an OPTIMIZE job is executed toward a default of 1 GB.
- B. A shuffle occurs prior to writing to try to group data together resulting in fewer files instead of each executor writing multiple files based on directory partitions.
- C. Before a job cluster terminates, OPTIMIZE is executed on all tables modified during the most recent job.
- D. Optimized writes logical partitions instead of directory partitions partition boundaries are only represented in metadata fewer small files are written.
答案:B
解題說明:
Delta Lake optimized writes involve a shuffle operation before writing out data to the Delta table.
The shuffle operation groups data by partition keys, which can lead to a reduction in the number of output files and potentially larger files, instead of multiple smaller files. This approach can significantly reduce the total number of files in the table, improve read performance by reducing the metadata overhead, and optimize the table storage layout, especially for workloads with many small files.
問題 #211
......
機會從來都是屬於那些有準備的人。但是,當屬於我們的機會到來的時候我們是否能成功地抓住它呢?正在準備Databricks的Certified-Data-Engineer-Professional考試的你,是否抓住了Fast2test這個可以讓你成功的機會呢?Fast2test的Certified-Data-Engineer-Professional資料是你可以順利通過考試的保障,有了它,你將節省大量的時間,高效率地準備考試。如果你用了Fast2test的資料,你可以很明顯地感覺到它的與眾不同和它的高品質。這絕對是你成功的一個捷徑。它可以讓你充分地準備Certified-Data-Engineer-Professional考試。
最新Certified-Data-Engineer-Professional題庫資訊: https://tw.fast2test.com/Certified-Data-Engineer-Professional-premium-file.html
- 最新上傳的Certified-Data-Engineer-Professional真題 -Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional 🔖 ➤ www.vcesoft.com ⮘上搜索⇛ Certified-Data-Engineer-Professional ⇚輕鬆獲取免費下載Certified-Data-Engineer-Professional認證考試
- Certified-Data-Engineer-Professional權威考題 🍶 Certified-Data-Engineer-Professional考試備考經驗 🌅 最新Certified-Data-Engineer-Professional題庫資源 📟 在⏩ www.newdumpspdf.com ⏪網站上查找➥ Certified-Data-Engineer-Professional 🡄的最新題庫Certified-Data-Engineer-Professional熱門認證
- Certified-Data-Engineer-Professional真題-最新Certified-Data-Engineer-Professional考試題庫幫助妳壹次性通過考試 🎌 免費下載「 Certified-Data-Engineer-Professional 」只需進入➥ www.pdfexamdumps.com 🡄網站Certified-Data-Engineer-Professional熱門認證
- 最受推薦的的Certified-Data-Engineer-Professional真題,覆蓋全真Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional考試考題 🟠 免費下載[ Certified-Data-Engineer-Professional ]只需在⏩ www.newdumpspdf.com ⏪上搜索Certified-Data-Engineer-Professional題庫分享
- Certified-Data-Engineer-Professional考題資訊 🕶 Certified-Data-Engineer-Professional權威認證 🥫 Certified-Data-Engineer-Professional熱門認證 🤗 立即到{ www.newdumpspdf.com }上搜索「 Certified-Data-Engineer-Professional 」以獲取免費下載Certified-Data-Engineer-Professional權威考題
- 高質量的Certified-Data-Engineer-Professional真題,Databricks Databricks Certification認證Certified-Data-Engineer-Professional考試題庫提供免費下載 👞 《 www.newdumpspdf.com 》上搜索{ Certified-Data-Engineer-Professional }輕鬆獲取免費下載Certified-Data-Engineer-Professional權威考題
- Certified-Data-Engineer-Professional真題 - 您通過Databricks Certified Data Engineer Professional的可靠支持 🤕 免費下載➡ Certified-Data-Engineer-Professional ️⬅️只需在( www.vcesoft.com )上搜索Certified-Data-Engineer-Professional題庫資訊
- Certified-Data-Engineer-Professional套裝 🦇 Certified-Data-Engineer-Professional權威認證 🕎 Certified-Data-Engineer-Professional考題寶典 ⛲ 打開網站⮆ www.newdumpspdf.com ⮄搜索➡ Certified-Data-Engineer-Professional ️⬅️免費下載Certified-Data-Engineer-Professional考試備考經驗
- Certified-Data-Engineer-Professional最新試題 🐓 最新Certified-Data-Engineer-Professional考證 🍅 Certified-Data-Engineer-Professional題庫分享 😖 立即打開➤ www.newdumpspdf.com ⮘並搜索⇛ Certified-Data-Engineer-Professional ⇚以獲取免費下載Certified-Data-Engineer-Professional題庫分享
- 一流的Databricks Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional真題 - 確保通過的Newdumpspdf 最新Certified-Data-Engineer-Professional題庫資訊 🌼 免費下載➠ Certified-Data-Engineer-Professional 🠰只需在▛ www.newdumpspdf.com ▟上搜索最新Certified-Data-Engineer-Professional考證
- 最真實的Certified-Data-Engineer-Professional認證考試資料庫 🔆 在⇛ www.newdumpspdf.com ⇚搜索最新的☀ Certified-Data-Engineer-Professional ️☀️題庫最新Certified-Data-Engineer-Professional考證
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, swipy.ru, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes