Pass4Test 는 여러분의 IT전문가의 꿈을 이루어 드리는 사이트 입다. Pass4Test는 여러분이 우리 자료로 관심 가는 인중시험에 응시하여 안전하게 자격증을 취득할 수 있도록 도와드립니다. 아직도Microsoft 인증DP-800 인증시험으로 고민하시고 계십니까? Microsoft 인증DP-800인증시험 가이드를 사용하실 생각은 없나요? Pass4Test는 여러분께 시험패스의 편리를 드릴 수 있습니다.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Exam Price: | $165 USD |
| Passing Score: | 700 (on a scale of 1-1000) |
| Exam Duration: | 100 minutes |
| Certificate Validity Period: | 1 year (renewable annually via free online assessment) |
| Exam Format: | Drag and drop, Multiple select, Active screen, Multiple choice, Case studies |
| Real Exam Qty: | 40-60 |
| Available Languages: | German, English, Chinese (Simplified), Portuguese (Brazil), Spanish, Korean, French, Japanese |
| Recommended Training: | Microsoft Learn DP-800 Learning Path |
| Exam Registration: | Pearson VUE Registration |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended experience: T-SQL development, SQL Server/Azure SQL, CI/CD practices, basic AI concepts |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-800 |
Microsoft DP-800인증시험을 패스하고 자격증 취득으로 하여 여러분의 인생은 많은 인생역전이 이루어질 것입니다. 회사, 생활에서는 물론 많은 업그레이드가 있을 것입니다. 하지만DP-800시험은Microsoft인증의 아주 중요한 시험으로서DP-800시험패스는 쉬운 것도 아닙니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
질문 # 59
You have an Azure SQL database named SalesDB
You have a Data API builder (DAB) instance that exposes the following entities in SalesDB
* A table entity named Order mapped to a table named dbo. Orders
* A stored procedure entity named FinalizeOrder mapped to a stored procedure named dbo.usp_FinalizeOrder The DAB runtime configuration includes the following permissions.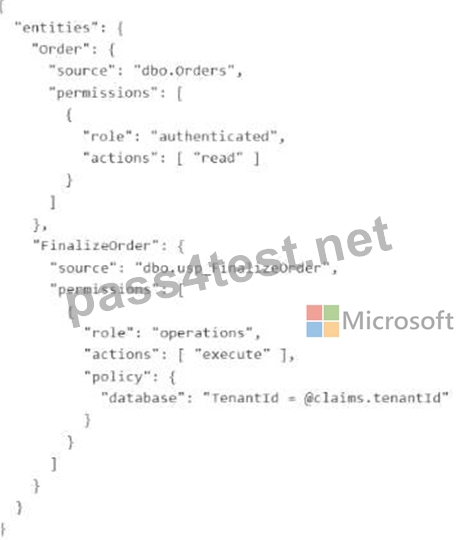
Client requests include a Microsoft Entra access token. The client also sends HTTP header x-MS-APl-ROlE:
operations for both REST and GraphQL requests.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.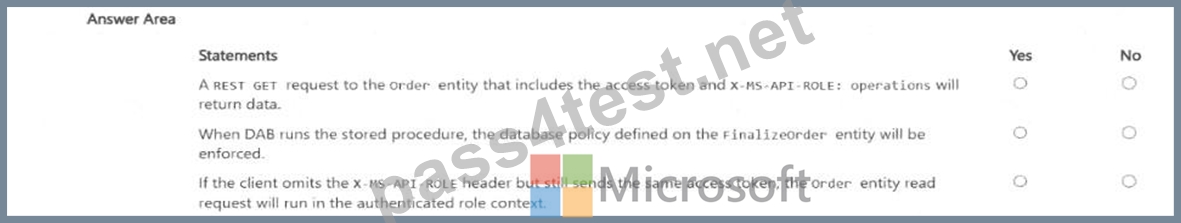
정답:
설명: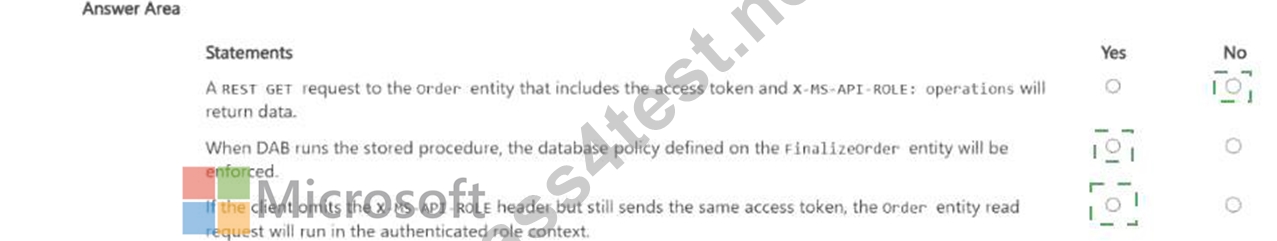
Explanation:
* A REST GET request to the order entity that includes the access token and x-MS-API-ROLE:
operations will return data. # No
* When DAB runs the stored procedure, the database policy defined on the FinalizeOrder entity will be enforced. # Yes
* If the client omits the x-MS-API-ROLE header but still sends the same access token, the order entity read request will run in the authenticated role context. # Yes The first statement is No . In Data API builder, when a valid token is sent with X-MS-API-ROLE, the request runs in that requested role if that role is present in the token . Here, that means the effective role becomes operations , not authenticated. But the order entity grants read only to the authenticated role, not to operations, so the GET request would not be authorized to return data.
The second statement is Yes . DAB evaluates the request against the permissions and policies configured for the effective role on the requested entity. The FinalizeOrder entity grants execute to role operations and includes a database policy of TenantId = @claims.tenantid, so that policy is part of the enforced authorization
/filtering behavior when the stored procedure entity is executed.
The third statement is Yes . If the client sends a valid access token without X-MS-API-ROLE, DAB uses the built-in Authenticated system role by default. Since the order entity allows read for the authenticated role, that read request runs in the authenticated role context.
Top of Form
Bottom of Form
질문 # 60
You have an Azure SQL database that contains a table named dbo.ManualChunks. dbo.HonualChunks contains product manuals A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpomt for chat completions. The request body must include both the user question and theretiieved chunks.
You write the following Transact-SQL code.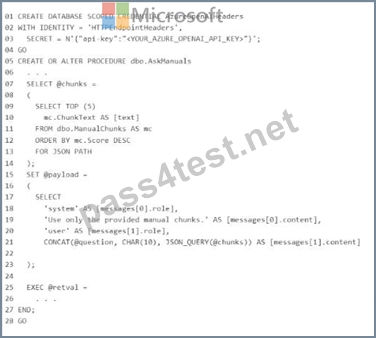
What should you insert at line 22?
정답:A
설명:
The correct insertion at line 22 is FOR JSON PATH, WITHOUT_ARRAY_WRAPPER .
The request body for the Azure OpenAI chat completions call must be a single JSON object containing the messages array with both the system/user content and the retrieved chunks. Microsoft documents that FOR JSON PATH is the preferred way to shape JSON output, especially when you want precise control over nested property names like messages[0].role and messages[1] .content.
The key detail is WITHOUT_ARRAY_WRAPPER . By default, FOR JSON returns results enclosed in square brackets as a JSON array. Microsoft documents that WITHOUT_ARRAY_WRAPPER removes those brackets so a single JSON object is produced instead. That is exactly what is needed here for @payload, because the stored procedure is building one request body, not an array of request bodies.
질문 # 61
You have an Azure SQL database that stores sales data and contains tables named Sales and Products . Sales contains three columns named SalesDate , ProductKey , and TotalSale .
Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales , filter on SalesDate or ProductKey , and use SUM() to aggregate TotalSale .
Products is relatively small and is used primarily for point lookups and joins to Sales .
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.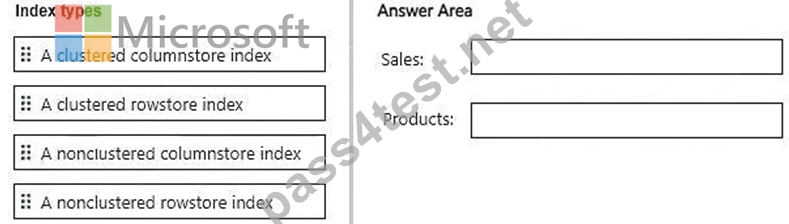
정답:
설명: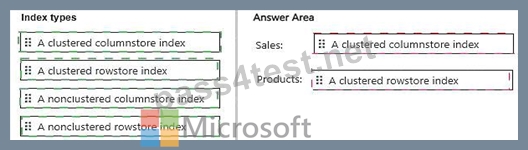
Explanation:
* Sales # A clustered columnstore index
* Products # A clustered rowstore index
For Sales , the correct choice is a clustered columnstore index . Microsoft identifies clustered columnstore indexes as the standard storage choice for large fact tables and analytical/data-warehouse workloads . The Sales table is 10 TB, loaded in nightly batches, and its reporting queries scan large portions of the table and perform aggregations such as SUM(TotalSale) . Those are exactly the workload characteristics that benefit from columnstore storage, batch-mode execution, aggregate pushdown, and high compression. Microsoft also notes that clustered columnstore indexes can provide substantial storage reduction compared with traditional uncompressed rowstore structures, which directly supports the requirement to minimize storage requirements .
For Products , the correct choice is a clustered rowstore index . Microsoft states that rowstore B-tree indexes perform best for point lookups, equality searches, and small-range retrieval , whereas columnstore is optimized for large analytical scans. Since Products is relatively small and primarily supports point lookups and joins to Sales , a rowstore structure is the better fit.
A nonclustered columnstore index would retain the underlying rowstore and add another compressed copy of selected columns, increasing storage. That is more appropriate for real-time analytics over an OLTP table, not for this dedicated large analytical fact table.
질문 # 62
You have an Azure SQL table that contains the following data.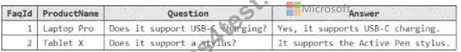
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
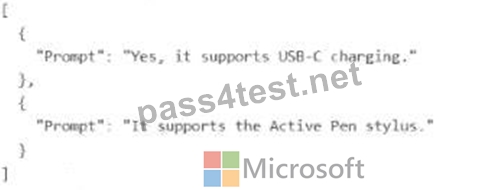
Which formal should you use to send the data to the LLM?
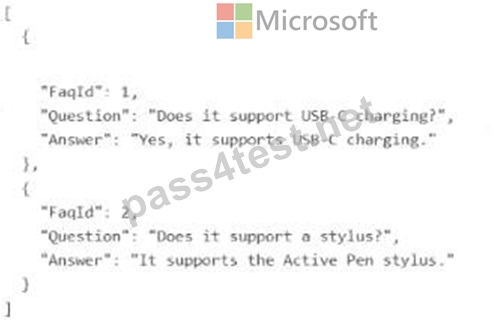
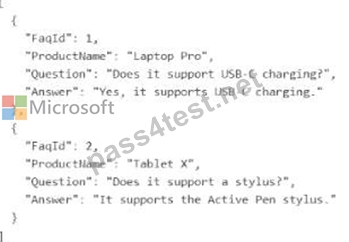
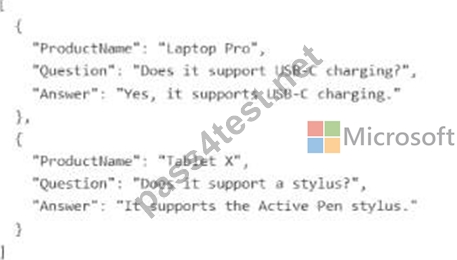
정답:D
설명:
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
질문 # 63
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.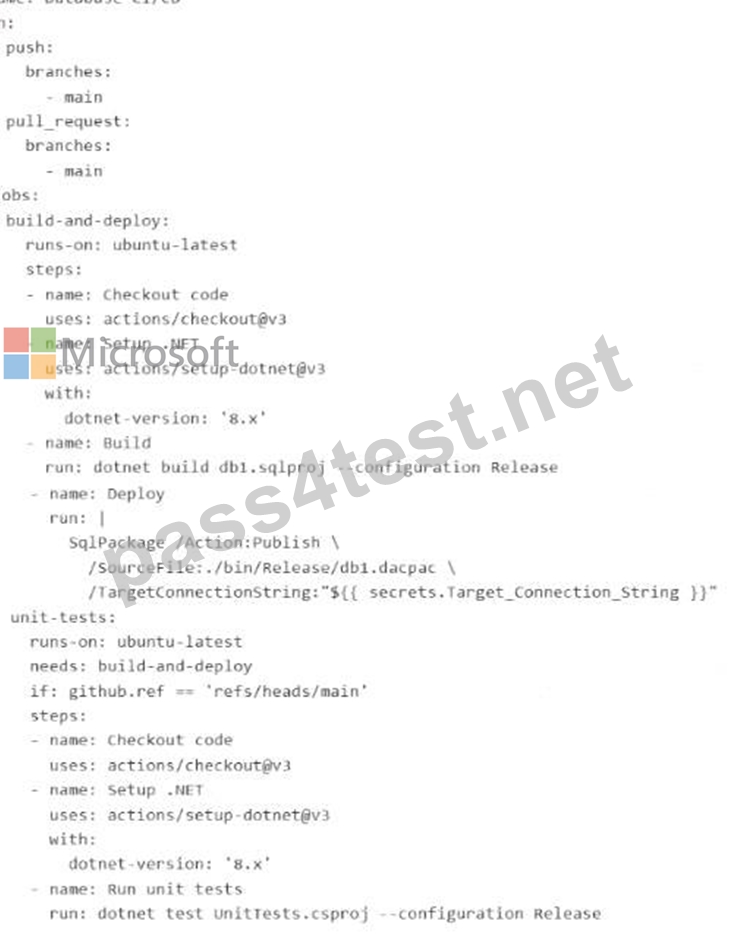
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.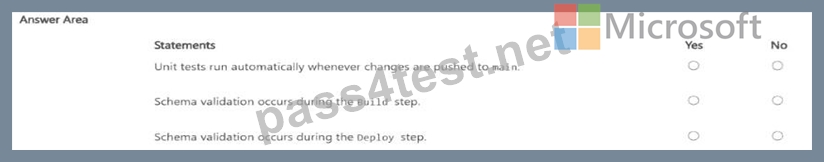
정답:
설명: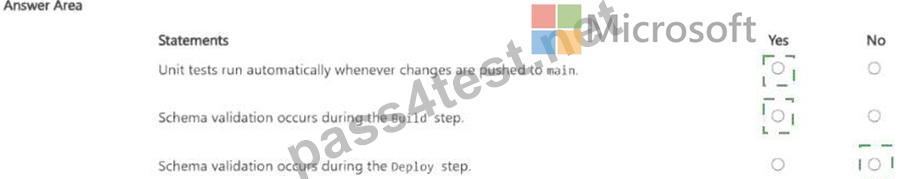
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
질문 # 64
......
DP-800최신덤프: https://www.pass4test.net/DP-800.html