BTW, DOWNLOAD part of ValidVCE Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1gXnFHA032hOiLQxRkgxTfS2aljm45U40
ValidVCE offers the complete package that includes all exam questions conforming to the syllabus for passing the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam certificate in the first try. These formats of actual Databricks Databricks-Certified-Professional-Data-Engineer Questions are specifically designed to make preparation easier for you.
Databricks Certified Professional Data Engineer Exam is an excellent way for data engineers to demonstrate their expertise in working with the Databricks platform. It provides employers with a way to validate the skills of potential candidates and ensures that data engineers have the knowledge and skills needed to work with Databricks effectively.
>> Latest Databricks-Certified-Professional-Data-Engineer Guide Files <<
So many candidates have encountered difficulties in preparing to pass the Databricks-Certified-Professional-Data-Engineer exam. But our study materials will help candidates to pass the exam easily. Our Databricks-Certified-Professional-Data-Engineer guide questions can provide statistics report function to help the learners to find weak links and deal with them. The Databricks-Certified-Professional-Data-Engineer Test Torrent boost the function of timing and simulating the exam. They set the timer to simulate the exam and help the learners adjust the speed and keep alert.
The Databricks Databricks-Certified-Professional-Data-Engineer Exam is intended for data engineers with experience in designing and implementing data solutions using Databricks. Candidates for this certification should have a good understanding of data engineering concepts, data processing frameworks, and programming languages such as Python and SQL. They should also be familiar with cloud platforms such as AWS, Azure, and Google Cloud Platform.
NEW QUESTION # 173
Which of the following locations hosts the driver and worker nodes of a Databricks-managed clus-ter?
Answer: E
Explanation:
Explanation
The answer is Data Plane, which is where compute(all-purpose, Job Cluster, DLT) are stored this is generally a customer cloud account, there is one exception SQL Warehouses, currently there are 3 types of SQL Warehouse compute available(classic, pro, serverless), in classic and pro compute is located in customer cloud account but serverless computed is located in Databricks cloud account.
Diagram, timeline Description automatically generated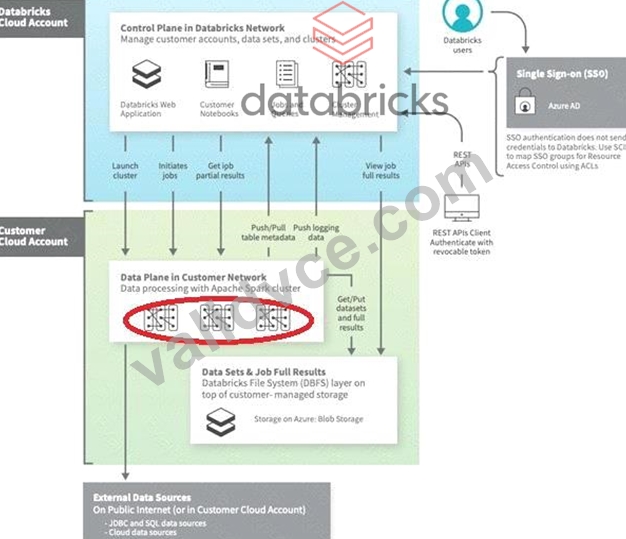
NEW QUESTION # 174
Which statement regarding spark configuration on the Databricks platform is true?
Answer: A
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
Reference:
Databricks documentation on configuring clusters: https://docs.databricks.com/clusters/configure.html
NEW QUESTION # 175
Data science team has requested they are missing a column in the table called average price, this can be calculated using units sold and sales amt, which of the following SQL statements allow you to reload the data with additional column
Answer: E
Explanation:
Explanation
1.CREATE OR REPLACE TABLE sales
2.AS SELECT *, salesAmt/unitsSold as avgPrice FROM sales
The main difference between INSERT OVERWRITE and CREATE OR REPLACE TABLE(CRAS) is that CRAS can modify the schema of the table, i.e it can add new columns or change data types of existing columns. By default INSERT OVERWRITE only overwrites the data.
INSERT OVERWRITE can also be used to overwrite schema, only when
spark.databricks.delta.schema.autoMerge.enabled is set true if this option is not enabled and if there is a schema mismatch command will fail.
NEW QUESTION # 176
A data engineer is using Auto Loader to read incoming JSON data as it arrives. They have configured Auto Loader to quarantine invalid JSON records but notice that over time, some records are being quarantined even though they are well-formed JSON .
The code snippet is:
df = (spark.readStream
.format( " cloudFiles " )
.option( " cloudFiles.format " , " json " )
.option( " badRecordsPath " , " /tmp/somewhere/badRecordsPath " )
.schema( " a int, b int " )
.load( " /Volumes/catalog/schema/raw_data/ " ))
What is the cause of the missing data?
Answer: C
Explanation:
Databricks Auto Loader quarantines records that fail schema validation, even if they are syntactically valid JSON . The documentation explains that "records that do not match the defined schema are considered corrupt and written to the bad records path." In this case, the data likely contains valid JSON fields whose structure or data types differ from the declared schema (a int, b int). For example, if a field expected as an integer arrives as a string, Auto Loader will quarantine it. The presence of badRecordsPath confirms this behavior. The cloudFiles.quarantineMode option controls quarantine behavior but is unrelated to valid data that fails schema validation. Thus, the correct cause is C .
NEW QUESTION # 177
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
Answer: A
Explanation:
The configuration that automatically recovers from query failures and keeps costs low is to use a new job cluster, set retries to unlimited, and set maximum concurrent runs to 1. This configuration has the following advantages:
A new job cluster is a cluster that is created and terminated for each job run. This means that the cluster resources are only used when the job is running, and no idle costs are incurred. This also ensures that the cluster is always in a clean state and has the latest configuration and libraries for the job1.
Setting retries to unlimited means that the job will automatically restart the query in case of any failure, such as network issues, node failures, or transient errors. This improves the reliability and availability of the streaming job, and avoids data loss or inconsistency2.
Setting maximum concurrent runs to 1 means that only one instance of the job can run at a time. This prevents multiple queries from competing for the same resources or writing to the same output location, which can cause performance degradation or data corruption3.
Therefore, this configuration is the best practice for scheduling Structured Streaming jobs for production, as it ensures that the job is resilient, efficient, and consistent.
NEW QUESTION # 178
......
Exam Databricks-Certified-Professional-Data-Engineer Collection Pdf: https://www.validvce.com/Databricks-Certified-Professional-Data-Engineer-exam-collection.html
P.S. Free 2026 Databricks Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by ValidVCE: https://drive.google.com/open?id=1gXnFHA032hOiLQxRkgxTfS2aljm45U40