
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=1iQ6rJjq-BjIZddTVxkVpt1Nsqmrq7RQN
Many people are difficult in getting the MLA-C01 certification successfully. If you also have trouble in passing your exam and getting your certification, we think it is time for you to use our AWS Certified Associate quiz prep. If you choose our study materials and use our products well, we can promise that you can pass the exam and get the MLA-C01 Certification. Then you will find you have so many chances to advance in stages to a great level of social influence and success. Our MLA-C01 dumps torrent can also provide all candidates with our free demo, in order to exclude your concerts that you can check our products.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Intereactive MLA-C01 Testing Engine <<
Many people are difficult in getting the MLA-C01 certification successfully. If you also have trouble in passing your exam and getting your certification, we think it is time for you to use our AWS Certified Associate quiz prep. If you choose our study materials and use our products well, we can promise that you can pass the exam and get the MLA-C01 Certification. Then you will find you have so many chances to advance in stages to a great level of social influence and success. Our MLA-C01 dumps torrent can also provide all candidates with our free demo, in order to exclude your concerts that you can check our products.
NEW QUESTION # 234
A company wants to use large language models (LLMs) that are supported by Amazon Bedrock to develop a chat interface for the company ' s internal technical documentation. The company stores the documentation as dozens of text files that are several megabytes in total size. The company updates the text files often.
Which solution will meet these requirements MOST cost-effectively?
Answer: B
Explanation:
Option D is correct because Amazon Bedrock Knowledge Bases are designed for applications that need to answer questions using private documents without retraining or repeatedly fine-tuning a foundation model.
AWS documentation states that with Amazon Bedrock Knowledge Bases, you can build applications enriched by context retrieved from a knowledge base, and that this provides an out-of-the-box RAG solution. AWS also explicitly says that adding a knowledge base increases cost-effectiveness by removing the need to continually train your model to use your private data. That matches this use case very closely.
The question also says the documentation consists of text files that are only several megabytes total and are updated often. A retrieval-based approach is more economical and operationally simpler than creating a new model or repeatedly fine-tuning one whenever the documents change. AWS documentation for Bedrock knowledge bases describes adding data sources and running ingestion jobs to process and index the content, which is exactly the pattern needed for frequently updated internal documentation used by a chat interface.
The other options are not as cost-effective. Creating a new LLM is far beyond the need here. Guardrails help control model behavior and policy enforcement, but they do not serve as a document retrieval layer for internal documentation. Fine-tuning a model on frequently changing text files is usually more expensive and less flexible than using retrieval augmentation. For a modest-sized, frequently updated documentation corpus, the AWS-native and most cost-effective solution is to load the files into an Amazon Bedrock knowledge base and use it to provide context at inference time. Therefore, the best verified answer is D.
NEW QUESTION # 235
A company needs to update the model definition of an existing Amazon SageMaker Al endpoint.
Select and order the correct steps from the following list to update the model definition settings with the LEAST interruption of inferences. Select each step one time or not at all. (Select and order THREE.)
* Create a new endpoint configuration that uses the new model definition.
* Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
* Delete the endpoint that needs to be updated and recreate the endpoint with the new endpoint configuration.
* Delete the IAM role and permissions for the ExecutionRoleArn parameter.
* Update the endpoint with the new endpoint configuration.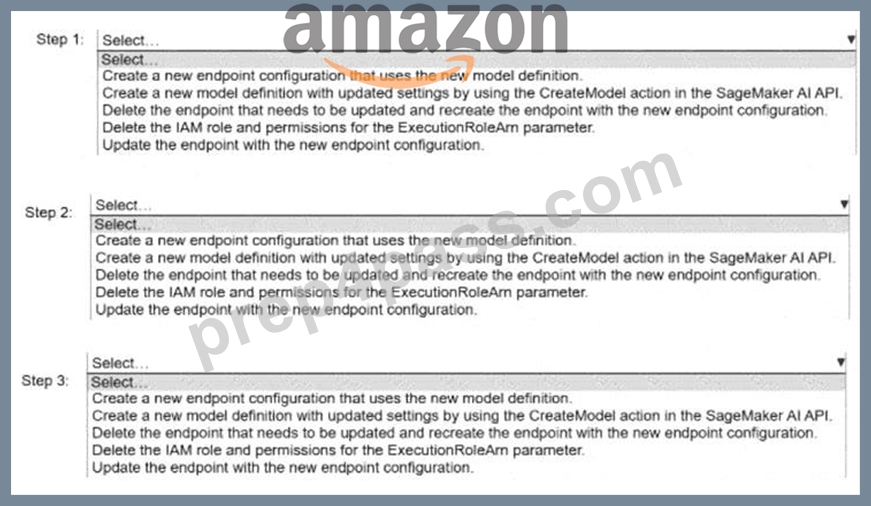
Answer:
Explanation: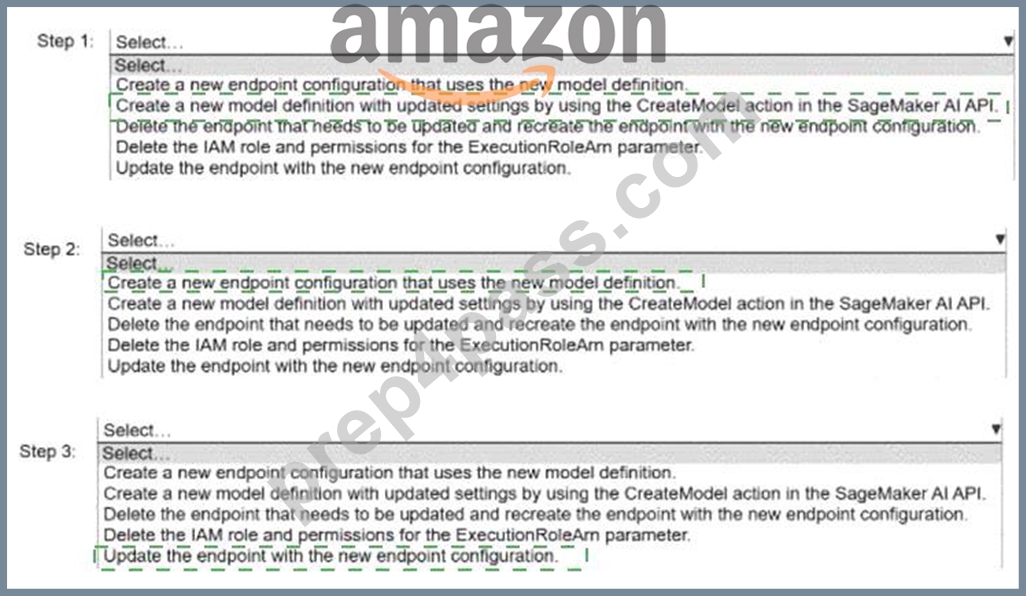
Explanation:
Step 1: Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
Step 2: Create a new endpoint configuration that uses the new model definition.
Step 3: Update the endpoint with the new endpoint configuration.
Do not delete and recreate the endpoint. That causes unnecessary inference interruption. SageMaker endpoint updates are designed to use a new EndpointConfig; AWS explicitly states that to update an endpoint, you must create a new endpoint configuration, then call UpdateEndpoint on the existing endpoint. During the update, SageMaker changes the endpoint to Updating and then back to InService.
NEW QUESTION # 236
An ML engineer is deploying a generative AI model-based customer support agent that uses Amazon SageMaker AI for inference. The customer support agent must respond to customer questions about topics such as shipping policies, refund processes, and account management. The generative AI model generates one token at a time.
Customers report dissatisfaction with how long the customer support agent takes to generate lengthy responses to questions. The ML engineer must apply an inference optimization technique to improve the performance of the customer support agent.
Which solution will meet this requirement?
Answer: B
Explanation:
Option B is correct because AWS documentation states that speculative decoding is specifically a technique to speed up the decoding process of large language models. The question highlights that the model generates one token at a time and that users are unhappy with the time needed to generate lengthy responses. That is exactly the stage of inference targeted by speculative decoding. AWS explains that this method improves latency without compromising the quality of the generated text.
According to AWS, speculative decoding works by using a smaller, faster draft model to generate candidate tokens first. The larger target model then verifies those tokens. AWS further explains that the draft model can generate multiple candidate tokens quickly, and the target model evaluates them in parallel, which speeds up the final response. This directly addresses the problem in the scenario: the customer support agent is slow not because of startup time, but because long answers require many decoding steps.
The other options are not the best fit. Compilation reduces deployment time and auto-scaling latency through ahead-of-time compilation, but AWS documents it primarily as helping model deployment and hardware optimization rather than token-by-token response generation. Quantization reduces hardware requirements and can lower cost, but the docs do not present it as the most direct answer to slow sequential decoding. Fast model loading improves how quickly the model loads onto instances, which helps startup and scale-out time, not long response generation after the model is already serving traffic. Therefore, the best AWS-documented answer is B.
NEW QUESTION # 237
A company launches a feature that predicts home prices. An ML engineer trained a regression model using the SageMaker AI XGBoost algorithm. The model performs well on training data but underperforms on real- world validation data.
Which solution will improve the validation score with the LEAST implementation effort?
Answer: D
Explanation:
This scenario indicates overfitting. AWS documentation for XGBoost recommends increasing the L2 regularization parameter (lambda) to reduce overfitting and improve generalization.
Increasing num_round worsens overfitting. Changing evaluation metrics does not change model behavior.
Collecting more data is effective but requires significant effort.
Regularization is a low-effort, high-impact fix.
Therefore, Option D is correct.
NEW QUESTION # 238
An ML engineer is developing a neural network to run on new user data. The dataset has dozens of floating- point features. The dataset is stored as CSV objects in an Amazon S3 bucket. Most objects and columns are missing at least one value. All features are relatively uniform except for a small number of extreme outliers.
The ML engineer wants to use Amazon SageMaker Data Wrangler to handle missing values before passing the dataset to the neural network.
Which solution will provide the MOST complete data?
Answer: A
Explanation:
The primary goal is to produce the most complete dataset while handling missing values and extreme outliers appropriately. Dropping samples (Option A) or columns (Option D) would reduce data completeness and potentially remove valuable information, which contradicts the requirement.
Imputation is therefore the correct approach. Between mean and median imputation, AWS ML best practices recommend using the median when features contain outliers. The mean is sensitive to extreme values and can be skewed significantly, leading to imputed values that are not representative of the typical data distribution.
In contrast, the median is robust to outliers, making it a better statistical estimator for central tendency in such datasets.
Amazon SageMaker Data Wrangler supports median imputation as a built-in transformation, enabling ML engineers to handle missing values consistently across large tabular datasets without custom code. This approach preserves all rows and columns while minimizing distortion caused by extreme values, which is particularly important for neural networks that are sensitive to input distributions.
Therefore, imputing missing values with the median value provides the most complete and statistically appropriate dataset for training.
NEW QUESTION # 239
......
We take the leader position in the career of assisting the candidates in passing their MLA-C01 exams and gaining their dreaming certifications. On the way to be successful, a large number of the candidates feel upset or disturbed when they study with the books or other MLA-C01 Exam Materials. With our high pass rate as 98% to 100%, which is provided and tested by our worthy customers, you will be encouraged to overcome the lack of confidence and establish your determination to pass MLA-C01 exam.
Free MLA-C01 Test Questions: https://www.prep4pass.com/MLA-C01_exam-braindumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=1iQ6rJjq-BjIZddTVxkVpt1Nsqmrq7RQN