DOWNLOAD the newest PrepPDF Databricks-Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Qx4YRRsYv6-pGRlboKbYFkEKfXEzpVJW
We are determined to be the best vendor in this career to help more and more candidates to acomplish their dream and get their desired Databricks-Certified-Data-Engineer-Professional certification. No only that we provide the most effective Databricks-Certified-Data-Engineer-Professional study materials, but also we offer the first-class after-sale service to all our customers.Our professional online service are pleased to give guide in 24 hours. If you have any question on our Databricks-Certified-Data-Engineer-Professional learning quiz, just contact us!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Governance | 7% | - Manage data assets and metadata - Enforce data policies and standards - Use Unity Catalog for governance |
| Topic 2: Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices |
| Topic 3: Data Modelling | 6% | - Optimize table design and partitioning - Design Medallion Architecture - Implement dimensional and relational models |
| Topic 4: Cost & Performance Optimisation | 13% | - Apply cost management best practices - Improve query and pipeline performance - Optimize compute and storage resources |
| Topic 5: Monitoring and Alerting | 10% | - Track data lineage and metrics - Monitor pipeline performance and health - Set up alerts and notifications |
| Topic 6: Data Sharing and Federation | 5% | - Implement Lakehouse Federation - Use Delta Sharing for secure data sharing - Manage cross-platform data access |
| Topic 7: Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs - Write efficient and maintainable code - Implement complex data processing logic |
| Topic 8: Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules - Enforce data quality standards - Implement schema evolution and management |
| Topic 9: Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming - Handle incremental and batch data loads - Ingest data from diverse sources |
| Topic 10: Ensuring Data Security and Compliance | 10% | - Implement access control and permissions - Ensure data privacy and compliance - Secure data at rest and in transit |
>> Reliable Databricks-Certified-Data-Engineer-Professional Test Questions <<
To advance your career, take the Databricks Certified Data Engineer Professional Exam exam. Your Databricks demonstrates your commitment to lifelong learning. Passing the Databricks Certified Data Engineer Professional Exam exam in one sitting is not a walk in the park. The Databricks Databricks-Certified-Data-Engineer-Professional exam preparation process takes a lot of time and effort. You have to put time and money into passing the Databricks Certified Data Engineer Professional Exam exam. The best method to reap the rewards of your investment in becoming an expert is by using Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions. Additionally, you can confidently study for the Databricks-Certified-Data-Engineer-Professional exam.Passing an Databricks Certified Data Engineer Professional Exam exam on the first attempt can be stressful, but Databricks Databricks-Certified-Data-Engineer-Professional exam questions can help manage stress and allow you to perform at your best.
NEW QUESTION # 100
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.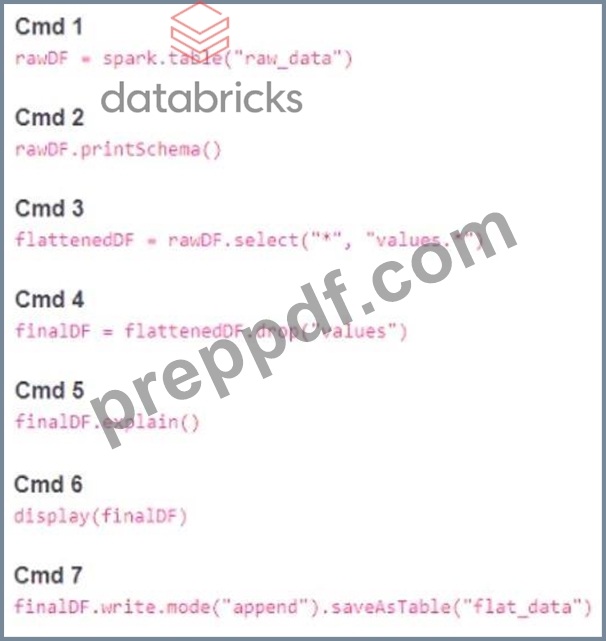
Which command should be removed from the notebook before scheduling it as a job?
Answer: A
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 101
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: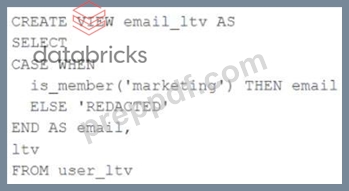
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
Answer: A
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
NEW QUESTION # 102
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
Answer: C
Explanation:
Repartitioning the DataFrame by the grouping key ensures that records with the same region are colocated in the same partitions before the aggregation runs. This significantly reduces the amount of data shuffled during the groupBy operation, leading to more efficient execution.
NEW QUESTION # 103
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity.
Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
Answer: C
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
NEW QUESTION # 104
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline. Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
Answer: A
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
NEW QUESTION # 105
......
With Databricks-Certified-Data-Engineer-Professional study tool, you are not like the students who use other materials. As long as the syllabus has changed, they need to repurchase learning materials. This not only wastes a lot of money, but also wastes a lot of time. Our industry experts are constantly adding new content to Databricks-Certified-Data-Engineer-Professional Exam Torrent based on constantly changing syllabus and industry development breakthroughs. We also hire dedicated staff to continuously update our question bank daily, so no matter when you buy Databricks-Certified-Data-Engineer-Professional guide torrent, what you learn is the most advanced.
Vce Databricks-Certified-Data-Engineer-Professional File: https://www.preppdf.com/Databricks/Databricks-Certified-Data-Engineer-Professional-prepaway-exam-dumps.html
BONUS!!! Download part of PrepPDF Databricks-Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1Qx4YRRsYv6-pGRlboKbYFkEKfXEzpVJW