Certified-Data-Engineer-Professional exams questions and answers & dumps PDF for Databricks Certified Data Engineer Professional

After you purchase our Certified-Data-Engineer-Professional study materials, we will provide one-year free update for you. Within one year, we will send the latest version to your mailbox with no charge if we have a new version of Certified-Data-Engineer-Professional learning materials. We will also provide some discount for your updating after a year if you are satisfied with our Certified-Data-Engineer-Professional Exam Questions. And if you find that your version of the Certified-Data-Engineer-Professional practice guide is over one year, you can enjoy 50% discount if you buy it again.
| Section | Objectives |
|---|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
>> Dumps Certified-Data-Engineer-Professional Torrent <<
Valid Certified-Data-Engineer-Professional Exam Camp Pdf, Latest Certified-Data-Engineer-Professional Dumps Questions
For candidates who are going to buy Certified-Data-Engineer-Professional exam torrent online, you may pay much attention to the privacy protection. We respect the private information of you, if you choose us for your Certified-Data-Engineer-Professional exam materials, your personal information will be protected well. Once the order finishes, your personal information such as your name and email address will be concealed. In addition, we have a professional team to research the professional knowledge for Certified-Data-Engineer-Professional Exam Materials, and you can get the latest information timely. Free update for one year is available, and the update version for Certified-Data-Engineer-Professional training material will be sent to your email automatically.
Databricks Certified Data Engineer Professional Sample Questions (Q187-Q192):
NEW QUESTION # 187
A data team is automating a daily multi-task ETL pipeline in Databricks. The pipeline includes a notebook for ingesting raw data, a Python wheel task for data transformation, and a SQL query to update aggregates. They want to trigger the pipeline programmatically and see previous runs in the GUI. They need to ensure tasks are retried on failure and stakeholders are notified by email if any task fails. Which two approaches will meet these requirements? (Choose two.)
- A. Create a single orchestrator notebook that calls each step with dbutils.notebook.run(), defining a job for that notebook and configuring retries and notifications at the notebook level.
- B. Create a multi-task job using the UI, Databricks Asset Bundles (DABs), or the Jobs REST API (/jobs/create) with notebook, Python wheel, and SQL tasks. Configure task-level retries and email notifications in the job definition.
- C. Use the REST API endpoint /jobs/runs/submit to trigger each task individually as separate job runs and implement retries using custom logic in the orchestrator.
- D. Trigger the job programmatically using the Databricks Jobs REST API (/jobs/run-now), the CLI (databricks jobs run-now), or one of the Databricks SDKs.
- E. Use Databricks Asset Bundles (DABs) to deploy the workflow, then trigger individual tasks directly by referencing each task's notebook or script path in the workspace.
Answer: B,D
Explanation:
Databricks Jobs supports defining multi-task workflows that include notebooks, SQL statements, and Python wheel tasks. These can be configured with retry policies, dependency chains, and failure notifications. The correct practice, as stated in the documentation, is to use the Jobs REST API (/jobs/create) or Databricks Asset Bundles to define multi-task jobs, and then trigger them programmatically using /jobs/run-now, CLI, or SDK. This allows the team to maintain full job history, handle retries automatically, and receive alerts via configured email notifications. Using
/jobs/runs/submit creates one-off ad hoc runs without maintaining dependency visibility.
Therefore, options B and C together satisfy the operational, automation, and governance requirements.
NEW QUESTION # 188
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- B. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- C. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- D. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- E. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
Answer: A
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 189
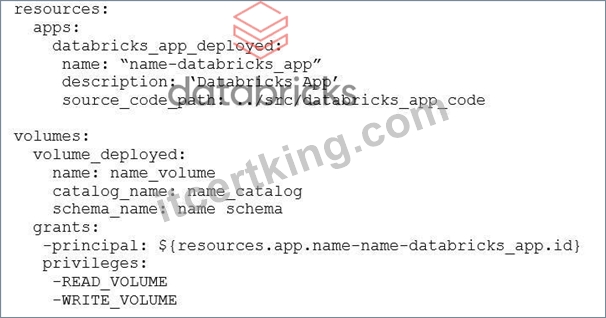
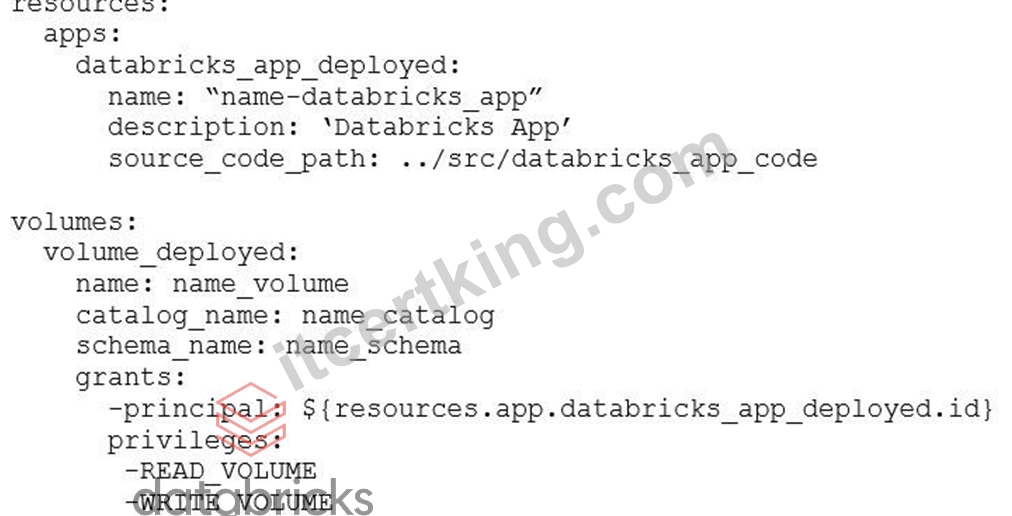
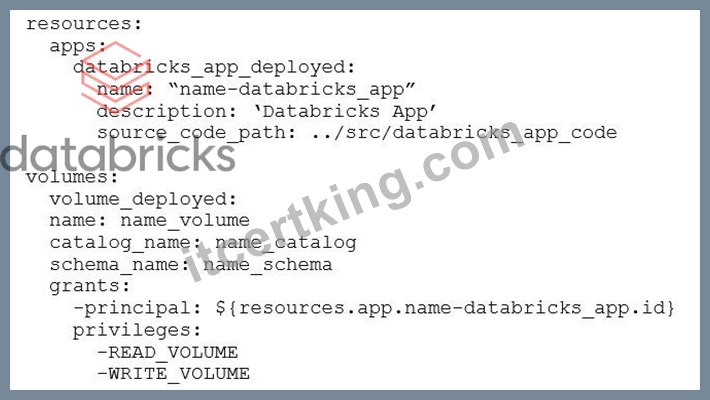
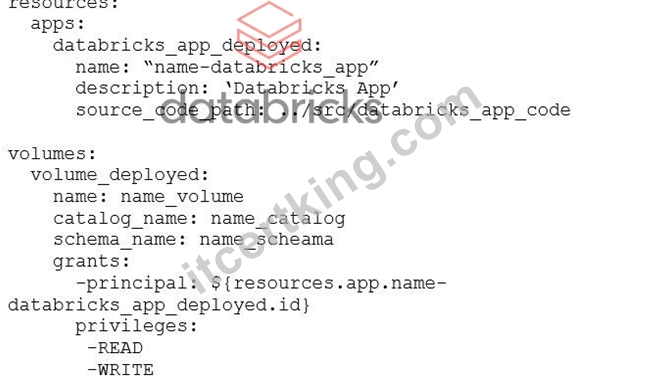
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Answer: B
Explanation:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
NEW QUESTION # 190
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
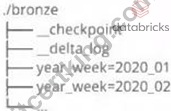
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
- A. No; each of the streams needs to have its own checkpoint directory.
- B. No; only one stream can write to a Delta Lake table.
- C. Yes; Delta Lake supports infinite concurrent writers.
- D. Yes; both of the streams can share a single checkpoint directory.
- E. No; Delta Lake manages streaming checkpoints in the transaction log.
Answer: A
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 191
When a new Databricks project starts, the central IP team provisions the required infrastructure using Terraform and a Service Principal. This includes creating a Databricks workspace, a Unity Catalog linked to an External Location, and a Databricks group containing all project team members. Project teams must store all assets - e.g., tables and volumes, as Managed assets in Unity Catalog. This model hides infrastructure complexity while giving teams autonomy within their catalog. They can create and manage schemas, tables, volumes, and related objects but cannot rename, delete, or change catalog permissions, those remain under IT's control. Which rights should the project group be granted to enable this model?
- A. The group needs to have ALL PRIVILEGES and the MANAGE on the catalog.
- B. The group needs to have USE CATALOG and USE SCHEMA on the catalog.
- C. The group needs to have ALL PRIVILEGES on the catalog.
- D. The group should be made OWNER of the catalog.
Answer: B
Explanation:
Granting the project group USE CATALOG (and USE SCHEMA on existing schemas) allows team members to work within the catalog without giving them ownership or administrative control.
This enables teams to create and manage schemas, tables, and volumes inside the catalog while preventing them from renaming, deleting, or modifying catalog-level permissions, which remain under central IT governance.
NEW QUESTION # 192
......
We have the Certified-Data-Engineer-Professional Questions and answers with high accuracy and timely update. Our professional team checks Certified-Data-Engineer-Professional answers and questions carefully with their professional knowledge. We also have the latest information about the exam center, and will update the version according to the new requirements. Pass guarantee and money back guarantee are also our principles, and if you have any questions, you can also consult the service stuff.
Valid Certified-Data-Engineer-Professional Exam Camp Pdf: https://www.itcertking.com/Certified-Data-Engineer-Professional_exam.html
- Certified-Data-Engineer-Professional Braindump Pdf 🎍 Exam Certified-Data-Engineer-Professional Overviews 👧 Vce Certified-Data-Engineer-Professional Torrent 🐗 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free immediately on ➽ www.pdfdumps.com 🢪 😐Brain Certified-Data-Engineer-Professional Exam
- Certified-Data-Engineer-Professional Vce Download 🌑 Certified-Data-Engineer-Professional Braindump Pdf 😩 Vce Certified-Data-Engineer-Professional Torrent ✈ Download 【 Certified-Data-Engineer-Professional 】 for free by simply entering ⇛ www.pdfvce.com ⇚ website ⚔Certified-Data-Engineer-Professional Vce Download
- Free PDF Databricks - Certified-Data-Engineer-Professional Pass-Sure Dumps Torrent 🤢 Easily obtain free download of { Certified-Data-Engineer-Professional } by searching on ⇛ www.pdfdumps.com ⇚ 👡Vce Certified-Data-Engineer-Professional Torrent
- 100% Pass 2026 Databricks Certified-Data-Engineer-Professional: Updated Dumps Databricks Certified Data Engineer Professional Torrent 🪒 「 www.pdfvce.com 」 is best website to obtain ( Certified-Data-Engineer-Professional ) for free download 🛸Certified-Data-Engineer-Professional Braindump Pdf
- Answers Certified-Data-Engineer-Professional Free 💋 Exam Certified-Data-Engineer-Professional Overviews 🔢 Detailed Certified-Data-Engineer-Professional Study Dumps 😻 Search on ➡ www.examcollectionpass.com ️⬅️ for ✔ Certified-Data-Engineer-Professional ️✔️ to obtain exam materials for free download 📷Certified-Data-Engineer-Professional Exam Preparation
- Free PDF Quiz Databricks - Fantastic Dumps Certified-Data-Engineer-Professional Torrent 🔆 Copy URL { www.pdfvce.com } open and search for ( Certified-Data-Engineer-Professional ) to download for free 🧏Certified-Data-Engineer-Professional Test Lab Questions
- Free PDF Useful Certified-Data-Engineer-Professional - Dumps Databricks Certified Data Engineer Professional Torrent 🍍 Open ▷ www.dumpsmaterials.com ◁ and search for “ Certified-Data-Engineer-Professional ” to download exam materials for free 🛺Certified-Data-Engineer-Professional Exams Collection
- Certified-Data-Engineer-Professional Braindump Pdf 🚮 Certified-Data-Engineer-Professional Test Certification Cost 📸 Answers Certified-Data-Engineer-Professional Free 🍴 Immediately open ⇛ www.pdfvce.com ⇚ and search for { Certified-Data-Engineer-Professional } to obtain a free download 🐘Certified-Data-Engineer-Professional Dumps Free
- Reliable Certified-Data-Engineer-Professional Exam Camp 🏘 Exam Certified-Data-Engineer-Professional Overviews 🍄 Detailed Certified-Data-Engineer-Professional Study Dumps 🚋 The page for free download of ⏩ Certified-Data-Engineer-Professional ⏪ on [ www.exam4labs.com ] will open immediately 🥫Certified-Data-Engineer-Professional Test Lab Questions
- 100% Pass 2026 Databricks Certified-Data-Engineer-Professional: Updated Dumps Databricks Certified Data Engineer Professional Torrent 🎇 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply searching on ( www.pdfvce.com ) 🐂Detailed Certified-Data-Engineer-Professional Study Dumps
- Test Certified-Data-Engineer-Professional Collection Pdf 🌗 Vce Certified-Data-Engineer-Professional Torrent 🍾 Valid Braindumps Certified-Data-Engineer-Professional Free 🛷 Copy URL { www.vceengine.com } open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free ⚪Certified-Data-Engineer-Professional Test Lab Questions
- www.stes.tyc.edu.tw, www.flirtic.com, www.stes.tyc.edu.tw, forums.filatelija.lv, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes