DP-700最新試題 - DP-700測試題庫

順便提一下,可以從雲存儲中下載NewDumps DP-700考試題庫的完整版:https://drive.google.com/open?id=1pcED2RdDU46XVf-UptT19Gzf198b6sW-
如果你覺得你購買NewDumps Microsoft的DP-700考試培訓資料利用它來準備考試是一場冒險,那麼整個生命就是一場冒險,走得最遠的人常常就是願意去做願意去冒險的人。更何況NewDumps Microsoft的DP-700考試培訓資料是由眾多考生用實踐證明了,它帶給每位考生的成功也是真實有效的,成功有夢想和希望固然重要,但更重要的是去實踐和證明,NewDumps Microsoft的DP-700考試培訓資料是被證明一定會成功的,選擇了它,你還有什麼理由不成功呢!
Microsoft DP-700 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Ingest and transform data | 30–35% | - Design and implement data loading patterns
- 1. Design streaming data loading patterns
- 2. Prepare data for dimensional models
- 3. Design full and incremental data loads
- Transform data
- 1. Transform data using SQL
- 2. Clean, denormalize, and aggregate data
- 3. Transform data using KQL
- 4. Transform data using PySpark
- Ingest data
- 1. Ingest data using Eventstreams
- 2. Ingest data using pipelines
- 3. Ingest data using Dataflows Gen2
- Orchestrate data operations
- 1. Implement schedules and triggers
- 2. Orchestrate with notebooks and pipelines
- 3. Use parameters and dynamic expressions
|
| Topic 2: Monitor and optimize an analytics solution | 30–35% | - Troubleshoot issues
- 1. Identify and resolve notebook and Spark errors
- 2. Identify and resolve storage and query errors
- 3. Identify and resolve Dataflow errors
- 4. Identify and resolve pipeline errors
- Optimize performance
- 1. Optimize Lakehouse and data warehouse performance
- 2. Optimize Spark and query performance
- 3. Optimize storage efficiency
- 4. Optimize pipelines and data flows
- Monitor analytics solutions
- 1. Monitor semantic model refreshes
- 2. Monitor Fabric items and activities
- 3. Monitor data ingestion and transformation
- 4. Configure alerts and notifications
|
| Topic 3: Implement and manage an analytics solution | 30–35% | - Manage data storage
- 1. Implement data mirroring
- 2. Choose appropriate data stores
- 3. Create and manage OneLake shortcuts
- Manage data lifecycle and governance
- 1. Implement data retention and archiving
- 2. Manage data access and security
- 3. Implement data governance with Microsoft Purview
- Configure workspace settings
- 1. Configure Spark workspace settings
- 2. Configure Microsoft Fabric workspace settings
- 3. Configure Dataflows Gen2 settings
- 4. Configure OneLake workspace settings
- 5. Configure domain workspace settings
|
>> DP-700最新試題 <<
最佳DP-700最新試題和資格考試領先提供商和免費下載的DP-700:Implementing Data Engineering Solutions Using Microsoft Fabric
我們承諾,使用我們NewDumps Microsoft的DP-700的考試培訓資料,確保你在你的第一次嘗試中通過測試,如果你準備考試使用我們NewDumps Microsoft的DP-700考試培訓資料,我們保證你通過,如果沒有通過測試,我們給你退還購買的全額退款,送你一個相同價值的免費產品。
最新的 Microsoft Certified: Fabric Data Engineer Associate DP-700 免費考試真題 (Q24-Q29):
問題 #24
You have a Fabric workspace named Workspace1 that contains a data pipeline named Pipeline1 and a lakehouse named Lakehouse1.
You have a deployment pipeline named deployPipeline1 that deploys Workspace1 to Workspace2.
You restructure Workspace1 by adding a folder named Folder1 and moving Pipeline1 to Folder1.
You use deployPipeline1 to deploy Workspace1 to Workspace2.
What occurs to Workspace2?
- A. Folder1 is created, and Pipeline1 and Lakehouse1 move to Folder1.
- B. Folder1 is created, Pipeline1 moves to Folder1, and Lakehouse1 is deployed.
- C. Only Folder1 is created and Pipeline1 moves to Folder1.
- D. Only Pipeline1 and Lakehouse1 are deployed.
答案:B
解題說明:
When you restructure Workspace1 by adding a new folder (Folder1) and moving Pipeline1 into it, deployPipeline1 will deploy the entire structure of Workspace1 to Workspace2, preserving the changes made in Workspace1. This includes:
Folder1 will be created in Workspace2, mirroring the structure in Workspace1.
Pipeline1 will be moved into Folder1 in Workspace2, maintaining the same folder structure.
Lakehouse1 will be deployed to Workspace2 as it exists in Workspace1.
問題 #25
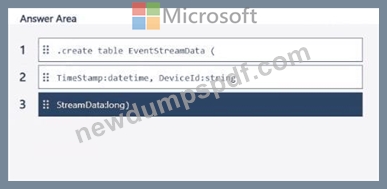
You have a Fabric workspace that contains an eventhouse named Eventhouse1.
In Eventhouse1, you plan to create a table named DeviceStreamData in a KQL database. The table will contain data based on the following sample.
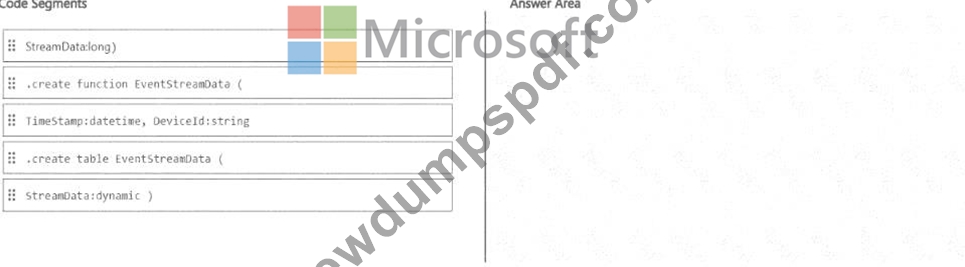
答案:
解題說明:
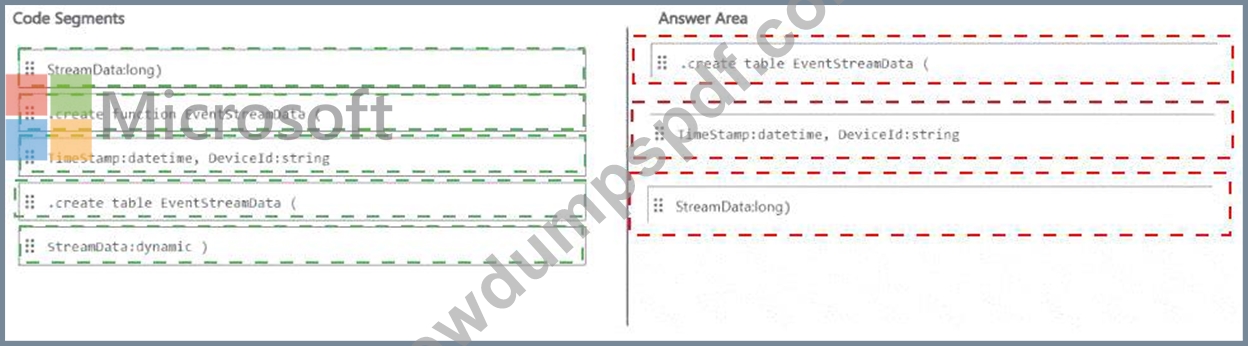
Explanation:
問題 #26
You are developing a data pipeline named Pipeline1.
You need to add a Copy data activity that will copy data from a Snowflake data source to a Fabric warehouse.
What should you configure?
- A. Enable staging
- B. Fault tolerance
- C. Degree of copy parallelism
- D. Enable logging
答案:A
解題說明:
When using the Copy data activity in a data pipeline to move data from Snowflake to a Fabric warehouse, the process often involves intermediate staging to handle data efficiently, especially for large datasets or cross-cloud data transfers.
Staging involves temporarily storing data in an intermediate location (e.g., Blob storage or Azure Data Lake) before loading it into the target destination.
For cross-cloud data transfers (e.g., from Snowflake to Fabric), enabling staging ensures data is processed and stored temporarily in an efficient format for transfer.
Staging is especially useful when dealing with large datasets, ensuring the process is optimized and avoids memory limitations.
問題 #27
You have a Fabric warehouse named DW1 that contains four staging tables named ProductCategory, ProductSubcategory, Product, and SalesOrder. ProductCategory, ProductSubcategory, and Product are used often in analytical queries.
You need to implement a star schema for DW1. The solution must minimize development effort.
Which design approach should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
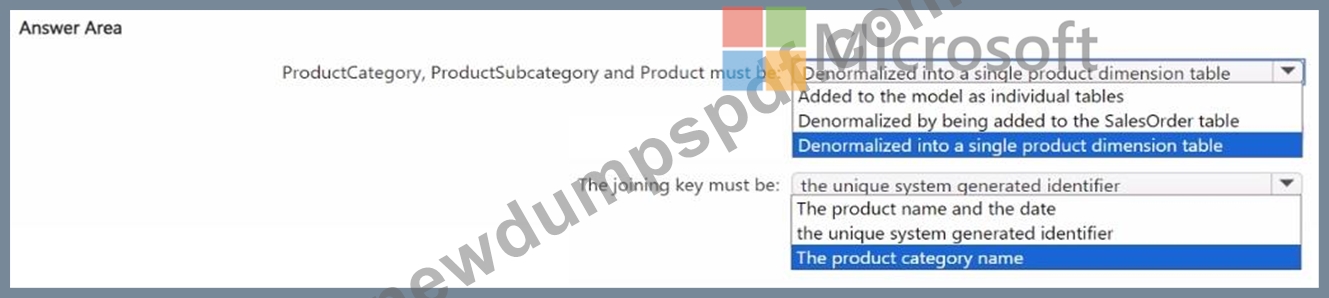
答案:
解題說明:
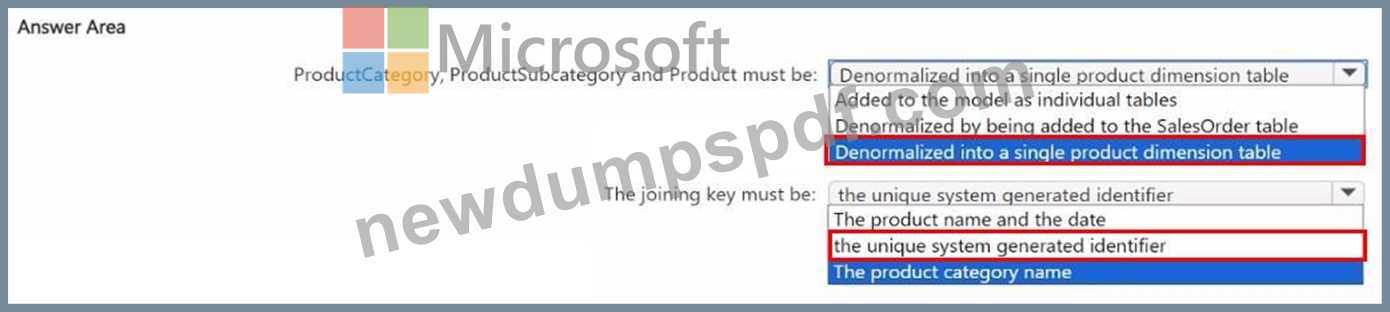
問題 #28
You need to populate the MAR1 data in the bronze layer.
Which two types of activities should you include in the pipeline? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
- A. Copy data
- B. WebHook
- C. ForEach
- D. Stored procedure
答案:A,C
解題說明:
MAR1 has seven entities, each accessible via a different API endpoint. A ForEach activity is required to iterate over these endpoints to fetch data from each one. It enables dynamic execution of API calls for each entity.
The Copy data activity is the primary mechanism to extract data from REST APIs and load it into the bronze layer in Delta format. It supports native connectors for REST APIs and Delta, minimizing development effort.
問題 #29
......
競爭頗似打網球,與球藝勝過你的對手比賽,可以提高你的水準。你可以選擇參加最近很有人氣的 Microsoft 的 DP-700 認證考試。得到這個考試的認證資格,你可以得到很大的好處。如果你要參加 DP-700 認證考試,Microsoft 的 DP-700 考古題是你最好的準備工具。這個資料可以幫助你輕鬆地通過考試。這是一個評價很高的資料,有了它,你就不用再擔心你的考試了。
DP-700測試題庫: https://www.newdumpspdf.com/DP-700-exam-new-dumps.html
- 專業DP-700最新試題及資格考試領先供應商和免費下載的Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric 🌿 ( tw.fast2test.com )網站搜索⮆ DP-700 ⮄並免費下載DP-700熱門證照
- DP-700證照資訊 🥠 DP-700考試證照 🧾 DP-700考題寶典 📯 透過⏩ www.newdumpspdf.com ⏪輕鬆獲取☀ DP-700 ️☀️免費下載DP-700權威認證
- 更新的DP-700最新試題 |高通過率的考試材料|全面覆蓋的DP-700:Implementing Data Engineering Solutions Using Microsoft Fabric 🏪 免費下載⮆ DP-700 ⮄只需進入【 www.pdfexamdumps.com 】網站最新DP-700題庫
- DP-700認證題庫 🧯 DP-700 PDF 🦨 DP-700測試引擎 🐣 進入{ www.newdumpspdf.com }搜尋▷ DP-700 ◁免費下載DP-700最新題庫
- 更新的DP-700最新試題 |高通過率的考試材料|全面覆蓋的DP-700:Implementing Data Engineering Solutions Using Microsoft Fabric 🪑 《 www.kaoguti.com 》上的免費下載⏩ DP-700 ⏪頁面立即打開DP-700考試題庫
- DP-700最新題庫 🎍 DP-700權威認證 🔛 DP-700 PDF 💻 在“ www.newdumpspdf.com ”上搜索➠ DP-700 🠰並獲取免費下載DP-700題庫資料
- DP-700測試引擎 💉 DP-700權威認證 🕊 DP-700證照資訊 🏰 ⏩ tw.fast2test.com ⏪提供免費( DP-700 )問題收集DP-700考試資料
- DP-700考題免費下載 🛕 DP-700考題寶典 🕙 DP-700熱門證照 🕌 ⏩ www.newdumpspdf.com ⏪上搜索➽ DP-700 🢪輕鬆獲取免費下載DP-700測試引擎
- DP-700測試引擎 👈 最新DP-700考古題 🐥 DP-700更新 📨 ➤ www.newdumpspdf.com ⮘上的【 DP-700 】免費下載只需搜尋DP-700證照資訊
- DP-700考題免費下載 👇 DP-700認證題庫 ⚠ DP-700下載 🕜 透過▛ www.newdumpspdf.com ▟輕鬆獲取( DP-700 )免費下載DP-700題庫更新
- 更新的DP-700最新試題 |高通過率的考試材料|全面覆蓋的DP-700:Implementing Data Engineering Solutions Using Microsoft Fabric 📻 《 www.newdumpspdf.com 》最新⏩ DP-700 ⏪問題集合DP-700更新
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! 免費下載NewDumps DP-700考試題庫的完整版:https://drive.google.com/open?id=1pcED2RdDU46XVf-UptT19Gzf198b6sW-