New Certified-Data-Engineer-Professional Dumps Questions | New Certified-Data-Engineer-Professional Study Materials

We truly treat our customers with the best quality service and the most comprehensive Certified-Data-Engineer-Professional exam pdf, that's why we enjoy great popularity among most IT workers. When you want to learn something about the Certified-Data-Engineer-Professional Online Training, our customer assisting will be available for you. We will offer you the best preparation materials regarding Certified-Data-Engineer-Professional practice exam. You can totally trust our dumps and service.
| Section | Objectives |
|---|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
>> New Certified-Data-Engineer-Professional Dumps Questions <<
Save Money and Time with EduDump Databricks Certified-Data-Engineer-Professional Exam Questions
We provide a wide range of learning and preparation methodologies to the customers for the Databricks Certified-Data-Engineer-Professional complete training. After using the Databricks Certified-Data-Engineer-Professional exam materials, success would surely be the fate of customer because, self-evaluation, highlight of the mistakes, time management and sample question answers in comprehensive manner, are all the tools which are combined to provide best possible results. Certified-Data-Engineer-Professional Exam Materials are also offering 100% money back guarantee to the customers in case they don't achieve passing scores in the Certified-Data-Engineer-Professional exam in the first attempt.
Databricks Certified Data Engineer Professional Sample Questions (Q94-Q99):
NEW QUESTION # 94
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
- A. Account Admin, because account admins can only create metastores but cannot change ownership of catalogs.
- B. Metastore Admin, because metastore admins can transfer ownership and manage privileges across all metastore objects, including shares and recipients.
- C. Catalog Owner, because catalog owners can transfer any object in any catalog in the metastore.
- D. Workspace Admin, because workspace admins can transfer ownership of any Unity Catalog object.
Answer: B
Explanation:
Metastore Admins have the highest administrative privileges within a Unity Catalog metastore.
They can transfer ownership of any Unity Catalog object, including catalogs, schemas, tables, storage credentials, and external locations. Metastore Admins are also required to manage Delta Sharing configurations such as creating or transferring shares and recipients.
Account Admins, by contrast, only create metastores and cannot change ownership or manage Delta Sharing objects. Workspace Admins have privileges limited to workspace-level management, not cross-metastore access.
NEW QUESTION # 95
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
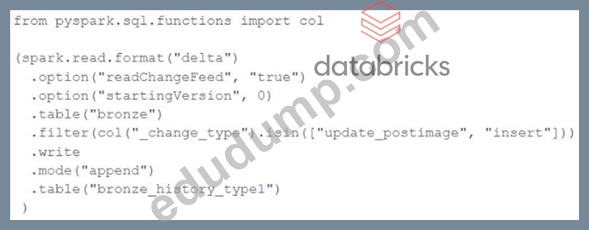
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- B. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- C. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- D. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- E. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
Answer: C
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 96
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control.
The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity. Which SQL query should the team run from the System catalog to achieve this?
- A. SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10 - B. SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - C. SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - D. SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
Answer: A
Explanation:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non- existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 97
A data engineer is masking a column containing email addresses. The goal is to produce output strings of identical length for all rows, while generating different outputs for different email values.
Which SQL function should be used to achieve this?
- A. hash(email)
- B. sha2(email, 0)
- C. sha1(email)
- D. mask(email, '?')
Answer: A
Explanation:
The hash() function in Databricks SQL returns a deterministic fixed-length integer (or hexadecimal string) derived from the input. When applied to sensitive identifiers like email addresses, it produces a unique value for each distinct input while ensuring uniform output size, making it suitable for anonymization where referential consistency is required.
Functions like mask() perform pattern-based substitutions that change string lengths, and sha1() or sha2() produce long hexadecimal strings of varying lengths (depending on hash size), which may not match requirements for fixed-length masking.
Therefore, the correct choice for fixed-length, deterministic pseudonymization of email addresses is hash(email), as it maintains analytical usability while anonymizing sensitive data.
NEW QUESTION # 98
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline. Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- B. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
- C. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- D. Stop the existing pipeline; use the returned settings in a reset command
Answer: C
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
NEW QUESTION # 99
......
The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) study material of EduDump is available in three different and easy-to-access formats. The first one is printable and portable Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) PDF format. With the PDF version, you can access the collection of actual Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) questions with your smart devices like smartphones, tablets, and laptops. You can even print the study material and save it in your smart devices to study anywhere and pass the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam.
New Certified-Data-Engineer-Professional Study Materials: https://www.edudump.com/exams/Databricks/Certified-Data-Engineer-Professional/
- Certified-Data-Engineer-Professional Latest Test Simulations 🙆 Certified-Data-Engineer-Professional Top Questions 🚴 Certified-Data-Engineer-Professional Top Questions 🧹 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free on ☀ www.practicevce.com ️☀️ website 🕑100% Certified-Data-Engineer-Professional Exam Coverage
- Certified-Data-Engineer-Professional Latest Exam Price 🎤 Hottest Certified-Data-Engineer-Professional Certification 🐊 Certified-Data-Engineer-Professional Latest Test Simulations 🧒 Easily obtain ⏩ Certified-Data-Engineer-Professional ⏪ for free download through ➥ www.pdfvce.com 🡄 🤪Certified-Data-Engineer-Professional Exam Passing Score
- Certified-Data-Engineer-Professional Vce Test Simulator 🐪 New Certified-Data-Engineer-Professional Exam Camp 👟 Certified-Data-Engineer-Professional Exam Online ⚜ Download 【 Certified-Data-Engineer-Professional 】 for free by simply entering [ www.troytecdumps.com ] website ◀Certified-Data-Engineer-Professional Cheap Dumps
- Certified-Data-Engineer-Professional Latest Dumps Free 💕 Valid Certified-Data-Engineer-Professional Exam Materials 🎸 Exam Certified-Data-Engineer-Professional Braindumps 😺 Simply search for ✔ Certified-Data-Engineer-Professional ️✔️ for free download on ✔ www.pdfvce.com ️✔️ 🏐Certified-Data-Engineer-Professional Exam Flashcards
- Databricks - High Hit-Rate New Certified-Data-Engineer-Professional Dumps Questions 🍒 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free on ➥ www.troytecdumps.com 🡄 website 📚New Certified-Data-Engineer-Professional Exam Camp
- Databricks Certified-Data-Engineer-Professional Exam Questions Come With Free 12 Months Updates 🦨 Easily obtain free download of 《 Certified-Data-Engineer-Professional 》 by searching on 《 www.pdfvce.com 》 ✋Certified-Data-Engineer-Professional Latest Exam Price
- Valid Certified-Data-Engineer-Professional Exam Materials ⏺ Certified-Data-Engineer-Professional Latest Dumps Pdf 🆔 Certified-Data-Engineer-Professional Free Exam Questions 🦛 Easily obtain free download of ▛ Certified-Data-Engineer-Professional ▟ by searching on ( www.pass4test.com ) 🏊Certified-Data-Engineer-Professional Free Exam Questions
- Databricks - Accurate Certified-Data-Engineer-Professional - New Databricks Certified Data Engineer Professional Dumps Questions 🚹 Simply search for 《 Certified-Data-Engineer-Professional 》 for free download on ▶ www.pdfvce.com ◀ 🎠Certified-Data-Engineer-Professional Latest Test Simulations
- Databricks Certified-Data-Engineer-Professional Dumps - A Way To Prepare Quickly For Exam 🕌 Open “ www.troytecdumps.com ” and search for ➥ Certified-Data-Engineer-Professional 🡄 to download exam materials for free 🔯100% Certified-Data-Engineer-Professional Exam Coverage
- Crack Databricks Certified-Data-Engineer-Professional Certification Exam Without Any Hassle 🌌 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on 【 www.pdfvce.com 】 🐁Certified-Data-Engineer-Professional Exam Passing Score
- Multiple Benefits Upon Buying Databricks Certified-Data-Engineer-Professional Exam Dumps 🤒 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download it for free immediately on ⮆ www.testkingpass.com ⮄ 📩Certified-Data-Engineer-Professional New Test Camp
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes