If someone who can pass the exam, they can earn a high salary in a short time. If you decide to beat the exam, you must try our AI-200 exam torrent, then, you will find that it is so easy to pass the exam. You only need little time and energy to review and prepare for the exam if you use our AI-200 prep torrent as the studying materials. So it is worthy for them to buy our AI-200 learning prep. We provide the free demo of our AI-200 training guide so as to let you have a good understanding of our AI-200 exam questions before your purchase.
| Section | Objectives |
|---|---|
| Topic 1: Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search |
| Topic 2: Plan and manage Azure AI solutions | - Plan security and compliance requirements - Select appropriate Azure AI services - Monitor and optimize AI solutions |
| Topic 3: Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
An updated Microsoft AI-200 study material is essential for the best preparation for the Microsoft AI-200 exam and subsequently passing the Microsoft AI-200 test. Students may find study resources on many websites, but they are likely to be outdated. Lead2PassExam resolved this issue by providing updated and real AI-200 PDF Questions.
NEW QUESTION # 81
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.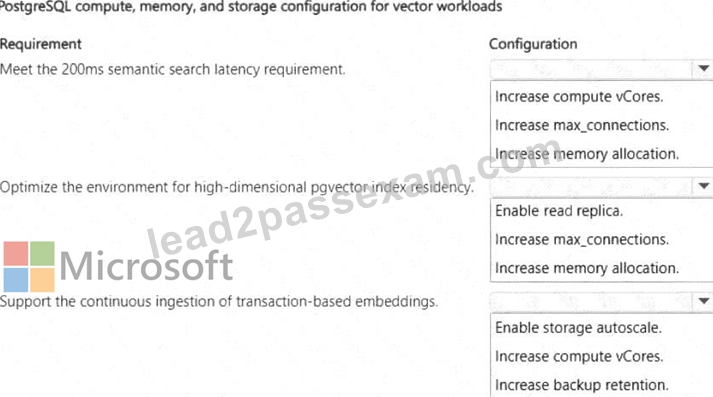
Answer:
Explanation: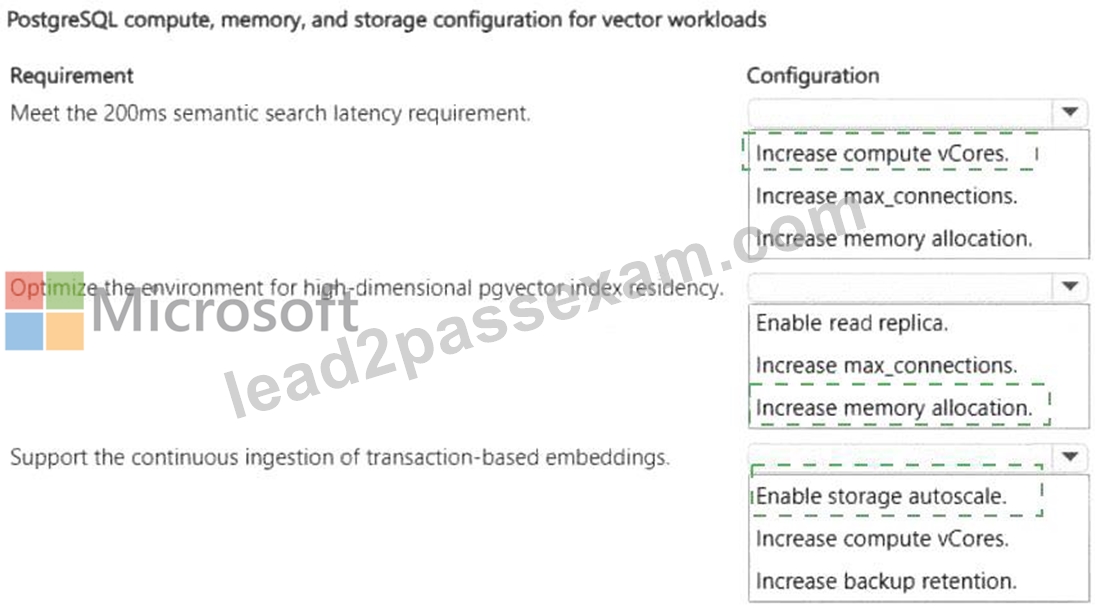
Explanation:
* Meet the 200-ms semantic search latency requirement: Increase compute vCores.
* Optimize the environment for high-dimensional pgvector index residency: Increase memory allocation.
* Support the continuous ingestion of transaction-based embeddings: Enable storage autoscale.
For the strict sub-200-ms vector-search latency target, increasing compute vCores is the appropriate choice.
Vector similarity operations are computationally intensive, and additional CPU capacity improves mathematical throughput and parallel query execution. Microsoft's pgvector guidance emphasizes query-plan optimization, ANN indexes such as HNSW, and sufficient compute resources when optimizing vector workloads.
For high-dimensional pgvector index residency , increase memory allocation . HNSW provides strong query-performance characteristics but consumes more memory than IVFFlat. Keeping frequently accessed vector index structures in memory minimizes disk access and materially improves latency. Microsoft explicitly notes that HNSW requires more memory while providing a better speed/recall tradeoff.
For the continuous ingestion of millions of embeddings, enable storage autoscale . Azure Database for PostgreSQL Flexible Server can automatically increase allocated storage as capacity approaches configured thresholds, avoiding an out-of-storage condition as data volumes grow. Microsoft recommends storage autogrow for workloads whose storage demand can increase dynamically.
Increasing max_connections does not directly improve vector computation or index residency, read replicas primarily scale reads, and backup retention does not address ingestion capacity.
Study Guide references: Azure Database for PostgreSQL Flexible Server # pgvector performance optimization; compute and memory sizing; HNSW indexing; storage autogrow.
NEW QUESTION # 82
You are reviewing an Azure Function app that processes incoming order requests for a company. The function must:
* Accept order submissions from an external client application.
* Require controlled access for security
* Return a response containing the processed request payload.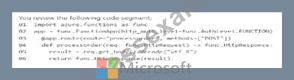
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.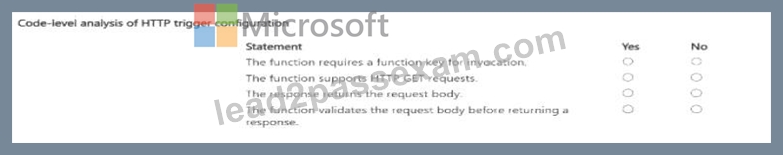
Answer:
Explanation:
Explanation: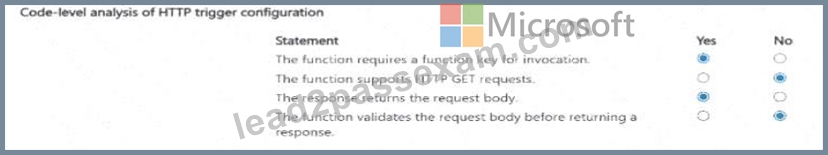
Verified Answer: Yes; No; Yes; No.
Detailed Explanation: `auth_level=FUNCTION` means invocation requires a function key unless a stronger platform authentication layer is configured, so the first statement is true. The route explicitly permits POST, not GET. The function reads `req.get_body()` and returns that value in the HttpResponse, so the response contains the request body. No schema, type, required-field, or other payload validation is performed before the response is constructed, making the final statement false.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Azure Functions HTTP trigger
NEW QUESTION # 83
You have a newly provisioned Azure subscription. You are designing a custom Event Grid workflow for AI inference events.
You need to implement the Event Grid components to support routing of high-confidence events to a downstream processor.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.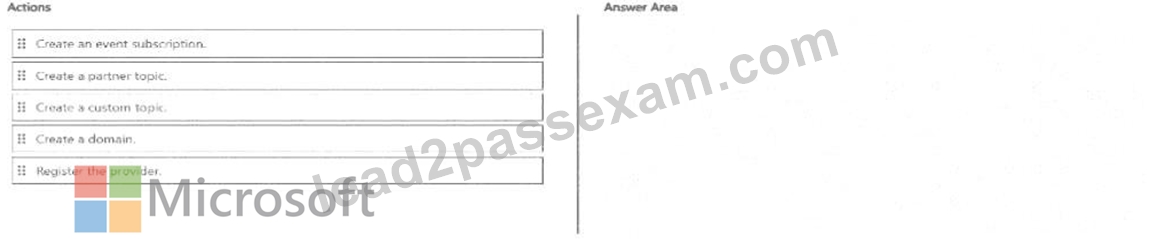
Answer:
Explanation: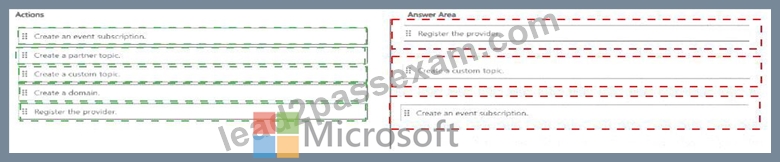
Explanation: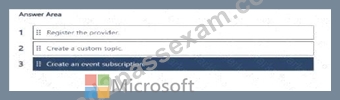
Verified answer: 1) Register the Event Grid resource provider; 2) create a custom topic; 3) create an event subscription.
Detailed Explanation: A newly provisioned subscription must have the Event Grid resource provider available before Event Grid resources can be created. The publisher needs a custom topic as the event-ingress resource, and routing to a downstream processor is then defined by an event subscription on that topic. The event subscription can include filters such as event type or data fields so that only high-confidence events reach the processor. Creating a partner topic or domain is unnecessary for the stated custom workflow.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Create an Event Grid custom topic or domain
NEW QUESTION # 84
You have an Azure subscription named Sub1 that contains a resource group named RG1 and a Service Bus queue named SB1.
You plan to implement an Azure Event Grid push even: subscription that will deliver an event lo SB1 whenever a resource is created, modified, or deleted in RG1. You must minimize the development and configuration efforts.
You need to create an Event Grid topic for your planned implementation
Which type of event topic should you create?
Answer: A
NEW QUESTION # 85
You need to implement the semantic retrieval workflow for the recommendation engine to meet the technical and performance requirements of Fabrikam Inc.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.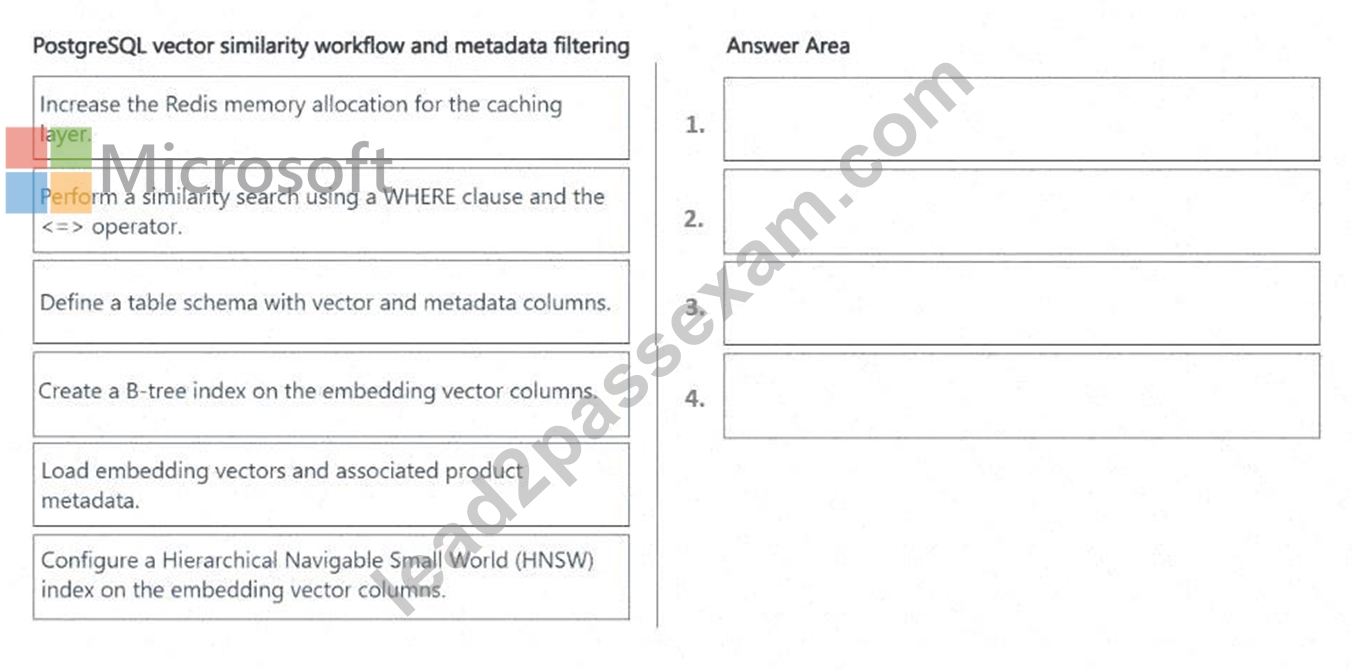
Answer:
Explanation: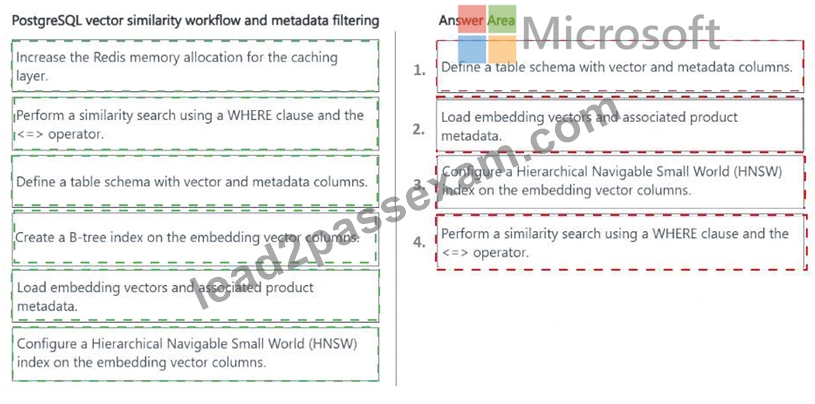
Explanation:
* Define a table schema with vector and metadata columns.
* Load embedding vectors and associated product metadata.
* Configure a Hierarchical Navigable Small World (HNSW) index on the embedding vector columns.
* Perform a similarity search using a WHERE clause and the < = > operator.
The workflow must first establish a PostgreSQL schema containing both the pgvector embedding column and the product metadata required for filtering. The embeddings and their associated metadata are then bulk- loaded. This ordering is important because Microsoft recommends loading data before creating vector indexes ; creating the index afterward provides faster ingestion and a more optimal index layout.
After loading, configure an HNSW index on the embedding column. HNSW is an approximate-nearest- neighbor index supported by pgvector and provides a strong speed/recall tradeoff for low-latency vector retrieval. Microsoft specifically documents HNSW for efficient cosine-distance searches in Azure Database for PostgreSQL.
Finally, execute the retrieval query so that mandatory product metadata constraints are applied through a WHERE clause , while vector similarity is evaluated with the < = > cosine-distance operator . This satisfies Fabrikam ' s requirement to calculate similarity only for eligible products.
A B-tree index is not an ANN vector index, and increasing Redis memory does not implement PostgreSQL semantic retrieval.
Study Guide references: Azure Database for PostgreSQL # pgvector, HNSW indexing, bulk-load optimization, vector similarity operators, metadata-filtered retrieval.
NEW QUESTION # 86
......
According to the needs of all people, the experts and professors in our company designed three different versions of the AI-200 certification training materials for all customers. The three versions are very flexible for all customers to operate. You can choose the version for yourself which is most suitable, and all the AI-200 Training Materials of our company can be found in the three versions. It is very flexible for you to use the three versions of the AI-200 latest questions to preparing for your AI-200 exam.
AI-200 Guaranteed Questions Answers: https://www.lead2passexam.com/Microsoft/valid-AI-200-exam-dumps.html