To contribute the long-term of cooperation with our customers, we offer great discount for purchasing our DP-750 exam pdf. Comparing to other dumps vendors, the price of our DP-750 questions and answers is reasonable for every candidate. You will grasp the overall knowledge points of DP-750 Actual Test with our pass guide and the accuracy of our DP-750 exam answers will enable you spend less time and effort.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Prepare and process data | 30-35% | - Data ingestion
|
>> DP-750 Real Exam Questions <<
Never say you can not do it. This is my advice to everyone. Even if you think that you can not pass the demanding Microsoft DP-750 exam. You can find a quick and convenient training tool to help you. DumpTorrent's Microsoft DP-750 exam training materials is a very good training materials. It can help you to pass the exam successfully. And its price is very reasonable, you will benefit from it. So do not say you can't. If you do not give up, the next second is hope. Quickly grab your hope, itis in the DumpTorrent's Microsoft DP-750 Exam Training materials.
NEW QUESTION # 73
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Answer: D
NEW QUESTION # 74
What does the VACUUM command do in Delta Lake?
Answer: D
Explanation:
VACUUM removes old, unreferenced files that are no longer needed after updates or deletes. It helps manage storage but does not improve query performance directly. OPTIMIZE handles performance improvements. Schema changes are unrelated.
NEW QUESTION # 75
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1 You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.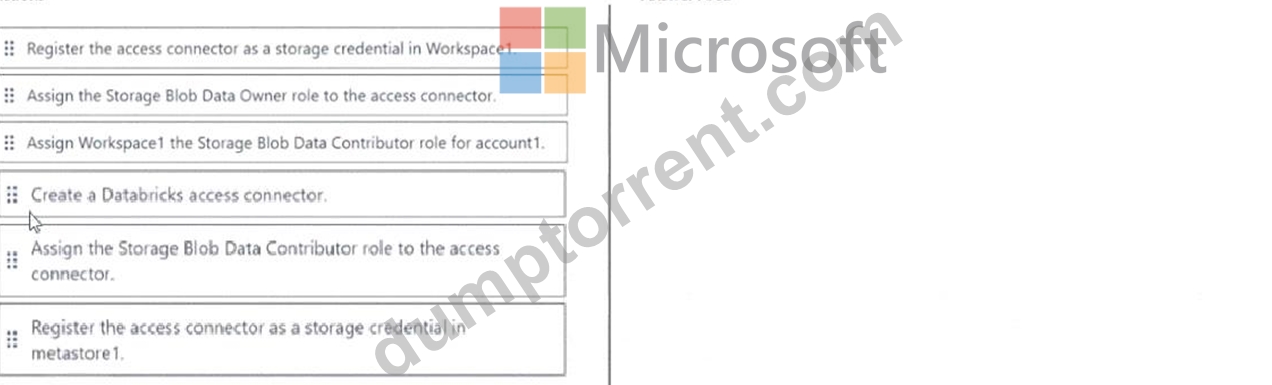
Answer:
Explanation: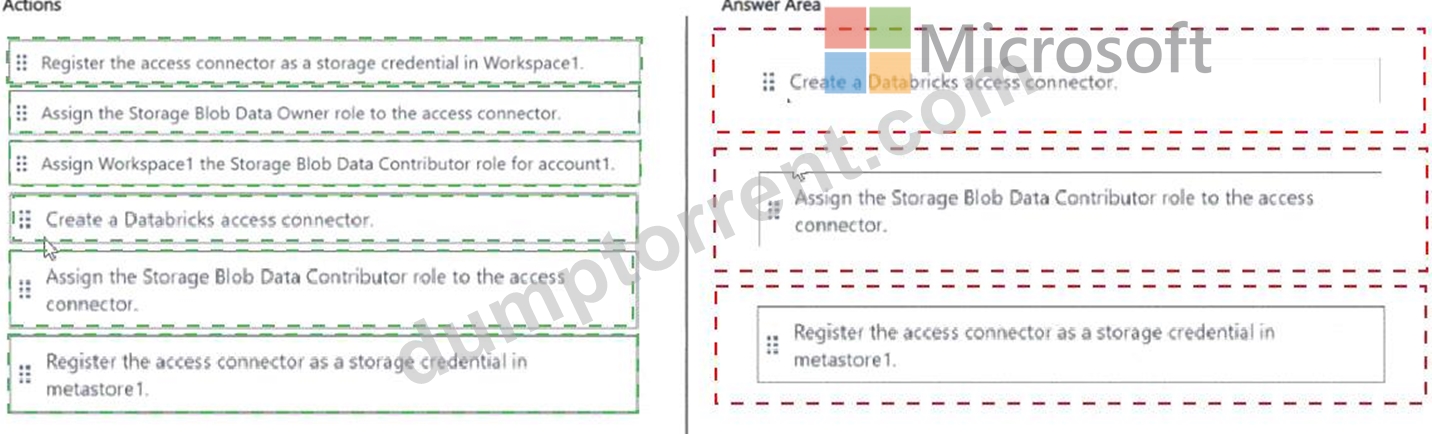
Explanation:
Registering an ADLS Gen2 account as an external location in Unity Catalog requires three steps in a specific order:
Step 1: Create a Databricks Access Connector. This Azure resource wraps a system-assigned or user-assigned managed identity. It is the credential-less authentication bridge between Databricks and Azure Storage - no SAS tokens or access keys are stored anywhere in the workspace.
Step 2: Create a Storage Credential in Unity Catalog that references the Access Connector. This object tells Unity Catalog 'use this identity when accessing storage.' The Storage Credential is the reusable authentication object.
Step 3: Create an External Location that maps a Unity Catalog path to the specific ADLS Gen2 container using the Storage Credential. This is the object that grants Databricks users access to files under that path, and it respects the principle of least privilege by scoping access to a specific container.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 76
You have an Azure Databricks workspace named Workspace1 that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1. Another user commits changes to Notebook1 in main.
When you attempt to merge Branch1 into main, the merge fails due to conflicts.
You need to merge Branch1 into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: A
Explanation:
To resolve the merge conflict and keep all changes from both branches, you must pull the updated main branch into your feature branch, resolve the conflicts manually within Databricks or a local Git tool, and then merge.
Reference:
https://devactivity.com/insights/streamlining-your-git-workflow-resolving-branch-behind-main- issues-in-your-git-repo/
NEW QUESTION # 77
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real-time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: C
Explanation:
Auto Loader incrementally detects and processes new files arriving in Azure Data Lake Storage Gen2 through the cloudFiles Structured Streaming source. It supports near-real-time ingestion while automatically tracking processed files, reducing the custom state-management code required. Its output can be written to a managed Delta table, and built-in schema inference and evolution reduce ongoing maintenance. Scheduled Spark batch jobs introduce latency based on their schedule and usually require custom file-tracking logic. An external table over CSV files does not ingest the data into a managed Delta table. Azure Data Factory can orchestrate ingestion, but it introduces another service and more configuration than the native Databricks capability needed here. Auto Loader is therefore the most direct and maintainable solution for continuously arriving cloud files. Microsoft Learn
Topic 1, Contoso Case Study
Overview
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region.
Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company ' s Azure environment contains:
* In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
* A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
* An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Company information Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Data Environment
Contoso ingests the following operational and business data:
* Telemetry data: More than 40,000 loT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
* Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
* Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
* External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
* ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company ' s existing analytics environment has several issues:
Ingestion
* Telemetry pipelines fall behind during peak loads.
* Telemetry ingestion fails when schema drift occurs.
* Streaming pipelines reprocess events after a pipeline restarts.
Compute
* Production and development workloads run on the same all-purpose clusters.
* Production and development workloads do NOT support autoscaling or workload isolation.
Governance
* The ERP data is duplicated across systems and development teams.
* Naming conventions are inconsistent across development teams, regions, and products.
* Ownership of the loT sensors changes over time, and analysts must track the full history of the ownership.
* Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names. Historical values are NOT required.
Pipeline operations
* Pipelines lack resiliency, alerting, and centralized scheduling.
Planned Changes
Contoso plans to implement the following changes:
* Implement scalable data pipeline orchestration.
* Create a managed analytics catalog in Unity Catalog.
* Implement a consistent approach to creating curated datasets.
* Establish a centralized governance model across ingestion, cleansed, and curated layers.
* Grant data engineers access to the ERP tables by using minimal development effort.
* Adopt a compute strategy that isolates production workloads and supports autoscaling.
* Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
* Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
* Provide fast and consistent performance for business intelligence (Bl) workloads.
* Prevent development activity from affecting production pipelines.
* Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
* Auto-scale ingestion pipelines to handle bursty workloads.
* Handle schema drift for the maintenance and telemetry data.
* Ingest file-based telemetry data by using minimal operational effort.
* Store all the ingested data in a format that supports incremental processing.
* Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
* Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
* Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
* Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
* Build curated tables that standardize business logic.
* Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements: |