2026 Latest TestKingIT SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1tcq5OA6MmHRaUsyUXG92Xc0CqAY_bzW2
TestKingIT is a website to improve the pass rate of Snowflake certification SPS-C01 exam. Senior IT experts in the TestKingIT constantly developed a variety of successful programs of passing Snowflake certification SPS-C01 exam, so the results of their research can 100% guarantee you Snowflake certification SPS-C01 exam for one time. TestKingIT's training tools are very effective and many people who have passed a number of IT certification exams used the practice questions and answers provided by TestKingIT. Some of them who have passed the Snowflake Certification SPS-C01 Exam also use TestKingIT's products. Selecting TestKingIT means choosing a success
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API and Development | 30% | - Python API fundamentals
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Performance and Best Practices | 10% | - Optimization techniques
|
To get better condition of life, we all need impeccable credentials of different exams to prove individual’s capacity. However, weak SPS-C01 practice materials may descend and impair your ability and flunk you in the real exam unfortunately. And the worst condition is all that work you have paid may go down the drain for those SPS-C01 question torrent lack commitments and resolves to help customers. The practice materials of the exam with low quality may complicate matters of the real practice exam. So, you must know about our SPS-C01 question torrent.
NEW QUESTION # 171
You are using Snowpark in Python within a Jupyter Notebook environment to analyze sales data'. You've established a connection to Snowflake and loaded your data into a Snowpark DataFrame named 'sales ff. You need to calculate the cumulative sales for each product category over time. The 'sales_df' DataFrame has columns 'SALE DATE' (DATE), 'PRODUCT CATEGORY' (VARCHAR), and 'SALE AMOUNT' (NUMBER). Which of the following approaches, or combination of approaches, will correctly calculate the cumulative sales while optimizing for Snowflake's performance and scalability? (Select all that apply)
Answer: A,C,E
Explanation:
Options A, C, and E are correct. Option A utilizes Snowpark's DataFrame transformations with window functions, which are optimized for Snowflake's engine and can efficiently handle large datasets. This leverages Snowflake's parallel processing capabilities. Option C involves creating a stored procedure within Snowflake. This approach pushes the computation to the Snowflake server, potentially improving performance, especially if the cumulative sales calculation is complex. This also benefits from Snowflake's optimization capabilities. Option E executes a SQL query with a window function that's optimized. Option B is incorrect because iterating through rows in a Jupyter Notebook will be extremely slow and inefficient for large datasets. It defeats the purpose of using Snowpark for distributed data processing. Calculating cumulative sales this way doesn't leverage Snowflake's capabilities. Option D is partially correct in that it orders the data, but using a UDF for cumulative sum calculation will likely be less efficient than using native window functions within Snowflake.
NEW QUESTION # 172
You are developing a Snowpark Python application that reads data from an external stage (AWS S3) and performs several transformations before loading it into a Snowflake table. During testing, you encounter the following error: net.snowflake.client.jdbc.SnowflakeSQLException: SQL compilation error: User does not have OWNERSHIP privilege on integration object 'YOUR INTEGRATION NAME". You have confirmed that the user has the 'USAGE privilege on the integration. Besides granting ownership, which of the following actions could resolve this issue in the MOST secure and efficient way?
Answer: E
Explanation:
Option B is the MOST secure and efficient. The error indicates that the user lacks necessary privileges to utilize the integration for creating objects (in this case, likely an internal stage used during the transformation process). Granting a custom role with both 'USAGE on the integration and 'CREATE TABLE on the database adheres to the principle of least privilege. Option A grants broad privileges to the user, which is less secure. Option C involves complex integration setup and might not be necessary for a simple data loading scenario. Option D is related to reading data from the external stage, not using the integration for internal operations. Option E bypasses the error without addressing the underlying permission issue.
NEW QUESTION # 173
You have two Snowpark DataFrames, 'dfl' and 'df2 , both containing customer data, but with slightly different schemas. 'dfl' has columns 'customer_id', 'name', and 'email'. 'df2' has columns 'id', 'customer name', and 'email_address'. You want to perform a set- based operation to find all unique customer IDs present in 'dfl but NOT in 'df2' , considering that 'customer_id' in 'dfl corresponds to 'id' in 'df2. Which of the following code snippets will achieve this, ensuring that column names are correctly aligned before the operation?





Answer: C
Explanation:
Option D is the correct solution. First, 'customer_id')' renames the 'id' column in 'df2 to 'customer_id', aligning it with the 'customer_id' column in 'dfl Then, 'cifl performs the set difference operation, returning only the 'customer_id' values present in 'dfl& but not in the modified 'df2. 'exceptAll' (Option A) will include duplicates. Option B uses 'minus' which does not exist on Snowpark DataFrame. Options C uses 'subtract which also does not exist. Option E will cause unexpected results because the column name of dfl and df2 would be different.
NEW QUESTION # 174
You are working with a Snowpark DataFrame 'products df' containing product information, including 'product_id', 'price', and 'discount'. You need to update the 'price' column in the 'products' table based on the following logic: If 'discount' is greater than 0.2, reduce the 'price' by 15%. If 'discount' is between 0.1 and 0.2 (inclusive), reduce the 'price' by 5%. Otherwise, keep the 'price' as is. Which of the following Snowpark code snippets efficiently implements this update? Assume 'products' table already exists and is correctly populated.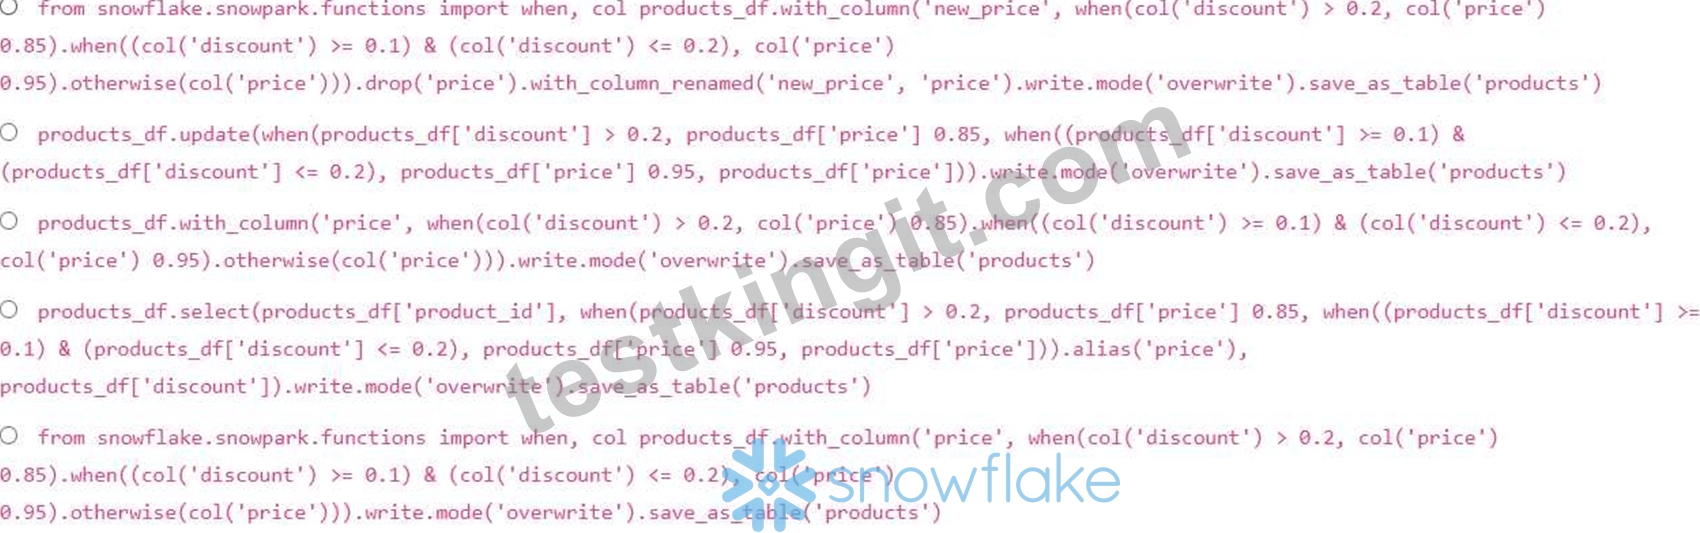
Answer: B
Explanation:
Option E is the most concise and correct solution. It uses 'with_column' to directly update the 'price' column based on the discount conditions, using nested 'when' functions for the logic and persists the change. Option A, while technically correct, is less efficient because it creates a new column ('new_price'), drops the original 'price' column, and then renames the new column. Option B tries to use an 'update' method which doesn't exist directly on Snowpark DataFrames in that way. Option C works correctly. Option D has an issue that it won't keep the original schema of the table being updated as it is selecting each of the columns.
NEW QUESTION # 175
You have created a Snowpark stored procedure in Python that accesses a Snowflake stage to read configuration files. To enhance security, you want to grant the stored procedure specific permissions to only read files from that stage, without granting broader account- level access. Which of the following approaches is the MOST secure and granular way to achieve this?
Answer: D
Explanation:
Using 'EXECUTE AS CALLER ensures the stored procedure executes with the privileges of the user calling it. This is the most secure and granular approach because you don't need to grant any specific privileges to the stored procedure itself. The user calling it must already have the necessary permissions to access the stage.
NEW QUESTION # 176
......
Our SPS-C01 study prep is classified as three versions up to now. All these versions of our SPS-C01 exam braindumps are popular and priced cheap with high quality and accuracy rate. They achieved academic maturity so that their quality far beyond other practice materials in the market with high effectiveness and more than 98 percent of former candidates who chose our SPS-C01 Practice Engine win the exam with their dream certificate.
SPS-C01 Valid Test Braindumps: https://www.testkingit.com/Snowflake/latest-SPS-C01-exam-dumps.html
What's more, part of that TestKingIT SPS-C01 dumps now are free: https://drive.google.com/open?id=1tcq5OA6MmHRaUsyUXG92Xc0CqAY_bzW2