BTW, DOWNLOAD part of RealVCE Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1npDR6WCS4WiwEgRjwSbZiMP95De8K_41
These Databricks Databricks-Certified-Data-Analyst-Associate exam questions have a high chance of coming in the actual Databricks-Certified-Data-Analyst-Associate test. You have to memorize these Databricks-Certified-Data-Analyst-Associate questions and you will pass the Databricks Databricks-Certified-Data-Analyst-Associate test with brilliant results. The price of Databricks Databricks-Certified-Data-Analyst-Associate updated exam dumps is affordable.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Exam Price: | $200 USD |
| Real Exam Qty: | 45 |
| Exam Format: | Multiple Choice |
| Certificate Validity Period: | 2 years |
| Available Languages: | English |
| Exam Duration: | 90 minutes |
| Passing Score: | 70% |
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
| Exam Way: | Online proctored or test center proctored |
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
>> Databricks-Certified-Data-Analyst-Associate Valid Dumps Demo <<
Our Databricks-Certified-Data-Analyst-Associate Test Braindumps boost high hit rate and can stimulate the exam to let you have a good preparation for the exam. Our Databricks-Certified-Data-Analyst-Associate prep torrent boost the timing function and the content is easy to be understood and has been simplified the important information. Our Databricks-Certified-Data-Analyst-Associate test braindumps convey more important information with less amount of answers and questions and thus make the learning relaxed and efficient. If you fail in the exam we will refund you immediately. All Databricks Certified Data Analyst Associate Exam exam torrent does a lot of help for you to pass the exam easily and successfully.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 85
Consider the following two statements:
Statement 1: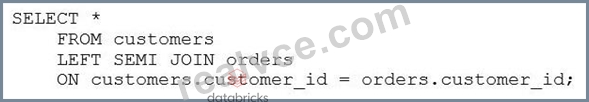
Statement 2: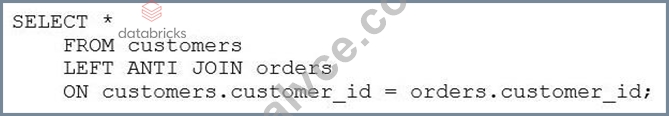
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
Answer: E
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id). Therefore, the result sets for the two statements will differ in the following way:
The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
A) The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
C) There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
D) Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
E) The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
NEW QUESTION # 86
A stakeholder has provided a data analyst with a lookup dataset in the form of a 50-row CSV file. The data analyst needs to upload this dataset for use as a table in Databricks SQL.
Which approach should the data analyst use to quickly upload the file into a table for use in Databricks SOL?
Answer: B
Explanation:
Databricks provides a user-friendly interface that allows data analysts to quickly upload small datasets, such as a 50-row CSV file, and create tables within Databricks SQL. The steps are as follows:
* Access the Data Upload Interface:
* In the Databricks workspace, navigate to the sidebar and click on New > Add or upload data.
* Select Create or modify a table.
* Upload the CSV File:
* Click on the browse button or drag and drop the CSV file directly onto the designated area.
* The interface supports uploading up to 10 files simultaneously, with a total size limit of 2 GB.
* Configure Table Settings:
* After uploading, a preview of the data is displayed.
* Specify the table name, select the appropriate schema, and configure any additional settings as needed.
* Create the Table:
* Once all configurations are set, click on the Create Table button to finalize the process.
This method is efficient for quickly importing small datasets without the need for additional tools or complex configurations. Options B, C, and D involve more complex or manual processes that are unnecessary for this task.
Reference: Create or modify a table using file upload
NEW QUESTION # 87
What is a benefit of using Databricks SQL for business intelligence (Bl) analytics projects instead of using third-party Bl tools?
Answer: C
Explanation:
Databricks SQL offers a unified platform where computations, data storage, and analytical tools coexist seamlessly. This integration allows business intelligence (BI) analytics projects to be executed more efficiently, as users can perform data processing and analysis without the need to transfer data between disparate systems. By consolidating these components, Databricks SQL streamlines workflows, reduces latency, and enhances data governance. While third-party BI tools may offer advanced dashboarding capabilities, simultaneous multi-user support, and automated alerting systems, they often require integration with separate data processing platforms, which can introduce complexity and potential inefficiencies.
NEW QUESTION # 88
A data engineer wants to create a relational object by pulling data from two tables. The relational object does not need to be used by other data engineers in other sessions. In order to save on storage costs, the data engineer wants to avoid copying and storing physical data.
Which of the following relational objects should the data engineer create?
Answer: B
Explanation:
Option D is correct. A temporary view is session-scoped and does not store physical data. It is suitable when the relational object is only needed in the current session or query context and should not be available to others in other sessions. A regular view also avoids copying physical data, but it is persistent and can be shared beyond the current session. Official Databricks extract: a view is a "virtual table that has no physical data," and temporary views are scoped to the notebook/script or query level and cannot be referenced outside that scope.
NEW QUESTION # 89
A data analyst is attempting to drop a table my_table. The analyst wants to delete all table metadata and data.
They run the following command:
DROP TABLE IF EXISTS my_table;
While the object no longer appears when they run SHOW TABLES, the data files still exist.
Which of the following describes why the data files still exist and the metadata files were deleted?
Answer: B
Explanation:
An external table is a table that is defined in the metastore, but its data is stored outside of the Databricks environment, such as in S3, ADLS, or GCS. When an external table is dropped, only the metadata is deleted from the metastore, but the data files are not affected. This is different from a managed table, which is a table whose data is stored in the Databricks environment, and whose data files are deleted when the table is dropped. To delete the data files of an external table, the analyst needs to specify the PURGE option in the DROP TABLE command, or manually delete the files from the storage system. Reference: DROP TABLE, Drop Delta table features, Best practices for dropping a managed Delta Lake table
NEW QUESTION # 90
......
Databricks-Certified-Data-Analyst-Associate Test Voucher: https://www.realvce.com/Databricks-Certified-Data-Analyst-Associate_free-dumps.html
BTW, DOWNLOAD part of RealVCE Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1npDR6WCS4WiwEgRjwSbZiMP95De8K_41