BONUS!!! Download part of PremiumVCEDump DP-750 dumps for free: https://drive.google.com/open?id=1J0QAJrWgahDINou3pXc9TKL6xpwvQCQ4
Many exam candidates attach great credence to our DP-750 simulating exam. You can just look at the hot hit on our website on the DP-750 practice engine, and you will be surprised to find it is very popular and so many warm feedbacks are written by our loyal customers as well. Our DP-750 study prep does not need any ads, their quality has propaganda effect themselves. As a result, the pass rate of our DP-750 exam braindumps is high as 98% to 100%.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
They work together and put all their expertise, knowledge, and experience and make sure the top standard of PremiumVCEDump DP-750 exam questions all the time. So we can say that the PremiumVCEDump DP-750 exam practice test questions are the ideal study material for quick Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam preparation. The PremiumVCEDump DP-750 exam questions are real, valid, and updated as per the latest Microsoft DP-750 exam syllabus and you can trust it and start Microsoft DP-750 exam preparation right now.
NEW QUESTION # 14
Which layer contains cleaned and conformed data in Databricks Lakehouse architecture?
Answer: C
Explanation:
Silver layer contains cleaned, validated, and enriched data ready for analytics. Bronze stores raw ingested data. Gold contains aggregated business-level data. Raw is not part of formal medallion architecture naming.
NEW QUESTION # 15
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 16
Which component enforces table-level permissions in Databricks?
Answer: A
Explanation:
Unity Catalog provides fine-grained access control at table, schema, and column levels. It centralizes governance across workspaces. Cluster policies control compute settings. Spark configuration does not manage security. DBFS permissions are not sufficient for enterprise governance.
NEW QUESTION # 17
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.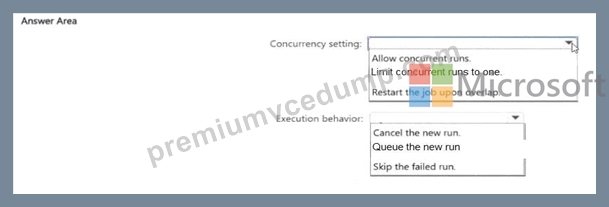
Answer:
Explanation: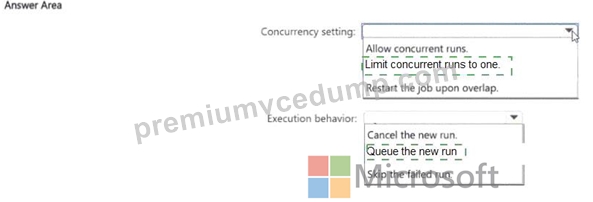
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to ' Skip ' (or ' Allow only one concurrent run ' ). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to ' Skip ' is ' Wait ' (queue the new run), which ensures every scheduled run eventually executes - but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
NEW QUESTION # 18
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.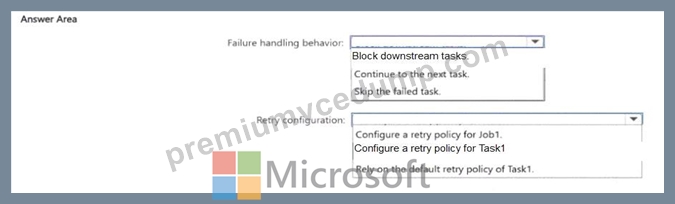
Answer:
Explanation: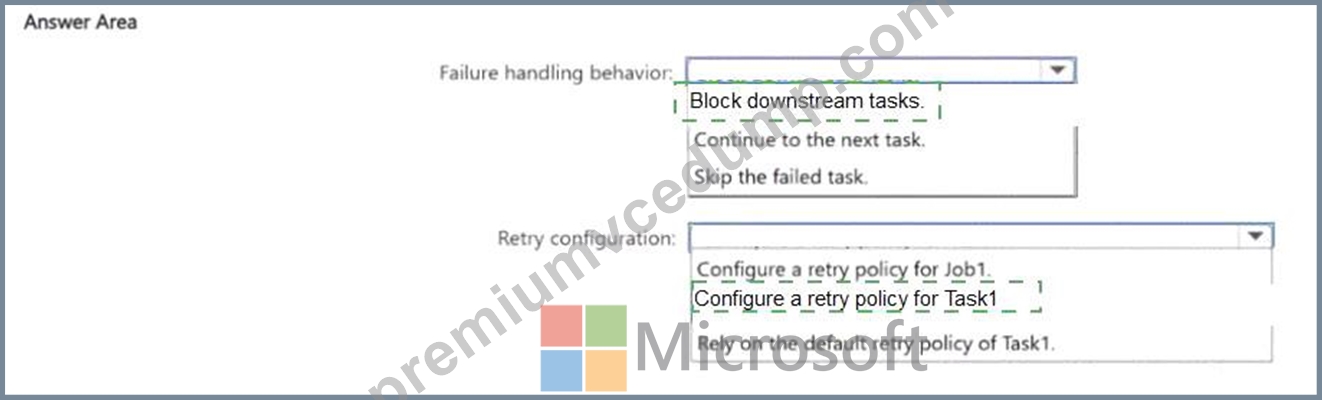
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to ' All succeeded ' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2 ' s ' Depends on ' setting in the job configuration.
These two settings are independent and composable. Task1 ' s retry policy gives it multiple chances to recover. Task2 ' s dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 19
......
The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) actual questions we sell also come with a free demo. Spend no time, otherwise, you will pass on these fantastic opportunities. Start preparing for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam by purchasing the most recent Microsoft DP-750 exam dumps. You must improve your skills and knowledge to stay current and competitive. You merely need to obtain the DP-750 Certification Exam badge in order to achieve this. You must pass the Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam to accomplish this, which can only be done with thorough exam preparation. Download the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions right away for immediate and thorough exam preparation.
DP-750 Passguide: https://www.premiumvcedump.com/Microsoft/valid-DP-750-premium-vce-exam-dumps.html
DOWNLOAD the newest PremiumVCEDump DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1J0QAJrWgahDINou3pXc9TKL6xpwvQCQ4