What's more, part of that ActualVCE AI-300 dumps now are free: https://drive.google.com/open?id=1u4L5KB9o5ea-HG6CbXjXjZkZBMgZoCMu
ActualVCE is proud to announce that our Microsoft AI-300 exam dumps help the desiring candidates of Microsoft AI-300 certification to climb the ladder of success by grabbing the Microsoft Exam Questions. ActualVCE trained experts have made sure to help the potential applicants of Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification to pass their Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam on the first try. Our PDF format carries real Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam dumps.
| Section | Weight | Objectives |
|---|---|---|
| Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
>> Pass4sure AI-300 Dumps Pdf <<
Microsoft AI-300 exam questions are the best because these are so realistic! It feels just like taking a real Microsoft AI-300 exam, but without the stress! Our Microsoft AI-300 Practice Test software is the answer if you want to score higher on your real Microsoft AI-300 certification exam and achieve your academic goals.
NEW QUESTION # 54
Drag and Drop Question
You have several machine learning models registered in an Azure Machine Learning workspace.
You must use the Fairlearn dashboard to assess fairness in a selected model.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.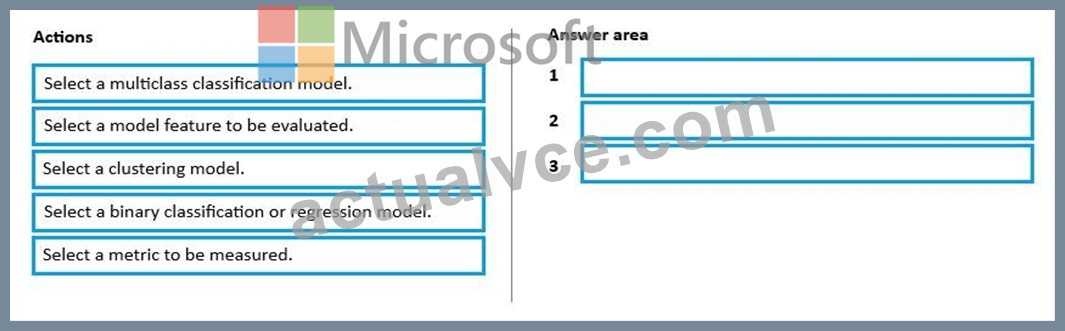
Answer:
Explanation: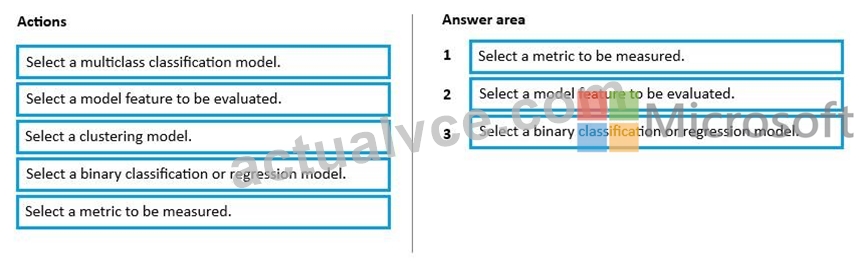
Explanation:
Step 1: Select a metric to measured
You need to choose a baseline performance or fairness metric (such as accuracy rate, precision, or demographic parity) along which the dashboard evaluates the model's overall behavior and cross-group disparities.
Step 2: Select a model feature to evaluated
You must specify a sensitive feature (such as age, gender, or race) to split the data into different subgroups and evaluate potential disparities across them.
Step 3: Select a binary classification or regression model
The Fairlearn package is specifically designed to assess and mitigate unfairness in binary classification and regression tasks. It does not natively support clustering or multiclass models for group fairness assessments in this wizard.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-fairness-ml?view=azureml-api-2
NEW QUESTION # 55
A data science team completes multiple training runs within an experiment by using MLflow.
The team wants to store a selected model in Azure Machine Learning so that it can be versioned and deployed later.
The model must be versioned centrally for reuse across environments.
You need to version the trained model.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
Answer: A,C
Explanation:
MLflow training runs produce model artifacts - the serialized model files, conda environment, and MLmodel specification - stored in the run ' s outputs folder. These artifacts are transient run outputs but are not yet a versioned, named model that can be deployed. To make the model a first-class, versioned, deployable artifact, you must explicitly register it. Locating artifacts from the run (action A) is necessary because you need the run ' s artifact URI, typically in the form runs:/run_id/model, to register from.
Registering in the AML workspace (action B) creates an entry in the model registry with a name and auto- incremented version, making the model discoverable, governable, and deployable across environments.
Tagging the experiment (option C) does not version the model. Exporting to local storage (option D) removes the model from Azure ML ' s managed infrastructure, losing lineage and governance.
Microsoft Learn Reference Topic: Register MLflow models in the Azure Machine Learning model registry
NEW QUESTION # 56
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to improve a GPT-5 model performance based on Fabrikam Inc.'s technical requirements. Which action should you perform first?
Answer: A
Explanation:
The recommended first action is to evaluate the model output.
Why This Is the Correct First Step
According to OpenAI's Model Optimization Framework, you must measure your baseline performance before moving to advanced optimization techniques like fine-tuning. You cannot objectively determine whether prompt engineering is "insufficient" without an established evaluation suite to quantify where the model diverges from expectations.
Scenario: To support the business goals, Fabrikam Inc. identifies these technical requirements:
Deploy traditional machine learning models with support for staged rollout and rollback.
Improve RAG-based solution output quality.
Use the existing evaluation datasets that are based on real data with input-output pairs.
-> Apply advanced fine-tuning techniques only when prompt engineering is insufficient Reference:
https://developers.openai.com/api/docs/guides/model-optimization
NEW QUESTION # 57
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
An organization provisions Azure Machine Learning workspaces for development, test, and production environments.
Each environment must be deployed consistently and updated through source control. The deployment process must be automated, repeatable, and auditable.
You need to deploy Azure Machine Learning resources in a consistent and controlled manner.
Solution: Define Azure Machine Learning resources in a Bicep template and deploy them within a GitHub Action.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Define Azure Machine Learning resources in a Bicep template and deploy them within a GitHub Action.
This action is best because it fulfills all of your operational requirements:
Consistency & Controlled Manner:
Infrastructure as Code (IaC) via Bicep ensures that dev, test, and prod environments are configured identically, eliminating configuration drift.
Source Control: Storing the Bicep template in a Git repository satisfies the requirement that each environment must be updated through source control.
Automated & Repeatable: Orchestrating the deployment using GitHub Actions fully automates the workflow, allowing it to be executed reliably every time a change is merged.
Auditable: Git commit histories combined with GitHub deployment logs provide a comprehensive, compliant audit trail of exactly who modified the infrastructure and when.
Incorrect:
* Clone an existing Azure Machine Learning workspace to create additional environments.
* Create Azure Machine Learning workspaces manually in the Azure portal for each environment.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-github-actions-machine-learning
NEW QUESTION # 58
Hotspot Question
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.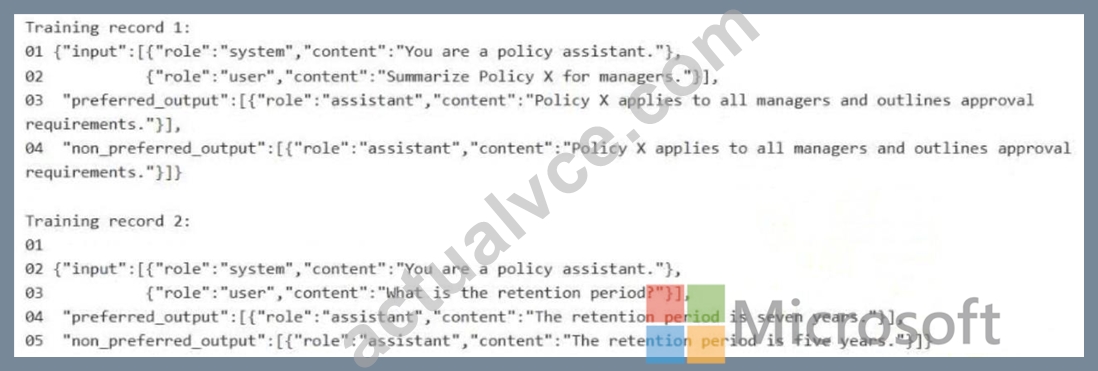
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.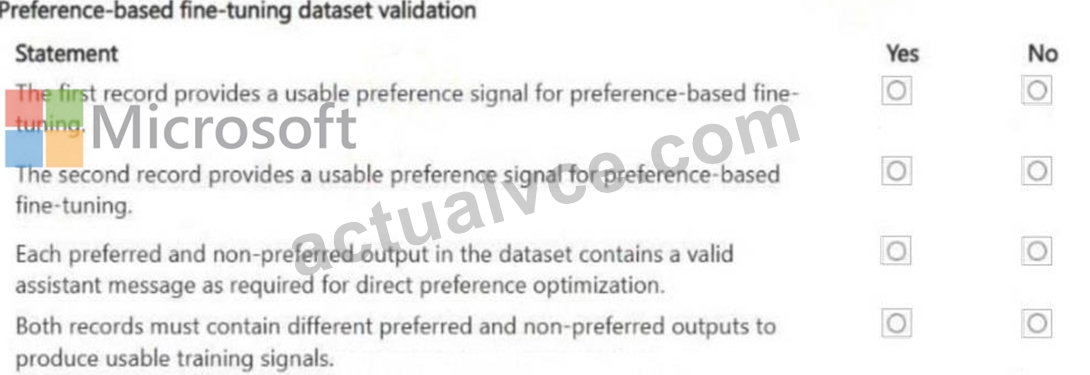
Answer:
Explanation: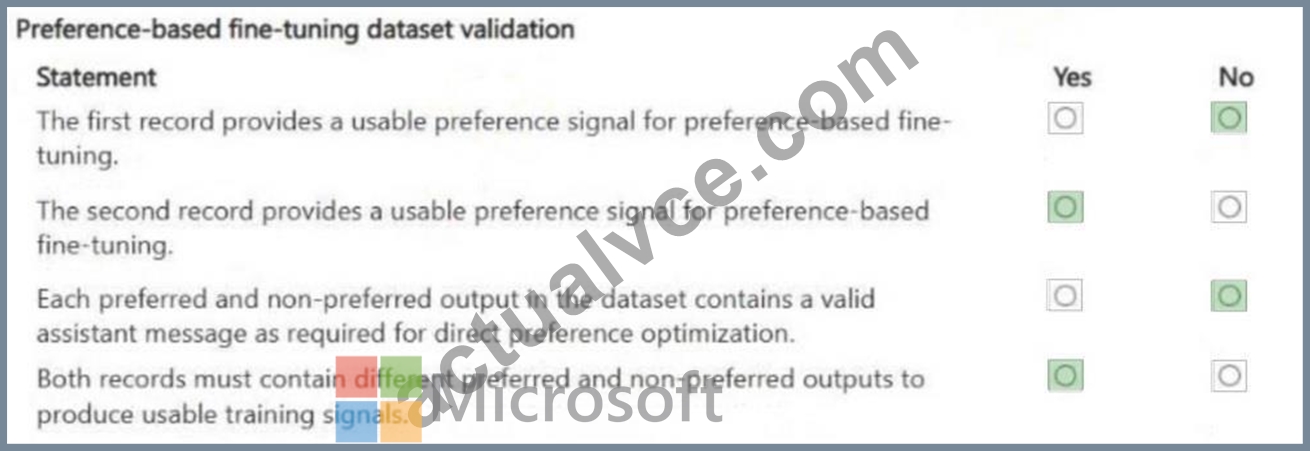
NEW QUESTION # 59
......
Because the busy people seldom have much time to read the books they need. So how should people get their dreaming AI-300 certification by passing the exam? At this time, people should to need some good AI-300 study materials. Not only will our AI-300 Exam Questions help you pass exam, but it will also save your valuable time. Now you can free download the demos of our AI-300 exam questions to have an experience the good quality and validity.
Exam AI-300 Training: https://www.actualvce.com/Microsoft/AI-300-valid-vce-dumps.html
BTW, DOWNLOAD part of ActualVCE AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1u4L5KB9o5ea-HG6CbXjXjZkZBMgZoCMu