Web-based software works without installation. Databricks Certified Professional Data Engineer Exam exam practice test software works on all well-known browsers, including Chrome, Firefox, Safari, and Opera. Trust Pass4Leader - Databricks Databricks-Certified-Professional-Data-Engineer exam preparation products and be prepared for the Databricks Certified Professional Data Engineer Exam at your home. Preparing and testing yourself, again and again, can be nerve-wracking, so in this scenario, we provide a Databricks Databricks-Certified-Professional-Data-Engineer PDF for exam preparation.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
>> Databricks-Certified-Professional-Data-Engineer New Exam Braindumps <<
Immediately after you have made a purchase for our Databricks-Certified-Professional-Data-Engineer practice test, you can download our exam study materials to make preparations for the exams. It is universally acknowledged that time is a key factor in terms of the success of exams. There is why our Databricks-Certified-Professional-Data-Engineer Test Prep exam is well received by the general public. I believe if you are full aware of the benefits the immediate download of our PDF study exam brings to you, you will choose our Databricks-Certified-Professional-Data-Engineer actual study guide.
NEW QUESTION # 41
Below table temp_data has one column called raw contains JSON data that records temperature for every four hours in the day for the city of Chicago, you are asked to calculate the maximum temperature that was ever recorded for 12:00 PM hour across all the days. Parse the JSON data and use the necessary array function to calculate the max temp.
Table: temp_date
Column: raw
Datatype: string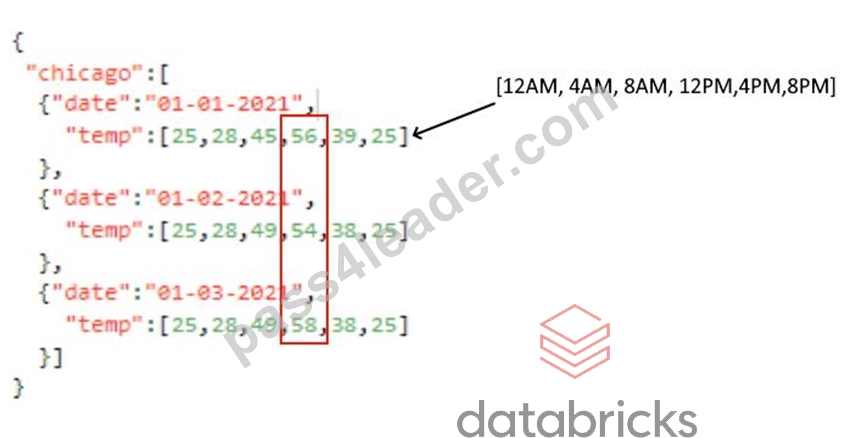
Expected output: 58
Answer: B
Explanation:
Explanation
Note: This is a difficult question, more likely you may see easier questions similar to this but the more you are prepared for the exam easier it is to pass the exam.
Use this below link to look for more examples, this will definitely help you,
https://docs.databricks.com/optimizations/semi-structured.html
Here is the solution, step by step
Text Description automatically generated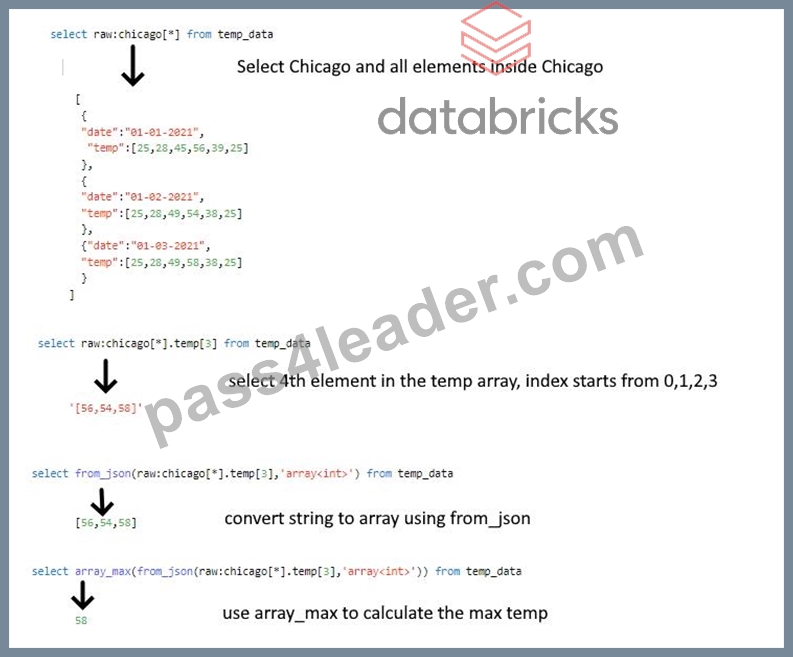
Use this below link to look for more examples, this will definitely help you,
https://docs.databricks.com/optimizations/semi-structured.html
If you want to try this solution use below DDL,
1.create or replace table temp_data
2. as select ' {
3. "chicago":[
4.{"date":"01-01-2021",
5."temp":[25,28,45,56,39,25]
6.},
7.{"date":"01-02-2021",
8."temp":[25,28,49,54,38,25]
9.},
10.{"date":"01-03-2021",
11."temp":[25,28,49,58,38,25]
12. }]
13. }
14. ' as raw
15.
16.select array_max(from_json(raw:chicago[*].temp[3],'array<int>')) from temp_data
17.
NEW QUESTION # 42
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped.
Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
Answer: C
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) → records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) → records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) → records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount ≤ 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 43
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalidlatitudeandlongitudevalues in theactivity_detailstable have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to addCHECKconstraints to the Delta Lake table: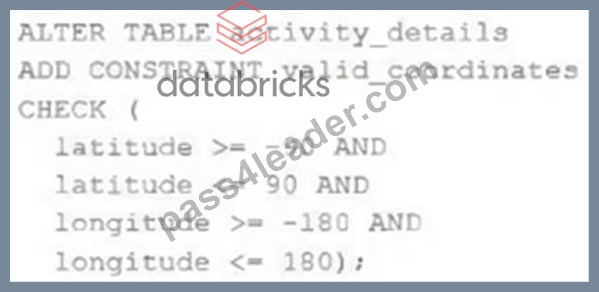
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: C
Explanation:
Explanation
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
NEW QUESTION # 44
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team: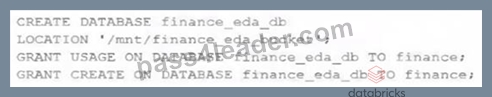
After the database was successfully created and permissions configured, a member of the finance team runs the following code: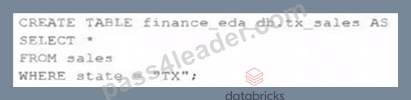
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
Answer: C
Explanation:
https://docs.databricks.com/en/lakehouse/data-objects.html
NEW QUESTION # 45
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
Answer: B
Explanation:
Explanation
The configuration that automatically recovers from query failures and keeps costs low is to use a new job cluster, set retries to unlimited, and set maximum concurrent runs to 1. This configuration has the following advantages:
A new job cluster is a cluster that is created and terminated for each job run. This means that the cluster resources are only used when the job is running, and no idle costs are incurred. This also ensures that the cluster is always in a clean state and has the latest configuration and libraries for the job1.
Setting retries to unlimited means that the job will automatically restart the query in case of any failure, such as network issues, node failures, or transient errors. This improves the reliability and availability of the streaming job, and avoids data loss or inconsistency2.
Setting maximum concurrent runs to 1 means that only one instance of the job can run at a time. This prevents multiple queries from competing for the same resources or writing to the same output location, which can cause performance degradation or data corruption3.
Therefore, this configuration is the best practice for scheduling Structured Streaming jobs for production, as it ensures that the job is resilient, efficient, and consistent.
References: Job clusters, Job retries, Maximum concurrent runs
NEW QUESTION # 46
......
The second format is a web-based format that can be accessed from browsers like Firefox, Microsoft Edge, Chrome, and Safari. It means you don't need to download or install any software or plugins to take the Databricks Certified Professional Data Engineer Exam practice test. The web-based format of the Databricks Databricks-Certified-Professional-Data-Engineer Certification Exams practice test supports all operating systems. The third and last format is desktop software format which can be accessed after installing the software on your Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) Windows Pc or Laptop. These formats are built especially for the students so they don't stop preparing for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification.
Databricks-Certified-Professional-Data-Engineer Reliable Exam Pattern: https://www.pass4leader.com/Databricks/Databricks-Certified-Professional-Data-Engineer-exam.html