100% Pass Quiz 2026 Databricks Professional Certified-Data-Engineer-Professional Latest Training

P.S. Free 2026 Databricks Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PDF4Test: https://drive.google.com/open?id=1DPVDo0ZeMBU74leVbSm_MxUfCcKZlxlU
With the help of the Certified-Data-Engineer-Professional practice exam questions and preparation material offered by PDF4Test, you can pass any Certified-Data-Engineer-Professional certifications exam in the first attempt. You don’t have to face any trouble, and you can simply choose to do a selective Certified-Data-Engineer-Professional brain dumps to pass the exam. We offer guaranteed success with Certified-Data-Engineer-Professional Questions on the first attempt, and you will be able to pass the Certified-Data-Engineer-Professional exam in short time. You can always consult our Certified-Data-Engineer-Professional certified professional support if you are facing any problems.
| Section | Objectives |
|---|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Use APPLY CHANGES APIs for change data capture
- 2. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 3. Develop unit and integration tests for data processing code
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Compare streaming tables and materialized views
- 6. Configure environments, dependencies, memory, and retry behavior
- 7. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 8. Use control flow operators in pipeline components
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
>> Certified-Data-Engineer-Professional Latest Training <<
Databricks Certified-Data-Engineer-Professional Book Free | Reliable Certified-Data-Engineer-Professional Braindumps
Free update for one year after purchasing is available for Certified-Data-Engineer-Professional study guide, therefore there is no need for you to spend extra money on update version. And the update version for Certified-Data-Engineer-Professional exam dumps will be sent to your email automatically, you just need to check your email for the update version. Besides, Certified-Data-Engineer-Professional Exam Materials are compiled by experienced experts and, so the quality can be guaranteed. We have online and offline service, and they possess the professional knowledge for Certified-Data-Engineer-Professional exam materials, and if you have any questions, you can consult us.
Databricks Certified Data Engineer Professional Sample Questions (Q156-Q161):
NEW QUESTION # 156
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
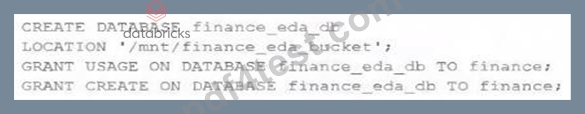
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
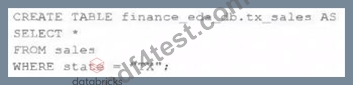
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. A managed table will be created in the DBFS root storage container.
- B. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- C. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- D. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- E. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
Answer: C
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 157
A developer has successfully configured their credentials for Databricks Repos and cloned a remote Git repository. They do not have privileges to make changes to the main branch, which is the only branch currently visible in their workspace. Which approach allows this user to share their code updates without the risk of overwriting the work of their teammates?
- A. Use Repos to merge all differences and make a pull request back to the remote repository.
- B. Use repos to merge all difference and make a pull request back to the remote repository.
- C. Use Repos to pull changes from the remote Git repository; commit and push changes to a branch that appeared as changes were pulled.
- D. Use Repos to create a new branch commit all changes and push changes to the remote Git repertory.
- E. Use repos to create a fork of the remote repository commit all changes and make a pull request on the source repository
Answer: D
Explanation:
In Databricks Repos, when a user does not have privileges to make changes directly to the main branch of a cloned remote Git repository, the recommended approach is to create a new branch within the Databricks workspace. The developer can then make changes in this new branch, commit those changes, and push the new branch to the remote Git repository. This workflow allows for isolated development without affecting the main branch, enabling the developer to propose changes via a pull request from the new branch to the main branch in the remote repository. This method adheres to common Git collaboration workflows, fostering code review and collaboration while ensuring the integrity of the main branch.
NEW QUESTION # 158
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
- A. Set the configuration delta.deduplicate = true.
- B. VACUUM the Delta table after each batch completes.
- C. Rely on Delta Lake schema enforcement to prevent duplicate records.
- D. Perform a full outer join on a unique key and overwrite existing data.
- E. Perform an insert-only merge with a matching condition on a unique key.
Answer: E
Explanation:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
NEW QUESTION # 159
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date. Which operation lacks support for cluster on write?
- A. spark.writestream.format('delta').mode('append')
- B. CTAS and RTAS statements
- C. spark.write.format('delta').mode('append')
- D. INSERT INTO operations
Answer: A
Explanation:
Delta Lake's Liquid Clustering is an advanced feature that improves query performance by dynamically clustering data without requiring costly compaction steps like traditional Z-ordering.
When performing writes to a Liquid Clustered table, some write operations automatically maintain clustering, while others do not.
NEW QUESTION # 160
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
- A. When stored as SCD 1, the target of AUTO CDC INTO includes updates and deletes. Streaming from customer_dim can fail due to these operations. Instead, build another stream from the original source.
- B. Use ignoreChanges flag while streaming from customer_dim to avoid breaking the pipeline during updates and deletes.
- C. Read change data feed from customer_dim table and apply filters to incrementally act on the change events.
- D. Streaming from customer_dim table would only be possible in the case of SCD 2 retention.
Answer: C
Explanation:
Reading the change data feed from the customer_dim table enables downstream processing to react specifically to update and delete events while operating incrementally. Change data feed exposes row-level change types and versions, making it the correct mechanism for streaming only the relevant changes from an SCD Type 1 table maintained with AUTO CDC INTO.
NEW QUESTION # 161
......
The online version of Certified-Data-Engineer-Professional study materials are based on web browser usage design and can be used by any browser device. The first time you open Certified-Data-Engineer-Professional study materials on the Internet, you can use it offline next time. Certified-Data-Engineer-Professional study materials do not need to be used in a Wi-Fi environment, and it will not consume your traffic costs. You can practice with Certified-Data-Engineer-Professional study materials at anytime, anywhere. On the other hand, the online version has a timed and simulated exam function. You can adjust the speed and keep vigilant by setting a timer for the simulation test. At the same time online version of Certified-Data-Engineer-Professional Study Materials also provides online error correction—Through the statistical reporting function, it will help you find the weak links and deal with them. Of course, you can also choose two other versions. The contents of the three different versions of Certified-Data-Engineer-Professional study materials are the same and all of them are not limited to the number of people/devices used at the same time.
Certified-Data-Engineer-Professional Book Free: https://www.pdf4test.com/Certified-Data-Engineer-Professional-dump-torrent.html
- Formats of www.verifieddumps.com Updated Certified-Data-Engineer-Professional Exam Practice Questions 🙇 Simply search for ➤ Certified-Data-Engineer-Professional ⮘ for free download on ( www.verifieddumps.com ) 🚝Exam Sample Certified-Data-Engineer-Professional Questions
- Popular Certified-Data-Engineer-Professional Exam Materials Can Help You Pass the Exam Successful - Pdfvce 🏦 Open { www.pdfvce.com } and search for ➽ Certified-Data-Engineer-Professional 🢪 to download exam materials for free 🃏Certified-Data-Engineer-Professional Reliable Test Answers
- Reliable Certified-Data-Engineer-Professional Test Tutorial 🦕 Certified-Data-Engineer-Professional Latest Dumps Pdf 🦯 Reliable Study Certified-Data-Engineer-Professional Questions 🐼 Download ➠ Certified-Data-Engineer-Professional 🠰 for free by simply searching on ▷ www.examcollectionpass.com ◁ 🎂Certified-Data-Engineer-Professional Certification Training
- Formats of Pdfvce Updated Certified-Data-Engineer-Professional Exam Practice Questions 📁 Search for ➠ Certified-Data-Engineer-Professional 🠰 and easily obtain a free download on ✔ www.pdfvce.com ️✔️ 📈Certified-Data-Engineer-Professional Valid Exam Camp
- Quiz Updated Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Latest Training 😾 ⇛ www.prepawayexam.com ⇚ is best website to obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download 🧆New Certified-Data-Engineer-Professional Exam Bootcamp
- Certified-Data-Engineer-Professional Latest Dumps Pdf 💠 Reliable Certified-Data-Engineer-Professional Braindumps Ebook 🎤 Latest Certified-Data-Engineer-Professional Braindumps Free 🍋 Open 【 www.pdfvce.com 】 enter “ Certified-Data-Engineer-Professional ” and obtain a free download 🤓Reliable Certified-Data-Engineer-Professional Braindumps Ebook
- Formats of www.prepawaypdf.com Updated Certified-Data-Engineer-Professional Exam Practice Questions 🦆 Download ▷ Certified-Data-Engineer-Professional ◁ for free by simply entering “ www.prepawaypdf.com ” website 🧭Certified-Data-Engineer-Professional Excellect Pass Rate
- Certified-Data-Engineer-Professional Excellect Pass Rate 🆕 Certified-Data-Engineer-Professional Exam Bootcamp 🤖 Certified-Data-Engineer-Professional Valid Exam Camp 📼 Copy URL ▷ www.pdfvce.com ◁ open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🕐Certified-Data-Engineer-Professional Practice Test Pdf
- Valuable Certified-Data-Engineer-Professional Feedback 🦓 Latest Certified-Data-Engineer-Professional Exam Practice ⛹ Latest Certified-Data-Engineer-Professional Exam Practice 🕓 Open website ⏩ www.troytecdumps.com ⏪ and search for ✔ Certified-Data-Engineer-Professional ️✔️ for free download 🙅Certified-Data-Engineer-Professional Valid Exam Camp
- Quiz Updated Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Latest Training 🎼 Simply search for 【 Certified-Data-Engineer-Professional 】 for free download on ➽ www.pdfvce.com 🢪 ↖Certified-Data-Engineer-Professional Valid Exam Camp
- Certified-Data-Engineer-Professional Latest Dumps Pdf 🦀 Reliable Certified-Data-Engineer-Professional Test Tutorial 🏊 Certified-Data-Engineer-Professional Exam Bootcamp 🎼 Simply search for “ Certified-Data-Engineer-Professional ” for free download on ⮆ www.dumpsquestion.com ⮄ 🚎Certified-Data-Engineer-Professional Practice Test Pdf
- poi-australia.com.au, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
BTW, DOWNLOAD part of PDF4Test Certified-Data-Engineer-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1DPVDo0ZeMBU74leVbSm_MxUfCcKZlxlU