그리고 KoreaDumps NCP-AII 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1l_s70dkhl3p5cCGqJx_cyfUdYXoHjolY
우리KoreaDumps 사이트에NVIDIA NCP-AII관련자료의 일부 문제와 답 등 문제들을 제공함으로 여러분은 무료로 다운받아 체험해보실 수 있습니다. 여러분은 이것이야 말로 알맞춤이고, 전면적인 여러분이 지금까지 갖고 싶었던 문제집이라는 것을 느끼게 됩니다.
| Certification Vendor: | NVIDIA |
|---|---|
| Exam Name: | NVIDIA Certified Professional – AI Infrastructure |
| Exam Number: | NCP-AII |
| Exam Duration: | 90 minutes |
| Exam Price: | $195 USD |
| Real Exam Qty: | 50 |
| Certificate Validity Period: | 2 years |
| Passing Score: | 700 (scale of 0-1000) |
| Exam Format: | Multiple Select, Multiple Choice |
| Available Languages: | English |
| Related Certifications: | NCP-AI NCP-DES |
| Sample Questions: | NVIDIA NCP-AII Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: hands-on experience with NVIDIA AI infrastructure products; basic knowledge of Linux, networking, and data center operations |
| Official Syllabus URL: | https://www.nvidia.com/en-us/certifications/ncp-ai-infra/ |
KoreaDumps에서는 시장에서 가장 최신버전이자 적중율이 가장 높은 NVIDIA인증 NCP-AII덤프를 제공해드립니다. NVIDIA인증 NCP-AII덤프는 IT업종에 몇십년간 종사한 IT전문가가 실제 시험문제를 연구하여 제작한 고품질 공부자료로서 시험패스율이 장난 아닙니다. 덤프를 구매하여 시험에서 불합격성적표를 받으시면 덤프비용 전액을 환불해드립니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
질문 # 194
An engineer needs to validate NVLink Switch functionality on a DGX H100 system with 8 GPUs. Which NCCL command verifies intra-node NVLink bandwidth?
정답:C
설명:
The NVIDIA Collective Communications Library (NCCL) "Tests" are used to verify the maximum achievable bandwidth of the interconnects. On a DGX H100, the GPUs are connected via a dedicated high- bandwidthNVLink Switch fabric(NVLink 4), which provides significantly higher throughput than PCIe. To validate the intra-node (within a single server) performance, the all_reduce_perf test is used. The command in Option D is specifically designed to stress all 8 GPUs (-g 8) across a wide range of message sizes (8 bytes to
16G). The use of the environment variable NCCL_TESTS_SPLIT with the bitwise "OR" or "AND" masks allows the engineer to isolate specific traffic patterns or groups of GPUs to ensure the NVLink switches are distributing the load evenly. For a standard 8-GPU H100 tray, achieving a "Bus Bandwidth" of ~450 GB/s to
900 GB/s (depending on the precision and message size) confirms that the NVLink fabric is operating at its theoretical peak. Using only 4 GPUs (Option B) or 1 GPU (Option C) would not provide a complete picture of the NVLink switch bisection bandwidth.
질문 # 195
You're debugging performance issues in a distributed training job. 'nvidia-smi' shows consistently high GPU utilization across all nodes, but the training speed isn't increasing linearly with the number of GPUs. Network bandwidth is sufficient. What is the most likely bottleneck?
정답:A,B,D,E
설명:
If GPUs are highly utilized but scaling is poor, the bottleneck is likely not GPU compute itself. Inefficient data pipelines mean GPUs spend time idle waiting for data. Suboptimal NCCL configurations result in communication overhead negating the benefit of more GPUs. Incorrect learning rate with larger batch size will impact covergence. Batch sizes can affect convergence and model effectiveness. While CUDA Graphs improves performance, the other answers are more pertinent to the question.
질문 # 196
An enterprise builds a Kubernetes-based AI platform using NVIDIA GPU Operator. After adding several new GPU nodes, administrators notice that NVIDIA drivers, container runtime components, and monitoring agents are installed automatically without manual intervention.
Which capability of GPU Operator enables this behavior?
정답:D
설명:
GPU Operator simplifies Kubernetes deployments by managing GPU drivers, the NVIDIA Container Toolkit, device plugins, DCGM exporters, and related software as Kubernetes resources. This automates installation, upgrades, and lifecycle management across the cluster. It does not configure BIOS settings or perform virtual machine migration.
질문 # 197
A media company is developing an AI platform for video content analysis that requires storing and processing large volumes of unstructured video data. The platform must support high throughput for data ingestion and provide efficient access for real-time analytics. Given these requirements, which storage strategy should the company implement?
정답:D
설명:
Object storage is best suited for large volumes of unstructured video data because it scales efficiently, supports high-throughput ingestion, and uses rich metadata to organize and retrieve content for analytics workflows. This makes it a strong fit for AI-based video analysis and real- time data access patterns.
질문 # 198
During BCM cluster setup, an engineer must configure bonded network interfaces on DGX nodes for high availability. Which cmsh command sequence properly configures a bond0 interface with two physical NICs?
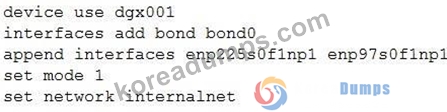
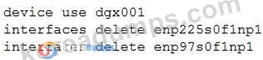
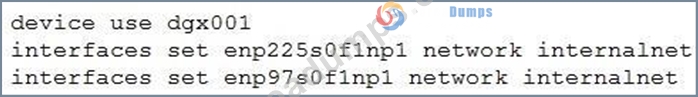
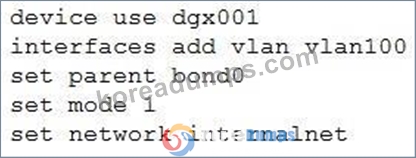
정답:A
설명:
In BCM cmsh, a bonded interface is created by adding a bond interface, appending the two physical NICs as bond members, setting the bonding mode, and assigning the bond to the appropriate network. This configures bond0 with the two physical interfaces for high availability on the internal network.
질문 # 199
......
NCP-AII완벽한 시험공부자료: https://www.koreadumps.com/NCP-AII_exam-braindumps.html
참고: KoreaDumps에서 Google Drive로 공유하는 무료 2026 NVIDIA NCP-AII 시험 문제집이 있습니다: https://drive.google.com/open?id=1l_s70dkhl3p5cCGqJx_cyfUdYXoHjolY