BTW, DOWNLOAD part of PassCollection AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=1VQDLDLxttThjY3sgWulW_IYhyEG_Eio-
A PassCollection support team is on hand to help AI-103 exam applicants use the Microsoft AI-103 practice tests and address any problems. The goal is to help candidates crack the AI-103 exam in one go. Free Microsoft AI-103 demo and up to 1 year of free Microsoft AI-103 Questions are also available at PassCollection. So, start preparation with real Developing AI Apps and Agents on Azure (AI-103) questions right away if you wish to pass the test while saving time and money.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement generative AI solutions | 25-30% | - Develop generative AI applications
|
| Topic 2: Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
| Topic 3: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Topic 4: Implement agentic solutions | 20-25% | - Build AI agents
|
| Topic 5: Implement computer vision solutions | 10-15% | - Analyze visual content
|
>> Accurate AI-103 Prep Material <<
On the basis of the current social background and development prospect, the AI-103 certifications have gradually become accepted prerequisites to stand out the most in the workplace. Our AI-103 exam materials are pleased to serve you as such an exam tool to help you dream come true. With over a decade's endeavor, our AI-103 practice materials successfully become the most reliable products in the industry. There is a great deal of advantages of our AI-103 exam questions you can spare some time to get to know.
NEW QUESTION # 31
You have a Microsoft Foundry project that contains an agent. The agent uses Azure Al Search as the retriever.
You plan to ingest PDFs into an Azure Al Search index to ensure that the agent can ground responses in texts in both documents and embedded images.
Users require citations that link to the source files.
You need to ensure that during indexing, the images are extracted into a structure that can be used as input for the built-in optical character recognition (OCR) skill.
Which indexing approach should you use?
Answer: D
Explanation:
The correct indexing approach is to use an indexer to extract image data into a normalized_images collection . In Azure AI Search enrichment pipelines, embedded images in PDFs are not passed directly from the text content field into OCR. Instead, the indexer must perform document cracking and image extraction by enabling the indexer image action. Microsoft's Azure AI Search documentation states that image-processing skills such as OCR and image analysis expect normalized images, and that enabling imageAction causes embedded images to be extracted and normalized for downstream skills.
The OCR skill is designed to receive image input from /document/normalized_images/*. Microsoft's skillset tutorial specifically states that the OCR skill assumes a normalized_images field exists and that this field is generated by setting the indexer imageAction configuration to generateNormalizedImages. The document extraction skill reference also confirms that generateNormalizedImages creates an array of normalized images during document cracking for OCR and image analysis.
Option A is incorrect because OCR does not run directly against the index content field. Option B maps outputs after enrichment; it does not extract images. Option D reshapes data but does not create the required normalized image collection. Reference topics: Azure AI Search indexers, AI enrichment, OCR skill, imageAction, and normalized_images.
NEW QUESTION # 32
You have a Microsoft Foundry project that contains a customer support agent built by using the Foundry Agent Service.
The agent uploads user-provided screenshots to Azure Storage through a ticketing tool and receives a blob URL for additional reasoning.
You need to use image moderation during agent runs and prevent harmful content from being returned during runs. Azure Al Content Safety must access the images by using the blob URL. The solution must follow the principle of least privilege.
What should you configure for Content Safety? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.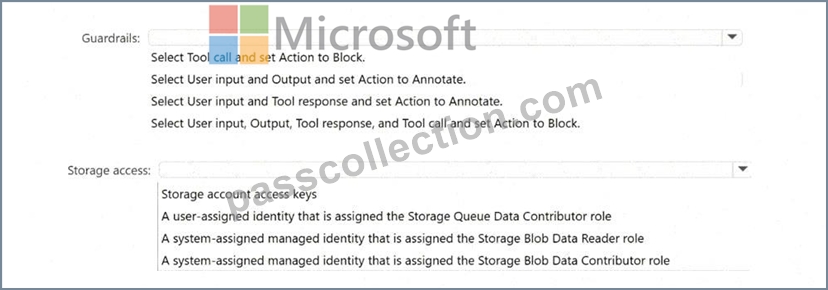
Answer:
Explanation: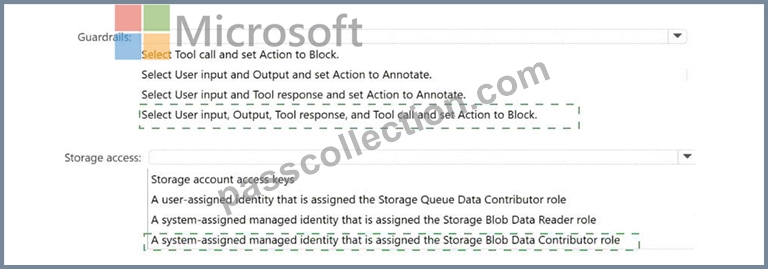
Explanation:
Guardrails: Select User input, Output, Tool response, and Tool call and set Action to Block.
Storage access: A system-assigned managed identity that is assigned the Storage Blob Data Contributor role The guardrail must be applied to User input, Output, Tool response, and Tool call with the action set to Block . Microsoft Foundry guardrails support four intervention points: user input, tool call, tool response, and output. This scenario includes user-provided screenshots, a ticketing tool that uploads images and returns blob URLs, and final agent responses. Applying blocking controls at all four points ensures harmful image-related content is inspected throughout the agent run and prevented from continuing or being returned to the user.
Microsoft's guardrails guidance also states that tool call and tool response controls are specifically required when harmful content can pass through agent tools.
For storage, configure the Azure AI Content Safety resource with a system-assigned managed identity and grant it Storage Blob Data Contributor on the storage account or container. The Content Safety image moderation quickstart states that images can be supplied by blob storage URL and that the Content Safety resource must be given storage access by enabling its system-assigned managed identity and assigning Storage Blob Data Contributor or Owner; Contributor is the least-privileged valid option shown. Reference topics: Foundry guardrails, agent intervention points, image moderation, managed identity, and Azure Storage RBAC.
NEW QUESTION # 33
You have a web app named App1 that sends requests to a multimodal chat model deployment in a Microsoft Foundry project. User messages can contain both text and images. Currently, App1 includes image URLs as plain text inside the message content, so the model cannot recognize them as images. You need to send the message as a structured array that includes both the text portion and the image reference.
Answer: B
Explanation:
A vision-enabled Chat Completions request must represent the user message as a multimodal content array.
One item contains the prompt with " type " : " text " , while another contains the image reference with " type ": " image_url " and an image_url.url property:
" content " : [
{ " type " : " text " , " text " : " Analyze this image. " },
{ " type " : " image_url " , " image_url " : { " url " : " < image-url > " }}
]
This structure explicitly identifies each modality, allowing the deployed model to route the text and image through the appropriate processing paths. A URL embedded in an ordinary string remains text and is not interpreted as visual input. Microsoft's documented Chat Completions schema shows the text and image objects inside the user message's content array.
Request metadata does not define model input, and a system message should contain behavioral instructions rather than the user's image attachment. Base64 images are supported, but the encoded value must be formatted as a data URL and supplied through the structured image item-not inserted into a plain content string.
Study Guide alignment: deploy and consume multimodal models, integrate generative workflows into applications, and design multimodal-understanding workflows .
NEW QUESTION # 34
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a multimodal AI generative model that accepts image uploads and uses extracted image text to generate responses.
You discover that users can upload unsafe images and embed hidden instructions into images to manipulate the model.
You need to implement controls to mitigate the risk.
Solution: You configure a prompt shield for user prompts.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You configure a prompt shield for documents.
Prompt Shield for Documents: Highly Effective (Critical Defense)
How it helps: This shield specifically scans untrusted, third-party data inputs (like external documents or text extracted from uploaded images).
Mechanism: It evaluates the extracted image text before it is sent to the LLM to identify hidden jail
* You configure a prompt shield for user prompts.
Prompt Shield for User Prompts: Partially Effective (Defense in Depth)
How it helps: This shield targets direct jailbreak attempts written manually by the user in the text prompt field accompanying the upload.
Mechanism: It prevents the user from typing supporting instructions that prime the model to execute the hidden instructions found within the image.
* You configure image moderation to block unsafe content before processing the images.
Implementing rigorous image moderation is one of the most effective ways to secure multimodal AI systems against these threats. Moderation acts as a necessary gatekeeper, preventing malicious inputs from ever reaching the generative model.
Incorrect:
* You configure protected material detection.
Protected Material Detection: Ineffective for this Threat
Why it does not help: This feature is designed to scan model outputs to prevent the generation of copyrighted text, proprietary source code, or licensed imagery.
Limitation: It does not scan inputs for adversarial instructions and will not prevent a user from manipulating the model's logic.
Reference:
https://www.upgrad.com/blog/what-is-multimodal-ai/
https://learn.microsoft.com/en-us/azure/ai-services/content-safety/concepts/jailbreak-detection
NEW QUESTION # 35
An agent must call your organisation's internal inventory system, which is exposed as a set of tools. You want the tool definitions maintained centrally and reusable across several agents rather than redefined in each agent. Which Foundry capability fits?
Answer: D
Explanation:
A Model Context Protocol (MCP) server exposes a reusable, centrally maintained set of tools that any agent can connect to, and Foundry Agent Service supports adding MCP servers from the tools catalogue. This is the standard pattern for connecting agents to external systems through shared tool definitions.
NEW QUESTION # 36
......
Although our company has designed the best and most suitable AI-103 learn prep, we also do not stop our step to do research about the study materials. All experts and professors of our company have been trying their best to persist in innovate and developing the AI-103 test training materials all the time in order to provide the best products for all people and keep competitive in the global market. We believe that the study materials will keep the top selling products. We sincerely hope that you can pay more attention to our AI-103 study questions.
AI-103 Real Exam: https://www.passcollection.com/AI-103_real-exams.html
BTW, DOWNLOAD part of PassCollection AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=1VQDLDLxttThjY3sgWulW_IYhyEG_Eio-