P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by FreeCram: https://drive.google.com/open?id=16LxwSg5PROBGpfTX0YdrGcfnbKoHeZYd
FreeCram is aware that in today’s routines many Developing AI-Enabled Database Solutions DP-800 exam candidates are under time pressures. Therefore, FreeCram offers Microsoft Exams questions in three formats that are DP-800 desktop practice test software, web-based practice test, and PDF dumps. These formats of our Developing AI-Enabled Database Solutions DP-800 updated exam study material give you multiple training options so that you can meet your Microsoft DP-800 exam preparation objectives. Keep reading because we have discussed the specifications of FreeCram DP-800 exam questions preparation material in three user-friendly formats.
| Section | Weight | Objectives |
|---|---|---|
| Implement AI capabilities in database solutions (25–30%) | 25-30% | - Integrate Azure AI services
|
| Design and develop database solutions (35–40%) | 35-40% | - Implement data management
|
| Secure, optimize, and deploy database solutions (35–40%) | 35-40% | - Implement data platform resources
|
>> Latest Test Microsoft DP-800 Simulations <<
As usual, you just need to spend little time can have a good commend of our study materials, then you can attend to your DP-800 exam and pass it at your first attempt. We also hire a team of experts, and the content of DP-800 question torrent is all high-quality test guidance materials that have been accepted by experienced professionals. DP-800 practice materials will be the most professional and dedicated tutor you have ever met.
NEW QUESTION # 38
You have an Azure SQL database that supports an OLTP application.
You need to write Transact-SQL code that returns blocking chain details. The output must return only sessions that ate blocked or are blocking other sessions.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.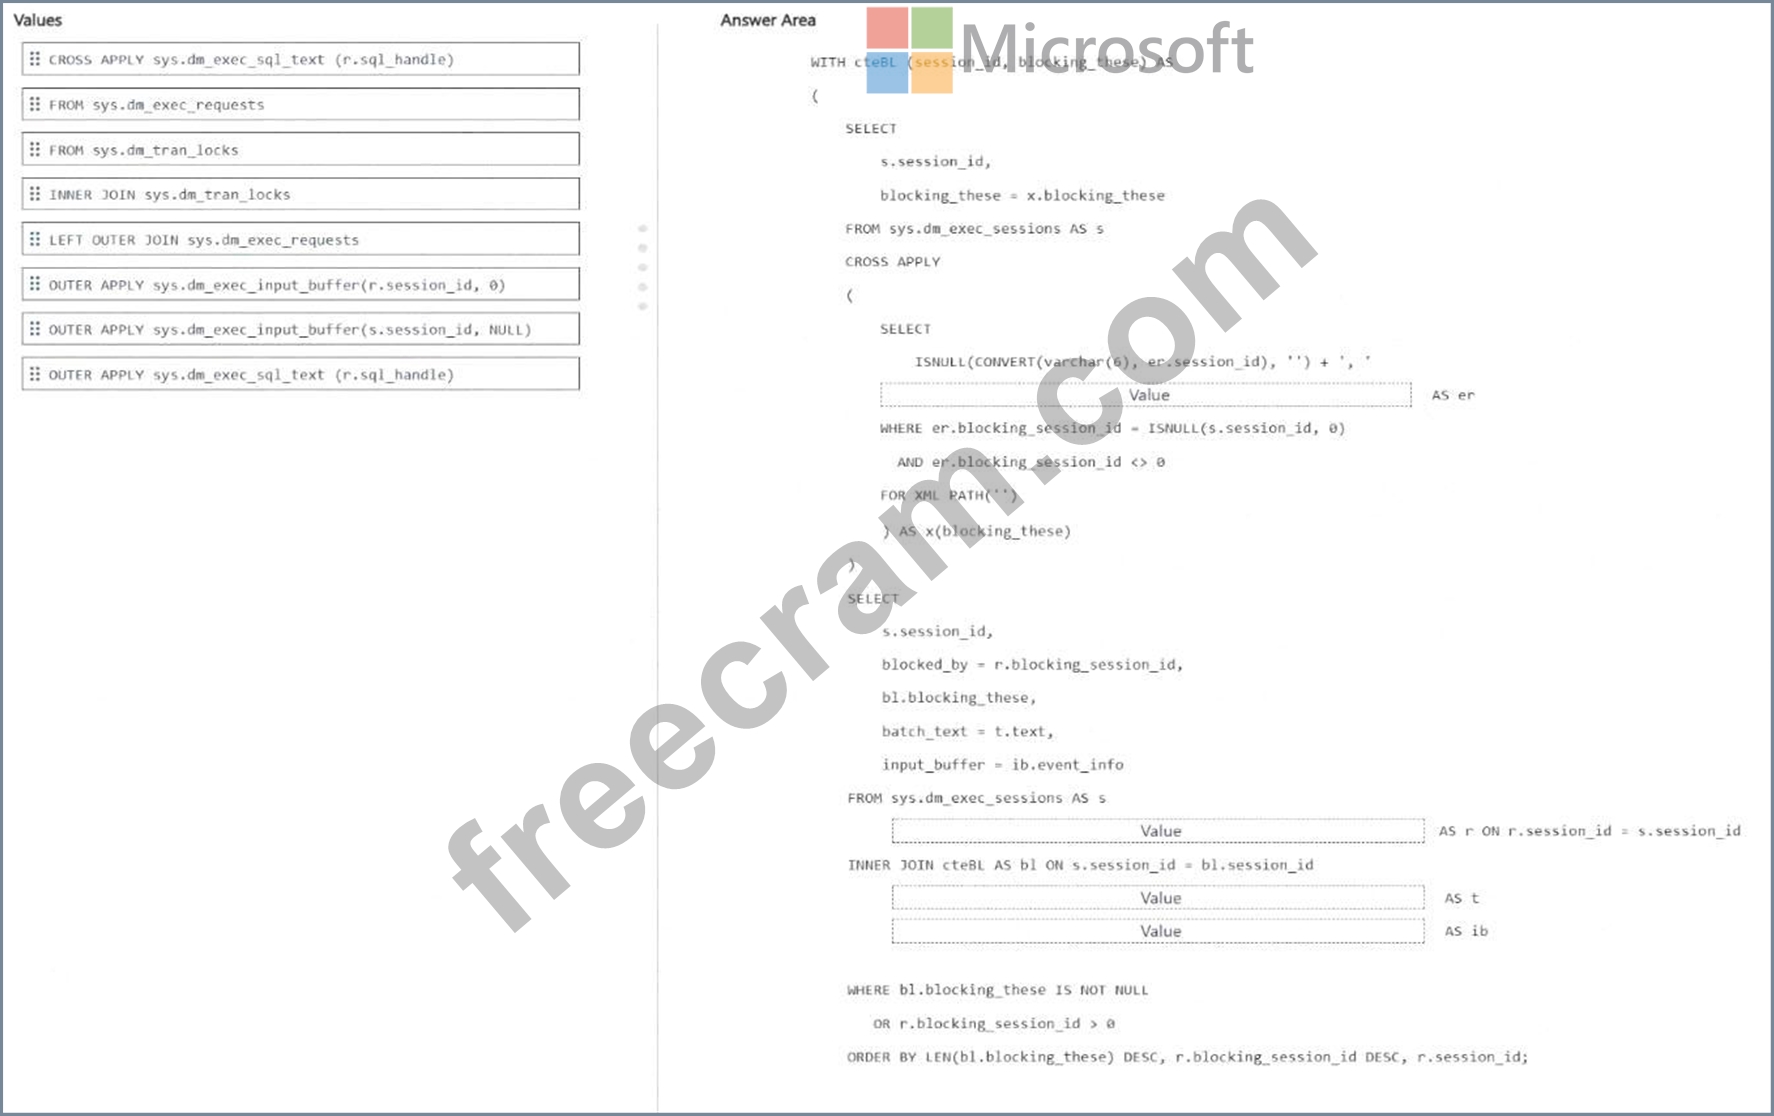
Answer:
Explanation: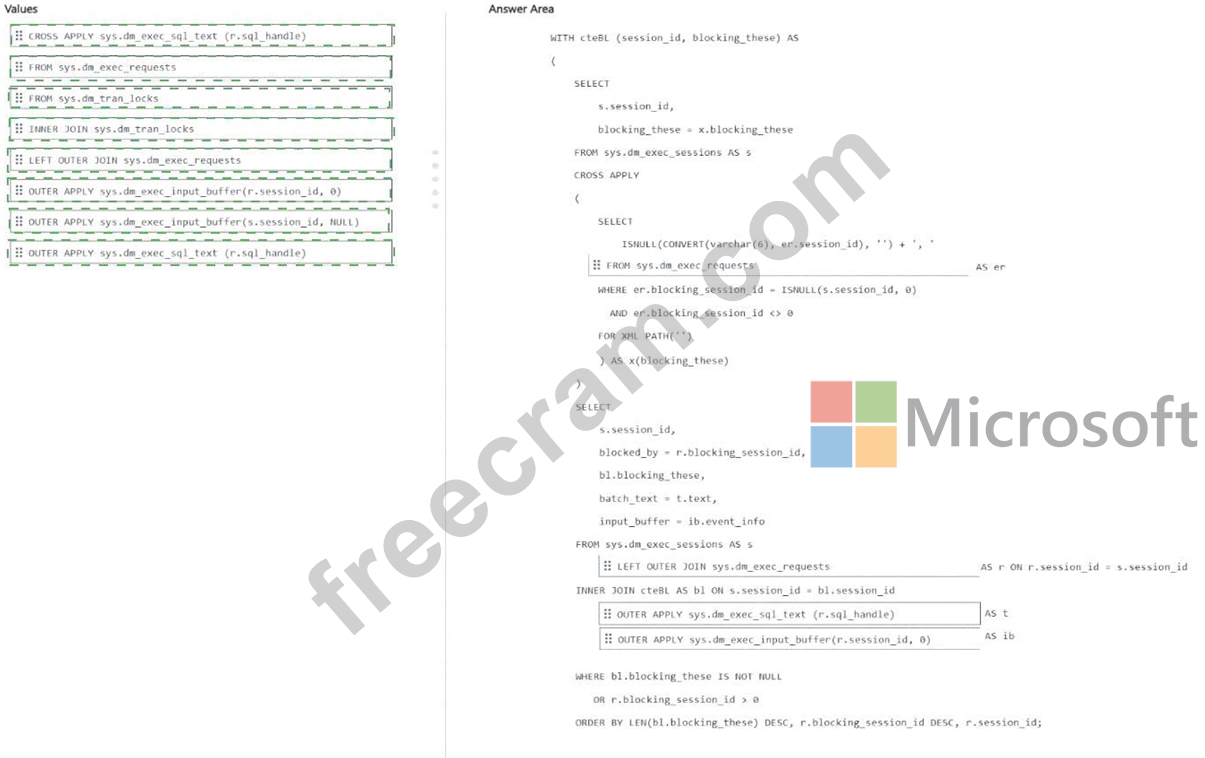
Explanation:
* CTE inner source # FROM sys.dm_exec_requests
* Join after sys.dm_exec_sessions AS s # LEFT OUTER JOIN sys.dm_exec_requests
* Text retrieval # OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* Input buffer retrieval # OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) The correct drag-and-drop choices are based on how blocking-chain details are normally assembled in Azure SQL Database.
The CTE must read from sys.dm_exec_requests because the alias er is used with er.session_id and er.
blocking_session_id, and those columns come from sys.dm_exec_requests. Microsoft documents that sys.
dm_exec_requests returns information about executing requests and includes the blocking_session_id column used to identify blockers.
After FROM sys.dm_exec_sessions AS s, the correct join is LEFT OUTER JOIN sys.dm_exec_requests so the query can still return sessions from sys.dm_exec_sessions even when a current request row is missing.
This is useful when showing sessions that are blocked or blocking, while still attempting to attach current request details when available.
For batch text, use OUTER APPLY sys.dm_exec_sql_text(r.sql_handle) because Microsoft documents sys.
dm_exec_sql_text(sql_handle) as the function that returns the SQL batch text for the specified sql_handle.
For the input buffer, use OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id) because Microsoft documents that sys.dm_exec_input_buffer takes session_id and request_id and returns event_info, which is commonly used when sys.dm_exec_sql_text is null or when you want the last command text.
So the completed code uses:
* FROM sys.dm_exec_requests
* LEFT OUTER JOIN sys.dm_exec_requests
* OUTER APPLY sys.dm_exec_sql_text(r.sql_handle)
* OUTER APPLY sys.dm_exec_input_buffer(r.session_id, r.request_id)
NEW QUESTION # 39
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
Answer: C
Explanation:
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector (1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
* A would require manual comparison logic and would increase latency rather than minimize it.
* B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
* C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft's current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam- aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
NEW QUESTION # 40
You have an Azure SQL database named sqldb-ai-prod that stores customer support tickets for a multitenant software as a service (SaaS) application. sqldb-ai-prod contains a table named Tickets. Tickets contains columns named TenantId, TicketId, CustomerEmail, CustomerPhone, and Notes.
You plan to harden data access, since a new support team will use ad hoc reporting tools that connect directly to sqldb-ai-prod.
You need to configure security to meet the following requirements:
* Support agents must see only the rows of their own TenantId column.
* Support agents must see only the domain name portion of the CustomerEmail column.
What should you do for each requirement? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.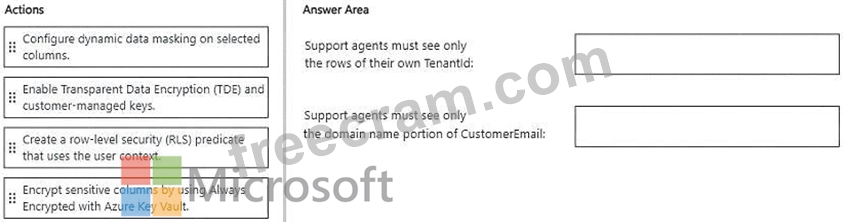
Answer:
Explanation: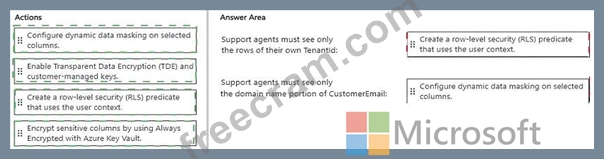
Explanation:
Verified Answer : =
* Support agents must see only the rows of their own TenantId # Create a row-level security (RLS) predicate that uses the user context.
* Support agents must see only the domain name portion of CustomerEmail # Configure dynamic data masking on selected columns.
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = For the TenantId requirement, use Row-Level Security (RLS) . RLS is designed to restrict which rows a database principal can access. A security predicate can compare the row ' s TenantId with tenant information derived from the current user ' s session or security context, so support agents querying the same Tickets table see only rows belonging to their own tenant. This is the correct multitenant isolation mechanism because it is enforced by the database rather than relying on individual reporting tools or application-side filtering.
For CustomerEmail , use Dynamic Data Masking (DDM) . DDM controls how sensitive column values are displayed to users who do not have UNMASK permission. A partial masking rule can conceal the local/user- specific portion of an email address while exposing only the required portion, such as its domain, according to the masking configuration.
The remaining choices do not satisfy these specific requirements. Transparent Data Encryption (TDE) protects database files at rest but does not filter rows or selectively obscure query results. Always Encrypted protects sensitive values cryptographically and is appropriate when the database engine itself should not see plaintext, but it is not the right mechanism when support agents must deliberately see a controlled portion of an email address.
Final drag-and-drop selections:
* Own TenantId rows # Create a row-level security (RLS) predicate that uses the user context
* Only domain portion of CustomerEmail # Configure dynamic data masking on selected columns
NEW QUESTION # 41
Your company has an ecommerce catalog in a Microsoft SQL Server 202b database named SalesDB SalesDB contains a table named products, products contains the following columns:
* product.id (int)
* product_name (nvarchar(200))
* description (nvarchar(max))
* category (nvarchar(50))
* brand (nvarchar(W))
* price (decimal)
* sku (nvarchar(40))
The description fields ate updated dairy by a content pipeline, and price can change multiple times per day.
You want customers to be able to submit natural language queries and apply structured filters for brand and price. You plan to store embeddings in a new VECTOR(1536) column and use VECTOR_SEARCH(...
METRIC=' cosine ' ...).
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.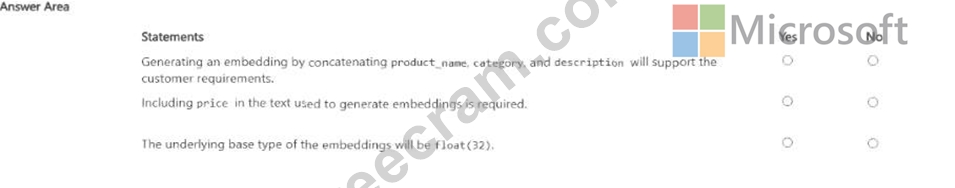
Answer:
Explanation: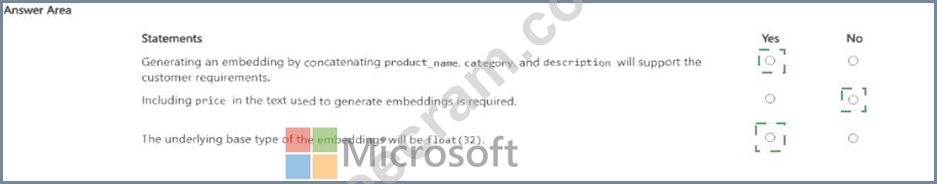
Explanation: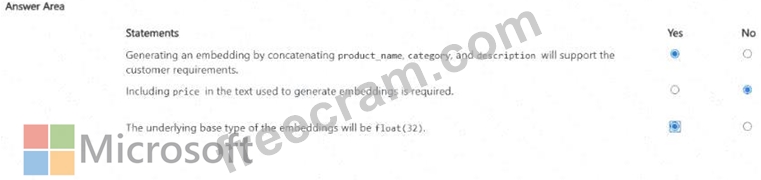
The first statement is Yes . Embeddings are used to represent the semantic meaning of content, and vector search is for conceptually similar matches over that content. Here, the semantically meaningful fields are product_name, category, and description. Using those together supports natural-language search, while brand and price can be handled as structured filters outside the embedding itself. This is an inference from Microsoft's guidance that vector search works over embeddings representing content meaning, while filters remain part of the nonvector query pipeline.
The second statement is No . price changes multiple times per day and is a structured numeric attribute, not stable semantic content. Since the requirement already says customers can apply structured filters for brand and price , price does not need to be embedded into the text. Embedding volatile numeric values would also make embeddings stale faster without improving the semantic-search objective. This is again an inference grounded in Microsoft's distinction between vector similarity over content and filtering/sorting over nonvector fields.
The third statement is Yes . In SQL Server's vector type, the default underlying base type is float32 unless float16 is specified explicitly.
NEW QUESTION # 42
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.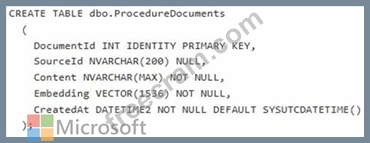
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.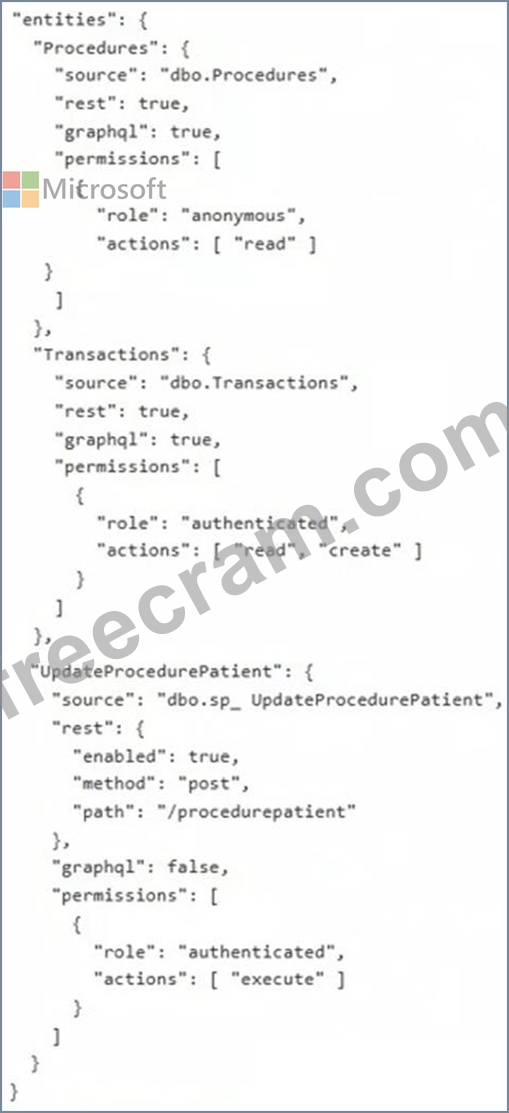
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
Answer: D
Explanation:
Scenario: Fabrikam identifies the following AI-related requirements: Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
To remedy data retrieval delays in a Retrieval Augmented Generation (RAG) pattern using Reciprocal Rank Fusion (RRF) on an Azure SQL Database table, you should use embeddings.
In a RAG architecture, retrieval delays often stem from inefficient or computationally heavy search processes. While RRF is excellent for merging results from multiple sources (like combining keyword and vector searches), the core of the speed problem typically lies in how the initial data is indexed and retrieved.
Role of Embeddings
Vector Search Acceleration: Embeddings convert text into high-dimensional vectors. Azure SQL Database can perform similarity searches on these vectors much faster than complex semantic text matching.
Hybrid Search Synergy: RRF is most effective when it fuses results from a keyword search (fast) and a vector search (powered by embeddings). Using embeddings ensures that the "semantic" side of the retrieval is streamlined.
Pre-computation: Since embeddings are generated once during ingestion, the retrieval phase only requires a distance calculation (e.g., Cosine Similarity), which is significantly faster than real- time natural language parsing during each query.
Reference:
https://pratikbarjatya.medium.com/unlocking-the-power-of-language-with-retrieval-augmented- generation-rag-14123cc275e6
NEW QUESTION # 43
......
Learning with our DP-800 learning guide is quiet a simple thing, but some problems might emerge during your process of DP-800 exam materials or buying. Considering that our customers are from different countries, there is a time difference between us, but we still provide the most thoughtful online after-sale service on DP-800 training guide twenty four hours a day, seven days a week, so just feel free to contact with us through email anywhere at any time. Our commitment of helping you to pass DP-800 exam will never change.
Examinations DP-800 Actual Questions: https://www.freecram.com/Microsoft-certification/DP-800-exam-dumps.html
DOWNLOAD the newest FreeCram DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=16LxwSg5PROBGpfTX0YdrGcfnbKoHeZYd