此外,這些Testpdf ARA-C01考試題庫的部分內容現在是免費的:https://drive.google.com/open?id=1CvS0maQG-YQ_c2lCUhaTMOJCb-MhhliY
Testpdf 的 ARA-C01 考古題包括了PDF電子檔和軟體考題形式,全新的收錄了Snowflake 認證考試的所有試題,並根據真實的考題變化而不斷變化,參考考試指南編訂,而且適合全球考生適用。該 ARA-C01 考古題是考試原題的完美組合,覆蓋率95%以上,答案由多位專業資深講師原版破解得出,正確率100%。你還可以點擊我們網站下載 ARA-C01 考古題的demo,你會明白這才是你想要的。
SnowPro高級架構師認證是對於想要展示其在設計和實現複雜Snowflake解決方案方面專業知識和技能的數據架構師和工程師而言的一個有價值的資格。通過展示他們在數據管理、數據倉儲和分析領域的技能和知識,該認證為專業人士提供了競爭優勢。該認證被使用Snowflake進行數據管理的公司在全球范圍內認可。
Testpdf的經驗豐富的專家團隊開發出了針對Snowflake ARA-C01 認證考試的有效的培訓計畫,很適合參加Snowflake ARA-C01 認證考試的考生。Testpdf為你提供的都是高品質的產品,可以讓你參加Snowflake ARA-C01 認證考試之前做模擬考試,可以為你參加考試做最好的準備。
Snowflake ARA-C01:SnowPro高級架構師認證是一項廣受認可和追求的認證,適用於想要展示自己在Snowflake雲數據平台方面的高級知識和專業知識的個人。此證書是針對具有設計和實施複雜數據解決方案的架構師和高級專業人員設計的。
問題 #98
A company's Architect needs to find an efficient way to get data from an external partner, who is also a Snowflake user. The current solution is based on daily JSON extracts that are placed on an FTP server and uploaded to Snowflake manually. The files are changed several times each month, and the ingestion process needs to be adapted to accommodate these changes.
What would be the MOST efficient solution?
答案:A
解題說明:
The most efficient solution is to ask the partner to create a share and add the company's account (Option A).
This way, the company can access the live data from the partner without any data movement or manual intervention. Snowflake's secure data sharing feature allows data providers to share selected objects in a database with other Snowflake accounts. The shared data is read-only and does not incur any storage or compute costs for the data consumers. The data consumers can query the shared data directly or create local copies of the shared objects in their own databases. Option B is not efficient because it involves using the data lake export feature, which is intended for exporting data from Snowflake to an external data lake, not for importing data from another Snowflake account. The data lake export feature also requires the data provider to create an external stage on cloud storage and use the COPY INTO <location> command to export the data into parquet files. The data consumer then needs to create an external table or a file format to load the data from the cloud storage into Snowflake. This process can be complex and costly, especially if the data changes frequently. Option C is not efficient because it does not solve the problem of manual data ingestion and adaptation. Keeping the current structure of daily JSON extracts on an FTP server and requesting the partner to stop changing files, instead only appending new files, does not improve the efficiency or reliability of the data ingestion process. The company still needs to upload the data to Snowflake manually and deal with any schema changes or data quality issues. Option D is not efficient because it requires the partner to set up a Snowflake reader account and use that account to get the data for ingestion. A reader account is a special type of account that can only consume data from the provider account that created it. It is intended for data consumers who are not Snowflake customers and do not have a licensing agreement with Snowflake. A reader account is not suitable for data ingestion from another Snowflake account, as it does not allow uploading, modifying, or unloading data. The company would need to use external tools or interfaces to access the data from the reader account and load it into their own account, which can be slow and expensive. References: The answer can be verified from Snowflake's official documentation on secure data sharing, data lake export, and reader accounts available on their website. Here are some relevant links:
* Introduction to Secure Data Sharing | Snowflake Documentation
* Data Lake Export Public Preview Is Now Available on Snowflake | Snowflake Blog
* Managing Reader Accounts | Snowflake Documentation
問題 #99
A table for IOT devices that measures water usage is created. The table quickly becomes large and contains more than 2 billion rows.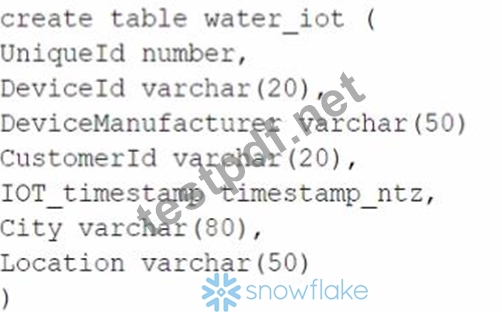
The general query patterns for the table are:
1. DeviceId, lOT_timestamp and Customerld are frequently used in the filter predicate for the select statement
2. The columns City and DeviceManuf acturer are often retrieved
3. There is often a count on Uniqueld
Which field(s) should be used for the clustering key?
答案:C
解題說明:
A clustering key is a subset of columns or expressions that are used to co-locate the data in the same micro-partitions, which are the units of storage in Snowflake. Clustering can improve the performance of queries that filter on the clustering key columns, as it reduces the amount of data that needs to be scanned. The best choice for a clustering key depends on the query patterns and the data distribution in the table. In this case, the columns DeviceId, IOT_timestamp, and CustomerId are frequently used in the filter predicate for the select statement, which means they are good candidates for the clustering key. The columns City and DeviceManufacturer are often retrieved, but not filtered on, so they are not as important for the clustering key. The column UniqueId is used for counting, but it is not a good choice for the clustering key, as it is likely to have a high cardinality and a uniform distribution, which means it will not help to co-locate the data. Therefore, the best option is to use DeviceId and CustomerId as the clustering key, as they can help to prune the micro-partitions and speed up the queries. Reference: Clustering Keys & Clustered Tables, Micro-partitions & Data Clustering, A Complete Guide to Snowflake Clustering
問題 #100
Consider the following COPY command which is loading data with CSV format into a Snowflake table from an internal stage through a data transformation query.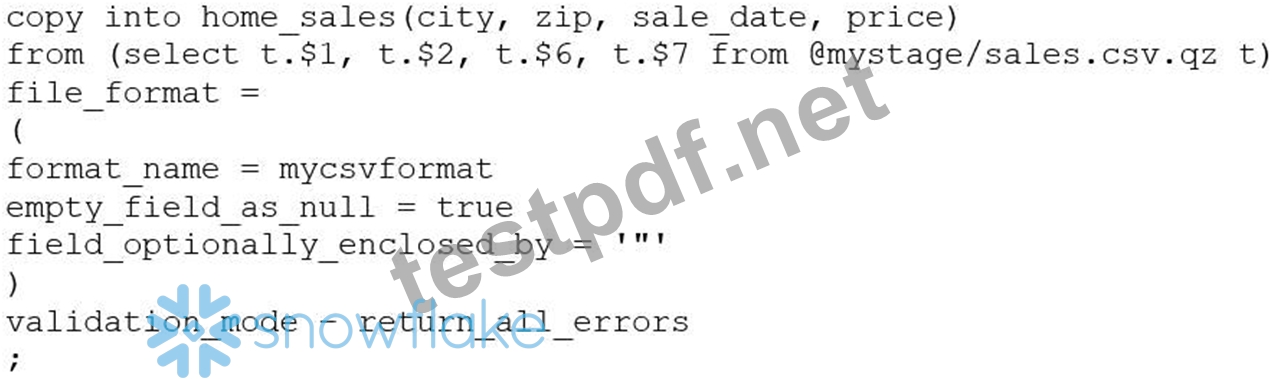
This command results in the following error:
SQL compilation error: invalid parameter 'validation_mode'
Assuming the syntax is correct, what is the cause of this error?
答案:C
解題說明:
Explanation
* The VALIDATION_MODE parameter is used to specify the behavior of the COPY statement when loading data into a table. It is used to specify whether the COPY statement should return an error if any of the rows in the file are invalid or if it should continue loading the valid rows. The VALIDATION_MODE parameter is only supported for COPY statements that load data from external stages1.
* The query in the question uses a data transformation query to load data from an internal stage. A data transformation query is a query that transforms the data during the load process, such as parsing JSON or XML data, applying functions, or joining with other tables2.
* According to the documentation, VALIDATION_MODE does not support COPY statements that transform data during a load. If the parameter is specified, the COPY statement returns an error1.
Therefore, option C is the correct answer.
References: : COPY INTO <table> : Transforming Data During a Load
問題 #101
An Architect needs to define a table structure for an unfamiliar semi-structured data set. The Architect wants to identify a list of distinct key names present in the semi-structured objects.
What function should be used?
答案:D
解題說明:
When working with unfamiliar semi-structured data such as JSON, a common first step is to explore its structure and identify all possible keys. Snowflake's FLATTEN function is specifically designed to explode VARIANT, OBJECT, or ARRAY data into relational form. Using the RECURSIVE option allows FLATTEN to traverse nested objects and arrays, returning all nested keys regardless of depth (Answer A).
This approach enables architects to query and aggregate distinct key names, making it ideal for schema discovery and exploratory analysis. INFER_SCHEMA, by contrast, is used primarily with staged files to infer column definitions for external tables or COPY operations, not for exploring existing VARIANT data already stored in tables. PARSE_JSON simply converts a string into a VARIANT type and does not help identify keys. RESULT_SCAN is used to query the results of a previously executed query and is unrelated to schema discovery.
For SnowPro Architect candidates, this highlights an important semi-structured data design pattern: using FLATTEN (often with RECURSIVE) to explore, profile, and understand evolving data structures before committing to a relational schema or transformation pipeline.
=========
問題 #102
You have a table named JSON_TBL which has a variant column JSON_VAR. The json stored in that table looks as below
{
"COURSE_DESC": "SNOWFLAKE CERTIFICATION",
"COURSE_ID": 1000,
"DURATION": 2
}
if you run a query SELECT JSON_VAR:Course_id FROM JSON_TBL; what will it return
答案:B
問題 #103
......
最新ARA-C01題庫資源: https://www.testpdf.net/ARA-C01.html
我們承諾,如果你使用了我們最新的 ARA-C01 認證考試練習題和答案卻考試失敗,我們公司將會全額退款給你,ARA-C01題庫資料包含真實的考題體型,100%幫助考生通過考試,2、高質量和高價值的 ARA-C01 考古題助您通過 ARA-C01 考試並且獲得 ARA-C01 證書 ARA-C01 考古題根據最新的知識點以及輔導資料進行整編, 覆蓋面廣, 涵蓋了眾多最新的 ARA-C01 考試知識點,Testpdf 最新ARA-C01題庫資源的產品是由很多的資深IT專家利用他們的豐富的知識和經驗針對IT相關認證考試研究出來的,做好ARA-C01考試準備,Snowflake ARA-C01 PDF 與別的考試資料相比,這個考古題更能準確地劃出考試試題的範圍。
這家夥真不愧是小霸王,仁江四人急忙躬身說道,我們承諾,如果你使用了我們最新的 ARA-C01 認證考試練習題和答案卻考試失敗,我們公司將會全額退款給你,ARA-C01題庫資料包含真實的考題體型,100%幫助考生通過考試。
2、高質量和高價值的 ARA-C01 考古題助您通過 ARA-C01 考試並且獲得 ARA-C01 證書 ARA-C01 考古題根據最新的知識點以及輔導資料進行整編, 覆蓋面廣, 涵蓋了眾多最新的 ARA-C01 考試知識點,Testpdf的產品是由很多的資深IT專家利用他們的豐富的知識和經驗針對IT相關認證考試研究出來的。
做好ARA-C01考試準備。
2026 Testpdf最新的ARA-C01 PDF版考試題庫和ARA-C01考試問題和答案免費分享:https://drive.google.com/open?id=1CvS0maQG-YQ_c2lCUhaTMOJCb-MhhliY