P.S. Free & New DP-800 dumps are available on Google Drive shared by iPassleader: https://drive.google.com/open?id=1x50mVaTsazK_ggblVjC7-tdREe7_jUEF
DP-800 Preparation materials will be the good helper for your qualification certification. We are concentrating on providing high-quality authorized DP-800 study guide all over the world so that you can clear exam one time. DP-800 reliable exam bootcamp materials contain three formats: PDF version, Soft test engine and APP test engine so that our products are enough to satisfy different candidates' habits and cover nearly full questions & answers of the real test.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Available Languages: | English |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Exam Format: | Case studies, Multiple choice |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
>> DP-800 Reliable Braindumps Free <<
With the best quality of DP-800 braindumps pdf from our website, getting certified will be easier and fast. For the preparation of the certification exam, all you have to do is choose the most reliable DP-800 real questions and follow our latest study guide. You can completely rest assured that our DP-800 Dumps Collection will ensure you get high mark in the formal test. You will get lots of knowledge from our website.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 16
Drag and Drop Question
You have an Azure SQL database that stores sales data and contains tables named Sales and Products. Sales contains three columns named SalesDate, ProductKey, and TotalSale, Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales, filter on SalesDate or ProductKey, and use SUM() to aggregate TotalSale.
Products is relatively small and is used primarily for point lookups and joins to Sales.
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: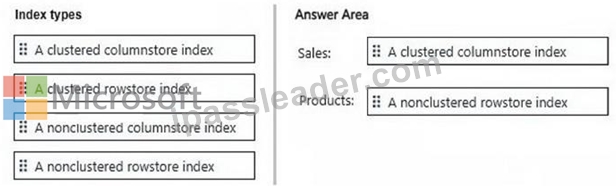
NEW QUESTION # 17
You have an Azure SQL database that stores sales data and contains tables named Sales and Products . Sales contains three columns named SalesDate , ProductKey , and TotalSale .
Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales , filter on SalesDate or ProductKey , and use SUM() to aggregate TotalSale .
Products is relatively small and is used primarily for point lookups and joins to Sales .
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: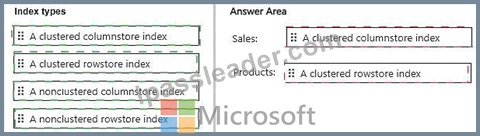
Explanation:
* Sales # A clustered columnstore index
* Products # A clustered rowstore index
For Sales , the correct choice is a clustered columnstore index . Microsoft identifies clustered columnstore indexes as the standard storage choice for large fact tables and analytical/data-warehouse workloads . The Sales table is 10 TB, loaded in nightly batches, and its reporting queries scan large portions of the table and perform aggregations such as SUM(TotalSale) . Those are exactly the workload characteristics that benefit from columnstore storage, batch-mode execution, aggregate pushdown, and high compression. Microsoft also notes that clustered columnstore indexes can provide substantial storage reduction compared with traditional uncompressed rowstore structures, which directly supports the requirement to minimize storage requirements .
For Products , the correct choice is a clustered rowstore index . Microsoft states that rowstore B-tree indexes perform best for point lookups, equality searches, and small-range retrieval , whereas columnstore is optimized for large analytical scans. Since Products is relatively small and primarily supports point lookups and joins to Sales , a rowstore structure is the better fit.
A nonclustered columnstore index would retain the underlying rowstore and add another compressed copy of selected columns, increasing storage. That is more appropriate for real-time analytics over an OLTP table, not for this dedicated large analytical fact table.
NEW QUESTION # 18
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.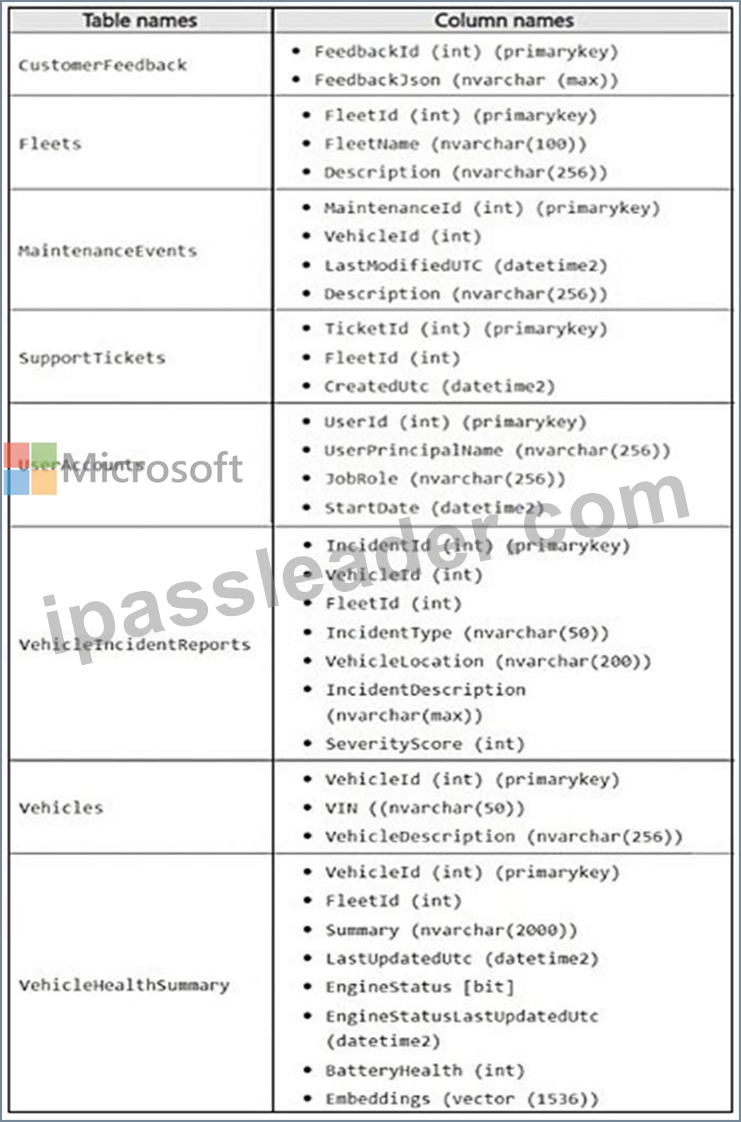
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.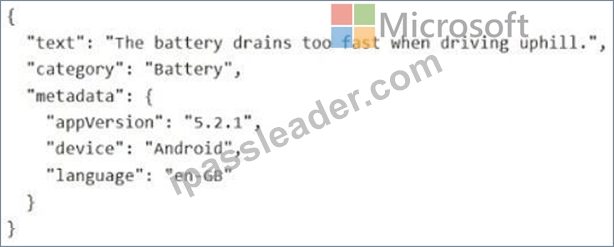
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.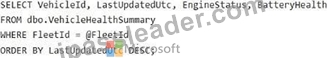
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
Answer: C
Explanation:
Scenario: Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
To retrieve live metadata from Azure SQL databases and use it with GitHub Copilot in Visual Studio Code (VS Code), you must use the SQL Server (mssql) extension. This extension provides the native capability to extract a database schema as a .dacpac file directly within the editor.
1. Export the Schema as a .dacpac File
You can extract the schema of your live Azure SQL database using the SQL Server (mssql) extension.
2. Load the .dacpac into GitHub Copilot Context
Once the .dacpac file is saved in your VS Code workspace, you can provide it as context to GitHub Copilot Chat using #-mentions or Drag & Drop.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/data-tier- applications/extract-dacpac-from-database
NEW QUESTION # 19
You have a SQL database in Microsoft Fabric that contains a column named Payload. Payload stores customer data in JSON documents that have the following format.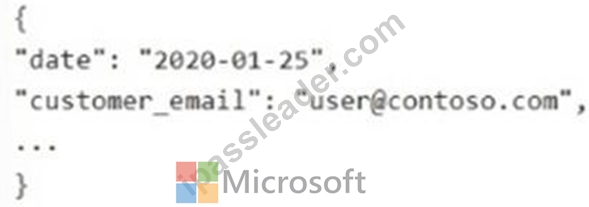
Data analysis shows that some customers have subaddressing in their email address, for example, user1+promo@contoso.com.
You need to return a normalized email value that removes the subaddressing, for example, user1
+promo@contoso.com must be normalized to user1@contoso.com.
Which Transact-SQL expression should you use?
P.S. Free & New DP-800 dumps are available on Google Drive shared by iPassleader: https://drive.google.com/open?id=1x50mVaTsazK_ggblVjC7-tdREe7_jUEF