How can we occupy a place in a market where talent is saturated? The answer is a certificate. All kinds of the test certificationS, prove you through all kinds of qualification certificate, it is not hard to find, more and more people are willing to invest time and effort on the Databricks-Certified-Professional-Data-Engineer exam guide, because get the test Databricks-Certified-Professional-Data-Engineer Certification is not an easy thing, so, a lot of people are looking for an efficient learning method. And here, fortunately, you have found the Databricks-Certified-Professional-Data-Engineer exam braindumps, a learning platform that can bring you unexpected experiences.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 2: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Topic 3: Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Topic 4: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Topic 5: Data Ingestion | 15-20% | - Streaming ingestion
|
>> Databricks-Certified-Professional-Data-Engineer Free Updates <<
In this way, you cannot miss a single Databricks-Certified-Professional-Data-Engineer exam question without an answer. One more thing to give you an idea about the top features of Databricks Certified Professional Data Engineer Exam exam questions before purchasing, the TestPassed are offering a Free Databricks-Certified-Professional-Data-Engineer Exam Questions demo download facility. This facility is being offered in all three Databricks Certified Professional Data Engineer Exam exam question formats. Just choose the right Databricks-Certified-Professional-Data-Engineer exam questions format demo and download it quickly.
NEW QUESTION # 190
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of
512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
Answer: D
Explanation:
The key to efficiently converting a large JSON dataset to Parquet files of a specific size without shuffling data lies in controlling the size of the output files directly.
* Setting spark.sql.files.maxPartitionBytes to 512 MB configures Spark to process data in chunks of
512 MB. This setting directly influences the size of the part-files in the output, aligning with the target file size.
* Narrow transformations (which do not involve shuffling data across partitions) can then be applied to this data.
* Writing the data out to Parquet will result in files that are approximately the size specified by spark.sql.files.maxPartitionBytes, in this case, 512 MB.
* The other options involve unnecessary shuffles or repartitions (B, C, D) or an incorrect setting for this specific requirement (E).
References:
* Apache Spark Documentation: Configuration - spark.sql.files.maxPartitionBytes
* Databricks Documentation on Data Sources: Databricks Data Sources Guide
NEW QUESTION # 191
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks documents that shuffle occurs when Spark redistributes data across partitions for grouping or joining. To optimize aggregation performance, repartitioning by the grouping key (region) ensures rows with the same key are co-located in the same partition, thus minimizing shuffle movement. Caching improves reuse of DataFrames but does not reduce shuffle volume. coalesce() reduces the number of partitions after computation and cannot prevent shuffle. Broadcast joins are unrelated to single-table aggregations. The recommended practice for reducing shuffle in aggregation is explicit repartitioning by the grouping column.
NEW QUESTION # 192
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.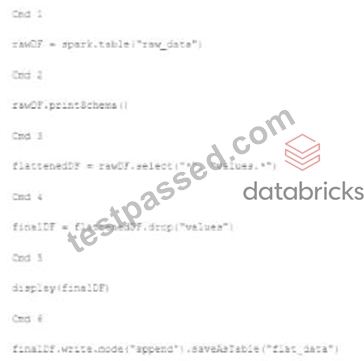
Which command should be removed from the notebook before scheduling it as a job?
Answer: A
Explanation:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
NEW QUESTION # 193
At the end of the inventory process, a file gets uploaded to the cloud object storage, you are asked to build a process to ingest data which of the following method can be used to ingest the data in-crementally, schema of the file is expected to change overtime ingestion process should be able to handle these changes automatically.
Below is the auto loader to command to load the data, fill in the blanks for successful execution of below code.
1.spark.readStream
2..format("cloudfiles")
3..option("_______","csv)
4..option("_______", 'dbfs:/location/checkpoint/')
5..load(data_source)
6..writeStream
7..option("_______",' dbfs:/location/checkpoint/')
8..option("_______", "true")
9..table(table_name))
Answer: E
Explanation:
Explanation
The answer is cloudfiles.format, cloudfiles.schemalocation, checkpointlocation, mergeSchema.
Here is the end to end syntax of streaming ELT, below link contains complete options Auto Loader options | Databricks on AWS
1.spark.readStream
2..format("cloudfiles") # Returns a stream data source, reads data as it arrives based on the trigger.
3..option("cloudfiles.format","csv") # Format of the incoming files
4..option("cloudfiles.schemalocation", "dbfs:/location/checkpoint/") The location to store the inferred schema and subsequent changes
5..load(data_source)
6..writeStream
7..option("checkpointlocation","dbfs:/location/checkpoint/") # The location of the stream's checkpoint
8..option("mergeSchema", "true") # Infer the schema across multiple files and to merge the schema of each file. Enabled by default for Auto Loader when inferring the schema.
9..table(table_name)) # target table
NEW QUESTION # 194
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. Theuser_idfield represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table namedaccount_historywhich maintains a full record of all data in the same schema as the source. The next table in the system is namedaccount_currentand is implemented as a Type 1 table representing the most recent value for each uniqueuser_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the describedaccount_currenttable as part of each hourly batch job?
Answer: E
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 195
......
Now is not the time to be afraid to take any more difficult certification exams. Our Databricks-Certified-Professional-Data-Engineer learning quiz can relieve you of the issue within limited time. Our website provides excellent Databricks-Certified-Professional-Data-Engineer learning guidance, practical questions and answers, and questions for your choice which are your real strength. You can take the Databricks-Certified-Professional-Data-Engineer Training Materials and pass it without any difficulty. As long as you can practice Databricks-Certified-Professional-Data-Engineer study guide regularly and persistently your goals of making progress and getting certificates smoothly will be realized just like a piece of cake.
Vce Databricks-Certified-Professional-Data-Engineer Format: https://www.testpassed.com/Databricks-Certified-Professional-Data-Engineer-still-valid-exam.html